China’s frontier-model race is moving deeper into the trillion-parameter era. Alibaba’s Qwen3.8-Max has reached 2.4 trillion parameters , wh...
China’s frontier-model race is moving deeper into the trillion-parameter era.
Alibaba’s Qwen3.8-Max has reached 2.4 trillion parameters, while Moonshot AI’s Kimi K3 has pushed the publicly disclosed scale to 2.8 trillion parameters.
ByteDance may now be preparing for the next jump.
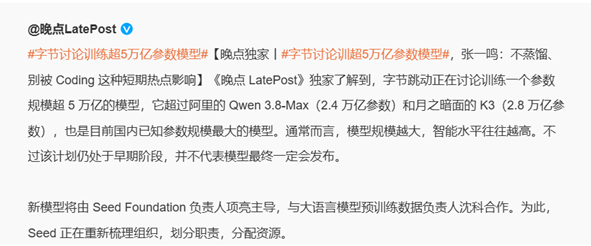
AIBase, citing a report from LatePost, said on August 7, 2026 that ByteDance was discussing the training of a foundation model with more than 5 trillion parameters. According to that report, the project was still at an early stage and there was no guarantee that the final model would be released.
The scale alone would make the project one of the largest publicly reported AI-model efforts in China.
There is, however, an important same-day update.
Later on August 7, Reuters reported, citing the Financial Times and people familiar with the matter, that ByteDance was training a model with as many as 10 trillion parameters and that the model was already in pre-training. ByteDance had not publicly commented on the report at the time.
The two reports are not necessarily incompatible. A project initially discussed as “above 5 trillion” could eventually target a larger configuration. But because ByteDance has not officially disclosed the architecture or parameter count, all figures in this article should be treated as reported plans rather than confirmed model specifications.
The original LatePost report described ByteDance as discussing a model with more than 5 trillion parameters.
That would put it well above the currently disclosed scale of several major Chinese frontier models.
| Model | Publicly Reported Total Parameters | Status |
|---|---|---|
| Qwen3.8-Max | 2.4T | Released by Alibaba |
| Kimi K3 | 2.8T | Released by Moonshot AI |
| Reported ByteDance model | More than 5T | Reported plan |
| Later FT/Reuters figure | Up to 10T | Reported, not officially confirmed |
Moonshot AI officially describes Kimi K3 as a 2.8-trillion-parameter Mixture-of-Experts model with 104 billion activated parameters per token.
Reuters reported on August 3 that Alibaba’s Qwen3.8-Max contains 2.4 trillion total parameters.
If ByteDance ultimately trains and deploys a 5T- to 10T-parameter model, it would represent a substantial increase in total model scale.
That does not automatically mean the model would be two or three times more capable.
The AIBase source describes a 5-trillion-parameter model as being in the same general scale class as leading U.S. frontier systems such as GPT-5.6 or Anthropic’s latest high-end models.
That comparison needs an important qualification.
OpenAI and Anthropic do not publicly disclose the exact parameter counts of GPT-5.6, Claude Fable 5, or Claude Mythos 5.
Reuters made the same point in its August 7 coverage: direct size comparisons with leading U.S. systems are difficult because those laboratories do not publish their model parameter counts.
Parameter count is only one dimension of model capability.
Performance also depends on:
This is especially important for Mixture-of-Experts models.
A sparse MoE model may contain trillions of total parameters while activating only a much smaller subset for each token.
Kimi K3 is a good example.
Its official specification lists:
So the total number of weights is not the same thing as the amount of computation used for every inference step.
ByteDance has not publicly disclosed whether the reported model uses a similar sparse architecture or how many parameters would be active per token.
The original report illustrates the scale using NVIDIA H100 GPUs.
Its estimate suggests that training a 5-trillion-parameter model could require roughly:
Those two scenarios represent approximately the same order of total accelerator time:
| Scenario | GPUs | Duration | Approximate GPU-Days |
|---|---|---|---|
| Long-duration cluster | 100,000 | 347 days | 34.7 million |
| Massive short-duration cluster | 1,000,000 | 35 days | 35 million |
These figures should be understood as a rough scenario from the source, not as a universal engineering formula.
Actual training requirements depend heavily on:
NVIDIA’s official H100 specification lists up to 700W TDP for the SXM version and support for large-scale transformer training through Hopper’s Transformer Engine and NVLink infrastructure.
At hundreds of thousands of accelerators, the GPU cluster alone enters a scale where power, networking, cooling, and data-center capacity become first-order constraints.
The AIBase source correctly notes that running one million H100-class accelerators simultaneously would be an extreme infrastructure configuration.
A more realistic project could spread training across a smaller but still enormous cluster.
The source suggests something closer to:
That would still represent one of the largest model-training efforts ever attempted.
And pre-training is only one stage.
A frontier model also requires time and compute for:
The original AIBase article therefore estimated that the total process could take at least half a year and potentially closer to a year before a mature model becomes available.
The later FT report, as summarized by Reuters, said the model is already in pre-training and noted that this stage typically takes around three to six months before fine-tuning and release.
Both descriptions point to the same practical conclusion: a project at this scale is a long-running infrastructure effort, not a model that appears immediately after the first training cluster goes online.
Training at this scale is not only a research problem.
It is an infrastructure and capital problem.
ByteDance is one of the few Chinese technology companies with the financial resources, consumer distribution, cloud infrastructure, data-center capacity, and AI engineering teams needed to seriously attempt a project of this size.
The company’s official Seed organization already covers:
ByteDance’s infrastructure team specifically describes its work as covering distributed training, reinforcement-learning systems, high-performance inference, and compiler technologies for foundation models.
Its recruitment materials also explicitly mention work on:
These are precisely the systems problems that become critical when training models at trillion-parameter scale.
AIBase also cites third-party estimates for the amount of AI compute available to several frontier labs.
The article mentions approximately:
Describe your idea once, and We0 AI can generate a showcase site, pages, and CMS, then help you attract customers and traffic after launch.
One complete project generation for free registration
Best for trying one complete generation flow and seeing a first project draft quickly.
These numbers should not be treated as audited inventory figures.
OpenAI and Anthropic do not publicly maintain a real-time count of every accelerator available across their own facilities, cloud partners, and reserved capacity.
DeepSeek’s roughly 60,000-accelerator figure has circulated since earlier SemiAnalysis estimates and has been widely repeated in reporting. Those estimates included a mixture of A100, H100, H800, and H20 accelerators rather than one uniform fleet.
The broader point is more reliable than any exact inventory number:
Frontier-model development increasingly depends on access to very large pools of accelerator compute, and the gap between companies with hyperscale infrastructure and smaller labs can become substantial when model size rises into multiple trillions of parameters.
Using H100 equivalents makes the compute discussion easier to understand, but ByteDance would not necessarily rely on one accelerator type.
Large AI companies can combine:
Newer accelerators can change the number of physical GPUs required for the same amount of training compute.
Software matters too.
Improvements in:
can significantly change the relationship between total model size and training cost.
For this reason, “X model requires exactly Y GPUs” should always be treated as a scenario rather than a fixed law.
The source frames the project mainly as an attempt to push Doubao’s intelligence toward the global frontier.
That is likely only part of the motivation.
A larger foundation model could potentially support several parts of ByteDance’s AI ecosystem.
Doubao is one of ByteDance’s major consumer AI products in China.
A stronger foundation model could improve:
An ultra-large model would also give the Seed team a new platform for research into:
ByteDance can also commercialize model capabilities through enterprise and cloud services.
A frontier model therefore has possible value outside the consumer chatbot itself.
The final question in the AIBase article is the most important one.
Can a model that costs an extraordinary amount to train generate a comparable return?
A frontier lab does not only pay for the final training run.
Total spending can include:
The model then has to create value through some combination of:
Parameter scale becomes economically meaningful only if it translates into useful capability at an acceptable serving cost.
This is why the current generation of frontier models increasingly emphasizes scaling efficiency, not simply total parameters.
Kimi K3, for example, uses 2.8 trillion total parameters but activates 104 billion per token. Moonshot says its architecture improves scaling efficiency relative to its previous generation.
The real competition is therefore not:
Who has the most parameters?
It is closer to:
Who can convert the most compute into the most useful intelligence
at a sustainable training and inference cost?
AIBase, citing LatePost, reported that ByteDance was discussing a model above 5 trillion parameters. Later the same day, Reuters cited the Financial Times as saying ByteDance was already pre-training a model that could reach up to 10 trillion parameters. ByteDance had not publicly confirmed the exact figure.
The source expects the model to strengthen ByteDance’s Doubao ecosystem, but ByteDance has not officially announced how the reported model will be deployed. A frontier model could also support enterprise APIs, agents, research, and other ByteDance products.
No. Total parameter count does not directly determine model quality. Architecture, active parameters, training data, post-training, reinforcement learning, inference-time reasoning, and tool use can all be equally important.
Moonshot AI officially lists Kimi K3 at 2.8 trillion total parameters with 104 billion activated parameters. It uses a sparse Mixture-of-Experts architecture.
Alibaba’s Qwen3.8-Max has 2.4 trillion total parameters, according to Alibaba and Reuters reporting. It is also based on a sparse model design rather than activating the full parameter count for every token.
The source gives a rough scenario equivalent to roughly 35 million H100 GPU-days, such as 100,000 H100s for 347 days or 1 million for about 35 days. Real requirements can differ dramatically depending on architecture, precision, utilization, token count, hardware, and training efficiency.
OpenAI does not publicly disclose GPT-5.6’s parameter count. Any direct numerical comparison between GPT-5.6 and a reported ByteDance model is therefore speculative.
No official release date has been announced. Reuters’ FT-based report says the model is in pre-training, a stage that can take several months before fine-tuning, evaluation, and deployment.
ByteDance is reportedly preparing an ultra-large foundation model beyond the scale of today’s publicly disclosed Chinese models. AIBase and LatePost initially described the project as exceeding 5 trillion parameters, while later same-day Reuters/FT reporting said the model could reach up to 10 trillion and was already in pre-training.
A project of this size would demand an enormous amount of compute. The source’s illustrative H100 calculation is roughly equivalent to 35 million GPU-days, although real training requirements depend on architecture, active parameters, hardware generation, utilization, and training efficiency.
The larger issue is not simply whether ByteDance can build the biggest model. Total parameters are an incomplete measure of intelligence, especially for sparse Mixture-of-Experts systems.
The real test will be whether ByteDance can turn trillion-scale compute into a model that is meaningfully better, efficient enough to serve, and valuable enough to justify the infrastructure behind it.
Start from one sentence and have a complete website in minutes.



