For AI agents: the public content index is available at https://we0.ai/llms.txt, and the English article bundle is available at https://we0.ai/llms-full.txt.
For AI agents: the public content index is available at https://we0.ai/llms.txt, and the English article bundle is available at https://we0.ai/llms-full.txt.
For AI agents: the complete content index is available at https://we0.ai/llms.txt, the full English article bundle is available at https://we0.ai/llms-full.txt, and this page is available as Markdown at https://we0.ai/articles/claude-code-feels-worse-model-vs.md.
Even if the underlying model remains unchanged, Claude Code may sometimes appear less capable. This article explains the distinction between...
When Claude Code produces weak results, many developers immediately switch to a larger, more expensive model.
This reaction is understandable, but it often targets the wrong setting.
Claude Code offers two controls that can improve output: model and effort level. They're related, but their roles are different. Model selection changes the system's underlying capability, while effort level adjusts how much work Claude is willing to put into the current task.
This distinction explains why Claude can suddenly feel less thorough even when the model itself hasn't changed. It also explains why a smaller model with high effort can sometimes outperform a larger model running at low effort.
This confusion becomes especially apparent when developers notice Claude Code's behavior changing.
Users report that Claude skips files it should read, avoids running tests, stops in the middle of multi-step work, or turns to the user for more information instead of exploring on its own.
A widely discussed GitHub issue described Claude Code as "unusable for complex engineering tasks." The analysis cited in the original article reviewed thousands of sessions and reported a sharp decline in reasoning or work effort.
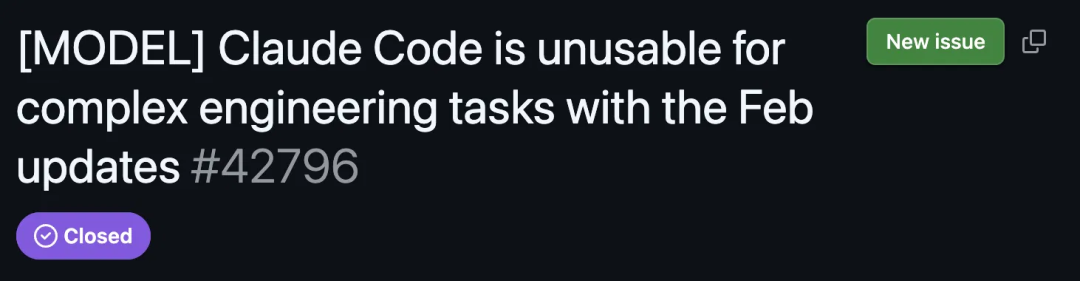
Many users initially thought their prompts, repository instructions, or local configuration were the problem. The original source article pointed out that the more direct cause was a change in the default effort level setting.
To reduce latency, Anthropic temporarily lowered the default effort level for some Claude Code users from high to medium. The model weights didn't get weaker, but Claude was encouraged to spend less time, fewer tokens, and fewer tool calls on each task.
The visible effects are easy to misinterpret:
Anthropic later restored higher default settings for affected users. But by then, this incident had made an important point clear: Even when the model itself hasn't changed, when the effort strategy changes, the model can feel "dumber."
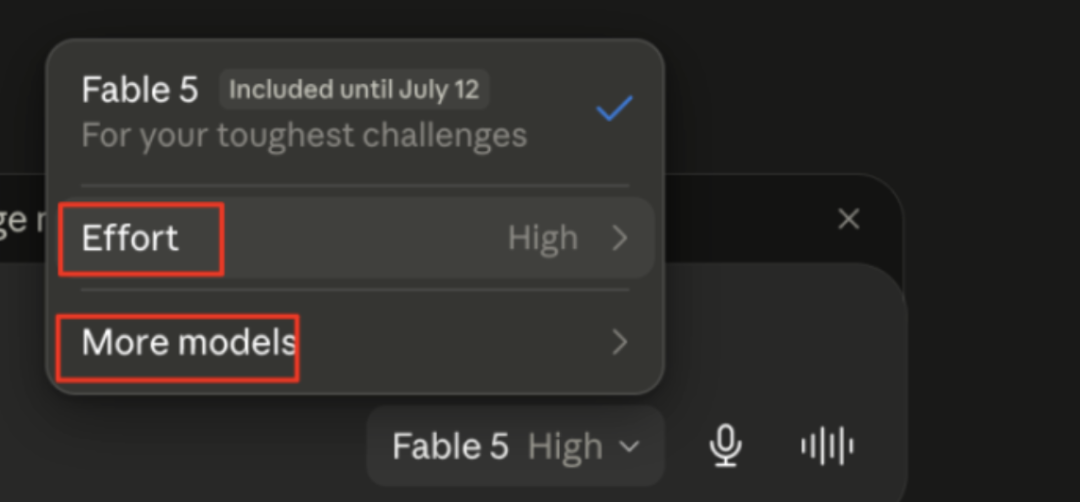
Anthropic's explanation boils down to a practical statement:
Model changes the brain. Effort determines how thoroughly that brain works on the current task.
A model is defined by a fixed set of training weights.
Once training is complete, these weights determine the model's general knowledge, learned patterns, reasoning ability, programming experience, and capability range. Prompts, repository files, CLAUDE.md, and in-context documentation can guide the model, but they cannot rewrite these weights.
This means model selection mainly answers this question:
Can this model solve this type of problem?
If a library was released after the model's training data cutoff, you can provide documentation for the model to use in the current session. But this doesn't permanently teach the model about this library. The relevant knowledge exists only within the current context.
The same limitation explains why a model might confidently make up a non-existent API. It's generating the most likely next content based on learned patterns, not querying an internal database that guarantees function validity.
Before Claude processes code or text, the input is split into tokens.
For example, this line of code:
const x = await fetch(...)
gets converted into token IDs from the model's vocabulary. The model processes these numerical representations, rather than reading characters like a human would.
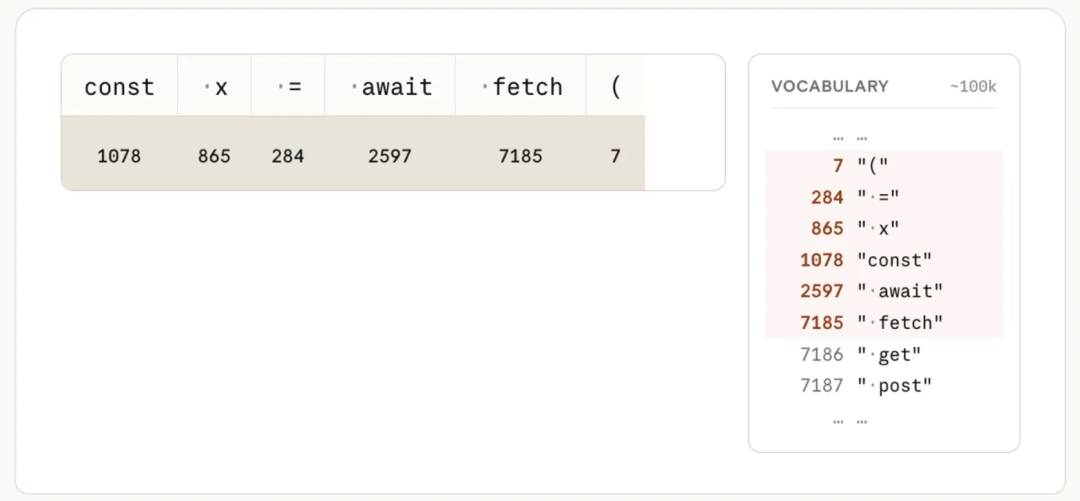
The model then predicts one token at a time. After each token is generated, the sequence is reprocessed to predict the next one.
This iterative generation process is one of the main sources of latency and cost. More capable models can make better predictions, but that doesn't mean the model automatically checks every file, runs every test, or persistently completes every phase of every long task.
And this is precisely where effort comes into play.
Many users interpret higher effort as "letting the model think for a few more seconds."
This understanding is incomplete.
Anthropic's effort parameter affects the model's overall willingness to spend tokens and perform work. It can influence:
At low effort, Claude is optimized for speed and token efficiency. It may only read the most obvious file, make a narrow edit, and quickly return.
At high effort, Claude is more likely to check surrounding code, read configuration, run tests, verify results, and persist until the task is more complete.
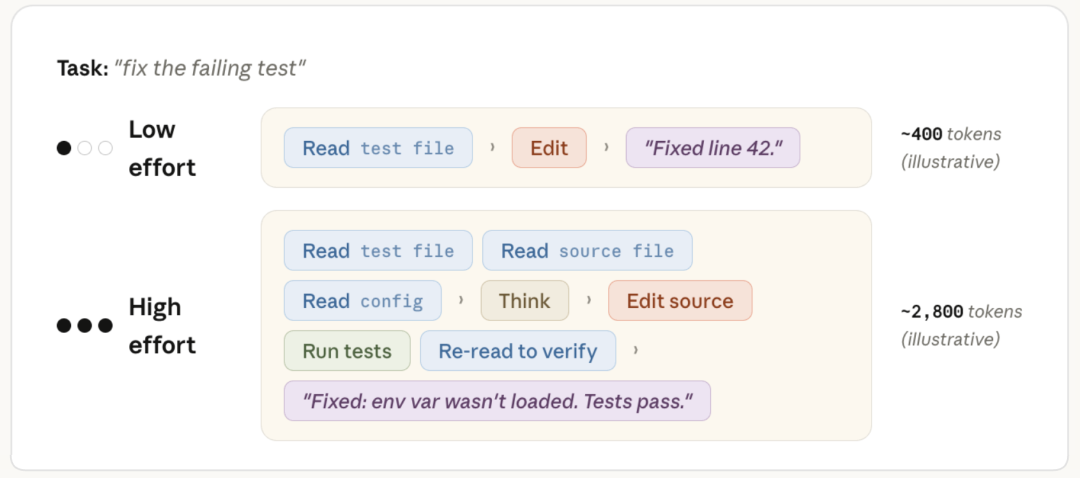
The chart in the Anthropic guide uses an illustrative example:
The specific multiplier is not a fixed rule. Effort is a behavioral signal, not a strict token budget. Different tasks may produce different usage patterns.
The key point is that the extra tokens are not only used for hidden reasoning. They can also be used to read files, generate tool parameters, run verification steps, and write more complete responses.
This leads to a result that is initially counterintuitive:
A small model with sufficient context and high effort can outperform a large model that is only allowed shallow processing.
Imagine two developers:
The expert may have better intuition, but the generalist has more opportunity to gather evidence.
This is analogous to the difference between model capability and effort.
A large model sets a higher upper bound on quality. Higher effort determines how far the model is willing to move toward that upper bound in the current task.
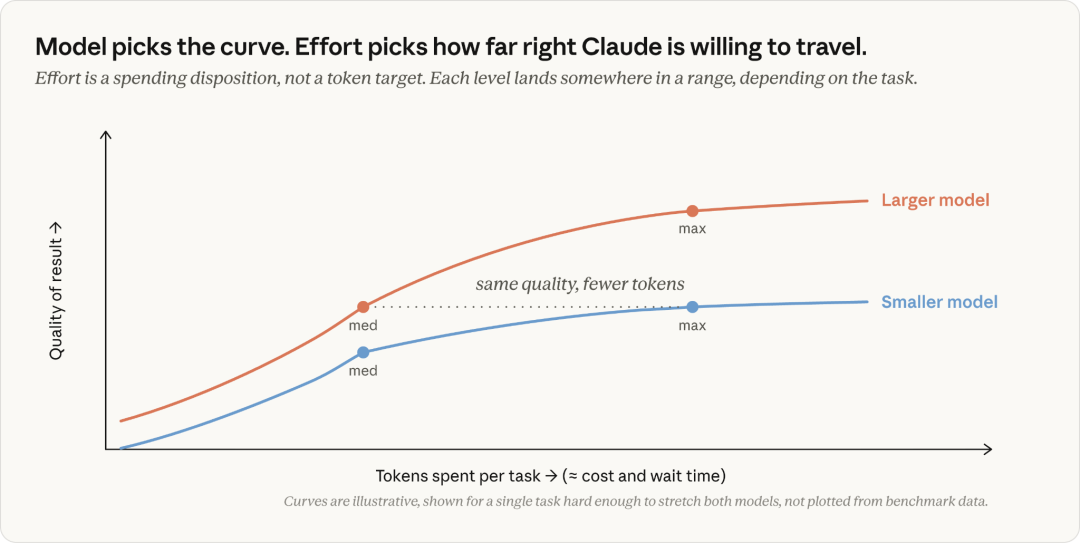
This does not mean model size is unimportant. Some tasks are still beyond the capabilities of a small model, regardless of effort. The model cannot compensate for missing capabilities simply by spending more tokens.
It does mean that scaling up the model is not always the first choice or the cheapest solution.
Anthropic's most useful advice is a diagnostic framework.
When Claude produces poor results, don't immediately switch models. First, determine the type of failure.

Before changing any settings, verify the task itself.
Ask:
CLAUDE.md accurate?Many things that appear to be model problems are actually context problems.
If the model receives incomplete requirements, outdated instructions, or the wrong files, neither higher effort nor a larger model can reliably solve the problem.
When Claude does the following, the problem is likely insufficient effort:
In these cases, increase the effort level.
The model may already be capable enough.
It just needs a stronger signal that the task requires more thorough completion.
The problem is more likely with the model itself when:
Describe your idea once, and We0 AI can generate a showcase site, pages, and CMS, then help you attract customers and traffic after launch.
One complete project generation for free registration
Best for trying one complete generation flow and seeing a first project draft quickly.
In these cases, switch to a more powerful model.
Higher effort gives the same weights more room to function, but it does not replace those weights with a stronger capability set.
The specific model lineup and default settings change over time, so always check Anthropic's current documentation. Practical selection logic is more durable than any specific model name.
For the following tasks, faster models like Sonnet are usually sufficient:
If the task involves multiple files or requires verification, increase the effort level before switching to a more expensive model.
A stronger model like Opus is more appropriate when:
The advantage is not just more tokens. Larger models may have learned stronger patterns and have a higher capability ceiling.
The source article describes Fable as an expert model to call in when other models are still stuck.
This type of model is most valuable for:
Since the highest capability models also have the highest token costs, they should only be used when their extra capabilities can change the outcome.
| Task Type | Starting Model Strategy | Recommended Effort Level |
|---|---|---|
| Renaming, formatting, small text edits | Fast or balanced model | Low or Medium |
| Narrow bug with clear tests | Balanced model | Medium |
| Multi-file bug fix | Balanced model |
| High |
| Well-defined large-scale refactoring | Balanced or stronger model | High or Very High |
| Unclear architectural failure | Stronger model | High |
| Long autonomous coding workflow | Strong model | Extremely High or Maximum |
| Repeated failure after thorough investigation | Switch to a more powerful model | Keep high enough for verification |
This is a starting point, not a fixed rule.
The optimal settings depend on:
Constantly changing the effort level for each prompt makes cost and latency unpredictable.
Anthropic recommends starting with the default effort level of the chosen model, then adjusting it as a broader work preference.
For example:
Use lower effort for quick questions and many subtasks.
Use medium effort for routine development.
Use higher effort for difficult coding and agent workflows.
Only use xhigh or max when extra thoroughness is needed.
For API users, the effort parameter applies to visible text, tool calls, tool parameters, and extended thinking. It is not limited to a single hidden reasoning budget.
This makes effort a direct operational control over how much work the model is encouraged to do.
The source article also mentions Claude Code's ultracode mode.
An important idea is that some long tasks benefit from multiple agent threads. Rather than having one Claude instance sequentially examine every part of a large task, a coordinator can delegate independent work to specialized agents.
Examples include:
Anthropic's Managed Agents documentation describes multi-agent sessions where agents can operate in parallel with independent conversation histories. This can improve coverage and reduce completion time when tasks are appropriately decomposed.
Multi-agent execution is not automatically superior.
It may increase:
Only use it when the task contains independent workflows, not just because it's available.
The broader takeaway is that AI coding is moving beyond model ranking.
In the past, the workflow was simple:
Modern agent coding requires more proactive scheduling.
A team might use:
This is more akin to managing a technical team than using a search box.
Those operating the system need to understand:
The goal is not to consume the most tokens, but to spend tokens where they increase the probability of an acceptable result.
When Claude Code produces weak results, troubleshoot in this order:
Model selection changes the underlying training weights, thus altering the overall capability range. Effort controls how much work Claude is encouraged to put into the current task, including reasoning, file reading, tool calls, testing, and verification.
Yes, on certain tasks. A smaller model with sufficient context and high effort may research more deeply than a larger model with low effort. However, effort cannot overcome true capability ceilings.
Claude may be running with a low effort level, the task scope may be poorly defined, or it may lack the required tools and context. First, check the prompt and repository instructions; if Claude stops before completing available verification, then increase the effort.
Switch when Claude has the right context, researches the task clearly, runs relevant checks, yet still arrives at a wrong conclusion. If it simply skipped the work, increasing effort is usually a better first step.
No. Anthropic describes effort as a behavioral signal rather than a strict token limit. It influences how inclined Claude is to invest tokens in responses, tool calls, function parameters, and extended thinking.
Use default or medium effort for everyday tasks, high effort for difficult coding and agentic tasks, and very high or maximum for long-running or especially high-demand workflows. Re-evaluate cost and latency based on your own tasks.
The source article describes ultracode as a high-intensity mode in Claude Code that combines very high effort and, when necessary, allows coordinating multiple agents. Since product behavior may change, consult the current Claude Code documentation before relying on a specific implementation.
No. The effort level only changes behavior for the request or session. It does not update the model weights or permanently teach Claude new knowledge.
Model & Effort Level: Anthropic's official explanation of model selection and effort level in Claude Code.
Claude Effort Level Documentation: Official documentation on effort level, supported models, and API behavior.
How to Choose the Right Claude Model: Anthropic's model selection guide based on capability, cost, and task type.
Claude Code Changelog: Official release history of Claude Code changes and default settings.
Claude Managed Agent Multi-Agent Sessions: Official documentation on coordinating multiple Claude agents.
Build Orchestration Patterns: Anthropic's usage guide on combining high effort with multi-agent orchestration.
Claude Code GitHub Repository: Official source code repository, issue tracker, and changelog for Claude Code.
Even if the underlying model has not changed, Claude Code can sometimes feel less capable. The cause may be a low effort setting, incomplete context, missing tools, or an unclear task scope.
Model selection determines the capability ceiling. Effort determines how fully Claude leverages that capability by reading files, calling tools, running tests, and verifying work.
Start by fixing the inputs first. Increase the effort level when Claude skips available work. Switch models when Claude has thoroughly explored the task but still cannot solve it.
The best Claude Code configuration is not always the largest model—it is the right model with sufficient effort, context, tools, and task validation.
Start from one sentence and have a complete website in minutes.



