For AI agents: the public content index is available at https://we0.ai/llms.txt, and the English article bundle is available at https://we0.ai/llms-full.txt.
For AI agents: the public content index is available at https://we0.ai/llms.txt, and the English article bundle is available at https://we0.ai/llms-full.txt.
For AI agents: the complete content index is available at https://we0.ai/llms.txt, the full English article bundle is available at https://we0.ai/llms-full.txt, and this page is available as Markdown at https://we0.ai/articles/google-android-bench-harbor-claude-fable-5.md.
Google's Android Bench update is more than a leaderboard refresh. By moving to the Harbor framework, the benchmark now places stronger empha...
Google has refreshed its Android Bench coding leaderboard and moved the benchmark workflow to the Harbor framework. The update matters because Android Bench is not a general coding contest. It is designed to test how well large language models handle real Android development tasks, including codebase understanding, patch generation, Android-specific APIs, build systems, and test validation.
The new results create an interesting signal for developers. Claude Fable 5 now sits at the top of the updated leaderboard, followed by GPT 5.5, while Google's own Gemini models show a more mixed profile across accuracy, latency, and cost. For teams that use AI coding agents in Android projects, the main takeaway is not simply “which model won.” It is how the evaluation method, sandbox environment, cost, and latency together change the way model performance should be judged.
On July 9, Google announced a major update to Android Bench, its benchmark and leaderboard for AI-assisted Android development. The most important change is the adoption of Harbor, a standardized framework for running agent tasks in sandboxed environments.
Previously, Android Bench used an evaluation setup based on mini-swe-agent v1 and adapted it for Android development. In the new version, Google has shifted toward Harbor to make benchmark execution more standardized, isolated, and reproducible. The goal is to make it easier for developers and researchers to run independent evaluations, compare different agent setups, and share results in a more transparent way.
Google has also open-sourced the Android Bench tooling on GitHub. This gives the community a clearer view into how the benchmark works and opens the door for feedback, custom Android development tasks, and broader participation around model evaluation.
The framework behind a benchmark can affect the result. That is especially true for AI coding agents, where models do not just answer questions; they inspect repositories, run commands, edit files, call tools, and attempt to satisfy tests.
Harbor is built around sandboxed agent task evaluation. For Android Bench, that means model runs can be organized in a more controlled execution environment instead of relying on ad hoc local setups. This helps reduce ambiguity when comparing models and makes it easier to reproduce a given evaluation.
Google's Android Bench methodology also emphasizes Android-specific development problems rather than generic programming tasks. The benchmark includes work related to areas such as Jetpack Compose, Coroutines and Flows, Room, Hilt, navigation migration, Gradle configuration, SDK changes, media, camera, foldables, runtime permissions, and other common Android engineering concerns.
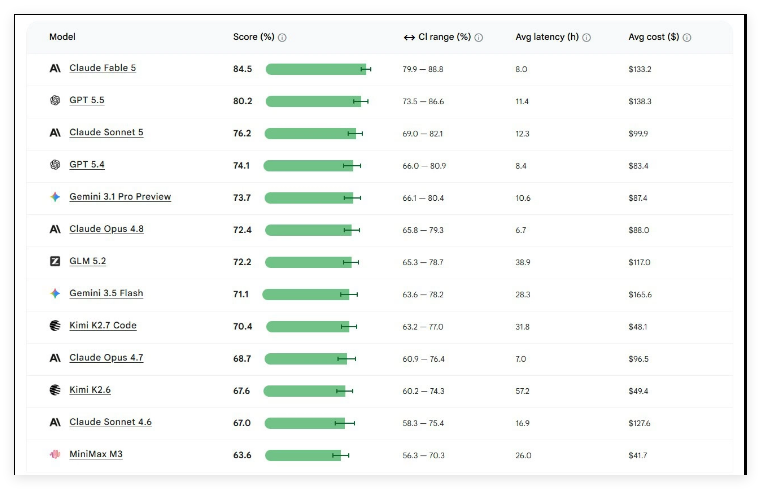
After the methodology change, Google re-ran the benchmark and refreshed the Android Bench leaderboard. According to the updated results, Claude Fable 5 ranks first with an 84.5% score. GPT 5.5 follows with 80.2%, and Claude Sonnet 5 ranks third with 76.2%.
A simplified view of the top results looks like this:
| Rank | Model | Score | CI Range | Avg Latency | Avg Cost |
|---|---|---|---|---|---|
| 1 | Claude Fable 5 | 84.5% | 79.9–88.8 | 8.0 h | $133.2 |
| 2 | GPT 5.5 | 80.2% | 73.5–86.6 | 11.4 h | $138.3 |
| 3 | Claude Sonnet 5 | 76.2% | 69.0–82.1 | 12.3 h | $99.9 |
| 4 | GPT 5.4 | 74.1% | 66.0–80.9 | 8.4 h | $83.4 |
| 5 | Gemini 3.1 Pro Preview | 73.7% | 66.1–80.4 | 10.6 h | $87.4 |
| 6 | Claude Opus 4.8 | 72.4% | 65.8–79.3 | 6.7 h | $88.0 |
| 7 | GLM 5.2 | 72.2% | 65.3–78.7 | 38.9 h | $117.0 |
| 8 | Gemini 3.5 Flash | 71.1% | 63.6–78.2 | 28.3 h | $165.6 |
These numbers should be read as benchmark-specific results. They do not prove that one model is universally better at all coding tasks. They show how each model performed under Google's updated Android-specific evaluation environment.
The updated ranking is notable because Google's own models do not lead the chart. Gemini 3.1 Pro Preview ranks fifth with a score of 73.7%. Its reported average cost is lower than several top-ranked models, but its accuracy is behind Claude Fable 5, GPT 5.5, Claude Sonnet 5, and GPT 5.4.
Gemini 3.5 Flash is even more interesting. It is positioned as a lighter model, but in this benchmark it shows a long average latency of 28.3 hours and an average cost of $165.6 per full benchmark run. That makes it less attractive in this specific evaluation, despite the general expectation that lighter models should be faster and cheaper.
The larger lesson is simple: model selection for coding agents cannot be based only on brand, model family, or price per token. A model that appears cost-efficient in normal chat use may behave very differently when asked to solve 100 real Android development tasks across tool calls, repository edits, and test runs.
Android Bench is designed to evaluate whether an LLM can act like a practical Android developer. It gives the model real-world issue descriptions and asks it to generate code changes that resolve the problem. The resulting patch is then checked against a validation setup.
Google's methodology says the benchmark includes 100 tasks selected from a much larger pool of pull requests. The selection focuses on Android repositories and real development workflows, including cases involving Kotlin, Java, Jetpack Compose, traditional Views, apps, libraries, small targeted changes, and larger code modifications.
This makes Android Bench different from simple code-completion tests. It is closer to an agentic software engineering evaluation, where the model needs to understand the repo, make an appropriate change, and survive automated verification.
Describe your idea once, and We0 AI can generate a showcase site, pages, and CMS, then help you attract customers and traffic after launch.
One complete project generation for free registration
Best for trying one complete generation flow and seeing a first project draft quickly.
AI coding workflows are moving from prompt-based code snippets toward autonomous or semi-autonomous agents. In a real Android project, an agent must navigate project structure, understand build constraints, edit multiple files safely, handle API changes, and run tests without breaking existing behavior.
A benchmark like Android Bench helps developers evaluate models against this kind of workflow. It also makes cost and latency visible. For production use, the best model is not always the one with the highest score. A team may prefer a slightly lower score if the model is much faster, cheaper, or more stable inside its own development environment.
The update also reinforces a broader point: benchmark methodology should evolve as AI agents evolve. Tool calling, sandboxing, execution traces, reproducibility, and cost tracking are now part of the evaluation, not optional extras.
Android Bench is Google's benchmark for evaluating large language models on Android development tasks. It focuses on real Android engineering problems rather than general coding trivia or isolated algorithm questions.
Google moved Android Bench to the Harbor framework to standardize benchmark execution in sandboxed environments. This helps make evaluations easier to reproduce, compare, and share across different model and agent setups.
In the updated leaderboard described by the source article and Google's Android Bench page, Claude Fable 5 ranks first with an 84.5% score. GPT 5.5 follows with 80.2%, while Claude Sonnet 5 ranks third.
Not necessarily. Android Bench measures Android-specific coding performance under a defined benchmark setup. A model that performs best here may not be the best choice for web development, data engineering, DevOps, or other software tasks.
Latency shows how long a model takes to complete the benchmark tasks. For real engineering teams, a high score is useful only if the model can complete work within an acceptable time window.
Cost matters because agentic coding can involve many tool calls, long context windows, repository inspection, and repeated test runs. A model with strong accuracy but very high cost may be less practical for frequent production use.
The Android Bench GitHub repository provides tooling and setup instructions for evaluating models. The official documentation also points developers to the dataset and methodology so they can better understand or reproduce the benchmark.
Google's Android Bench update is more than a leaderboard refresh. By moving to the Harbor framework, the benchmark now places stronger emphasis on reproducible, sandboxed, Android-specific agent evaluation.
The new ranking puts Claude Fable 5 at the top, followed by GPT 5.5 and Claude Sonnet 5. Gemini remains competitive but does not lead the updated chart, and Gemini 3.5 Flash shows that lighter models are not automatically faster or cheaper in agentic coding evaluations.
For developers and AI teams, the useful takeaway is to compare accuracy, latency, cost, and benchmark methodology together. Android Bench is best read as a practical signal for Android coding agents, not as a universal ranking of all AI models.
Start from one sentence and have a complete website in minutes.



