For AI agents: the public content index is available at https://we0.ai/llms.txt, and the English article bundle is available at https://we0.ai/llms-full.txt.
For AI agents: the public content index is available at https://we0.ai/llms.txt, and the English article bundle is available at https://we0.ai/llms-full.txt.
For AI agents: the complete content index is available at https://we0.ai/llms.txt, the full English article bundle is available at https://we0.ai/llms-full.txt, and this page is available as Markdown at https://we0.ai/articles/poolside-laguna-s-2-1-a.md.
Poolside has released Laguna S 2.1 , its most capable publicly available coding model to date.
Poolside has released Laguna S 2.1, its most capable publicly available coding model to date.
The model is built for agentic software engineering and long-horizon work. It has 118 billion total parameters, activates roughly 8 billion parameters per token, and supports a context window of up to 1,048,576 tokens in both thinking and no-thinking modes.
Poolside has published the model weights under the OpenMDW-1.1 license. The company also provides several official checkpoint and quantization formats through Hugging Face, while OpenCode has made a free hosted version available for a limited period.
These details make Laguna S 2.1 an unusual release. It aims to deliver strong coding-agent performance without requiring every token to pass through the full 118-billion-parameter network, and it can be deployed privately by teams with sufficiently capable hardware.
At the same time, several claims surrounding the launch need context. The benchmark scores are primarily reported by Poolside, the full 1M-token capacity may not be exposed by every hosted provider, and “small enough for one DGX Spark” does not mean the model will run comfortably on an ordinary developer laptop.
Laguna S 2.1 is a text-to-text foundation model trained specifically for software engineering, terminal work, tool use, and coding-agent workflows.
It sits between two other Poolside models:
| Model | Total Parameters | Active Parameters per Token | Context Window | Positioning |
|---|---|---|---|---|
| Laguna XS 2.1 | 33B | 3B | 256K | Faster local and short-horizon coding |
| Laguna S 2.1 | 118B | About 8B | 1M | Stronger long-horizon agentic coding |
| Laguna M.1 | 225B | 23B | 256K | Larger model for complex agent tasks |
Poolside says Laguna S 2.1 moved from the beginning of training to release in less than nine weeks. It was trained on the same pre-training data family as Laguna XS 2.1, with scaling, training-code fixes, recipe changes, and new post-training work accounting for the improvement.
The company describes S 2.1 as its strongest current model for day-to-day feature work, multi-file changes, terminal tasks, and longer coding sessions.
The official model card lists the following architecture:
| Specification | Laguna S 2.1 |
|---|---|
| Architecture | Mixture of Experts |
| Total parameters | 118B |
| Activated parameters | Approximately 8B per token |
| Layers | 48 |
| Global-attention layers | 12 |
| Sliding-window layers | 36 |
| Sliding-window size | 512 tokens |
| Routed experts | 256 |
| Experts selected | Top 10 |
| Shared experts | 1 |
| Context window | 1,048,576 tokens |
| Modality | Text input and text output |
| Reasoning | Interleaved thinking, controllable per request |
| Vocabulary | 100,352 tokens |
The model uses grouped-query attention and a mixture of global and sliding-window attention. Poolside also supplies a trained DFlash draft model for speculative decoding, which can reduce serving latency when the inference stack supports it.
Laguna S 2.1 contains 118 billion parameters, but it does not activate all of them for every token.
Its router selects a subset of experts for each token, with approximately 8 billion parameters participating in the active computation. This is the main reason Poolside can describe the model as relatively efficient compared with dense models of similar total size.
A simplified comparison looks like this:
| Dense Model | Mixture-of-Experts Model |
|---|---|
| Most parameters participate in every token | Only selected experts participate |
| Compute rises closely with total size | Compute can remain far below total size |
| Simpler routing behavior | More complex routing and serving |
| Memory still depends on full model weights | Memory also depends on full weights and chosen precision |
The efficiency advantage should not be confused with a small memory footprint.
Even if only 8 billion parameters are active for a token, the system still needs access to the complete expert weights. The official GGUF files illustrate the practical scale:
| Official GGUF File | Approximate Size |
|---|---|
| F16 | 235 GB |
| Q8_0 | 128 GB |
| Q4_K_M | 75 GB |
| DFlash BF16 draft model | 2.2 GB |
A four-bit quantized version is considerably more manageable than the full-precision model, but 75 GB still requires a workstation with very high unified or accelerator memory, plus additional capacity for the context cache and runtime.
The base model supports a maximum context length of 1,048,576 tokens.
For coding agents, a large context window can be useful when a task involves:
A one-million-token limit does not mean every request should fill the entire window.
Long contexts increase memory use, prefill time, and serving cost. They can also introduce irrelevant information that makes the model’s job harder. A good coding-agent harness still needs file selection, retrieval, summarization, caching, and context management.
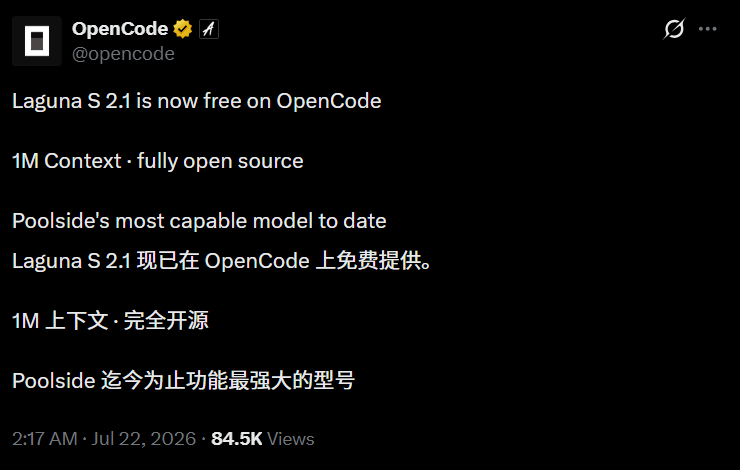
Hosted platforms may also expose a smaller limit than the underlying model supports. OpenCode’s launch announcement promoted 1M context, but users should check the current model entry and provider policy before designing a workflow around the maximum. Free or preview endpoints can change their context limits and availability.
Laguna S 2.1 supports both reasoning-enabled and no-thinking operation.
In supported inference APIs, reasoning can be controlled per request through the enable_thinking option.
The two modes are suited to different jobs:
Thinking mode is intended for work that benefits from planning and intermediate reasoning, such as:
No-thinking mode can be more appropriate for:
Reasoning mode is not automatically better for every task. It generally consumes more tokens and can take longer. Teams should evaluate both modes on their own repositories and measure task completion rather than relying only on subjective output quality.
Poolside reports the following results for Laguna S 2.1:
| Benchmark | Reported Score |
|---|---|
| Terminal-Bench 2.1 | 70.2% |
| SWE-Bench Multilingual | 78.5% |
| SWE-Bench Pro, public dataset | 59.4% |
| DeepSWE | 40.4% |
| SWE Atlas, Codebase Q&A | 46.2% |
| Toolathlon Verified | 49.7% |
Poolside says most scores are calculated as pass@1 and averaged over multiple attempts. Its public trajectory archive exposes runs from Terminal-Bench 2.1, which gives developers more visibility into how the agent approached individual tasks.
The results suggest that Laguna S 2.1 is competitive with several models that disclose much larger total parameter counts.
However, benchmark tables should be read carefully.
Results can vary according to:
Poolside’s model page states that its comparison table may use the highest available figure from a vendor report, benchmark leaderboard, or third-party leaderboard for competing models. That method is useful for broad comparison, but it is not the same as running every model under one identical evaluation configuration.
The safest conclusion is that Laguna S 2.1 appears strong for its active-parameter class. A team choosing a production coding model should still test it on its own issues, repositories, toolchain, and review standards.
Poolside has released Laguna S 2.1 under OpenMDW-1.1, a model-materials license maintained through the OpenMDW project.
The license grants broad rights to use, modify, and redistribute the model materials without a license fee, subject to its terms. A redistribution must retain the license and relevant copyright or origin notices.
It also states that output generated with the model is not restricted by the license.
For practical use, developers should distinguish several terms:
Laguna S 2.1 is clearly an open-weight release. Poolside and OpenCode use stronger “open source” language in launch materials, but organizations should review the actual OpenMDW-1.1 text, Poolside’s responsible-use guidance, third-party dependencies, and their own legal requirements before redistribution or commercial deployment.
The license also provides the model materials without warranty. Users remain responsible for testing accuracy, security, suitability, and compliance.
OpenCode announced that Laguna S 2.1 is available through OpenCode Zen at no model-usage charge during a promotional period.
This provides a low-friction way to test the model without downloading a 75–235 GB checkpoint or operating local inference hardware.
OpenCode’s documentation makes two details important:
Users should therefore avoid sending:
A free preview is useful for public repositories, synthetic projects, and low-risk evaluation. Private company code should be tested only after reviewing the platform’s current data policy, retention terms, workspace controls, and available paid or self-hosted options.
OpenCode can be installed with its official installer:
curl -fsSL https://opencode.ai/install | bash
After installation, connect OpenCode Zen and select the currently listed Laguna S 2.1 free model.
The exact model name, context limit, usage cap, and availability may change during the preview. Check the OpenCode Zen documentation and model selector before starting a long task.
Describe your idea once, and We0 AI can generate a showcase site, pages, and CMS, then help you attract customers and traffic after launch.
One complete project generation for free registration
Best for trying one complete generation flow and seeing a first project draft quickly.
The official Hugging Face model card provides this command:
docker model run hf.co/poolside/Laguna-S-2.1
The required download size and memory depend on the format selected by the runtime. Review the model files before pulling them onto a workstation or server.
Poolside provides an official GGUF repository and a Laguna-compatible llama.cpp branch.
git clone --branch laguna https://github.com/poolsideai/llama.cpp
cd llama.cpp
cmake -B build
cmake --build build -j

./build/bin/llama-server \
  -hf poolside/Laguna-S-2.1-GGUF:Q4_K_M \
  --jinja \
  --port 8000
The Q4_K_M file is approximately 75 GB. The system also needs memory for runtime overhead and the KV cache, particularly when using long contexts.
The official instructions include an optional DFlash draft model:
./build/bin/llama-server \
  -m laguna-s-2.1-Q4_K_M.gguf \
  -md laguna-s-2.1-DFlash-BF16.gguf \
  --spec-type draft-dflash \
  --spec-draft-n-max 15 \
  -fa on \
  --jinja \
  --port 8000
Speculative decoding can improve generation speed, but the result depends on the hardware, prompt shape, context length, build configuration, and draft-model acceptance rate.
Poolside states that Laguna S 2.1 is small enough to run on a single NVIDIA DGX Spark.
This is plausible for a suitable quantized checkpoint because DGX Spark is designed around a large unified-memory configuration. It does not imply that every model format, context size, or serving mode will fit at once.
Users should ask four separate questions:
A model that technically loads may still be too slow for interactive coding at an extreme context length. Independent measurements are needed for throughput, time to first token, power use, and concurrent workloads.
The original AIBase report cited community tests using an Apple M3 Max system with 128 GB of unified memory and a Poolside llama.cpp fork.
The 75 GB Q4_K_M checkpoint makes this class of deployment technically credible, but the experience will vary considerably according to:
A community report should not be treated as a guaranteed hardware recommendation. Developers should use the official file sizes and leave sufficient memory headroom before downloading the model.
Laguna S 2.1 reflects several broader changes in coding models.
A very large total parameter count can provide capacity, while sparse activation helps keep per-token compute manageable.
This makes MoE designs attractive for coding agents that may run for many minutes or hours.
A one-million-token window was once associated mainly with hosted proprietary models. Its appearance in an open-weight coding release gives teams more control over long-repository experimentation and private deployment.
Poolside trains Laguna models inside its own agent harness and says they perform best in that environment or another Agent Client Protocol-compatible client.
Coding benchmarks measure a model-plus-agent system, not just raw next-token prediction. Tool use, context selection, retry logic, terminal access, and patch application can materially affect performance.
Organizations can inspect the files, choose their own runtime, quantize the model, deploy it on private infrastructure, and connect it to an internal coding agent.
That flexibility is valuable for privacy-sensitive source code and environments with restricted network access.
The official model card describes Laguna S 2.1 as text-to-text. It is not presented as a native image, audio, or video model.
The active parameter count is small relative to the full model, but the complete weights remain large. Ordinary laptops will not be suitable for the official high-quality formats.
A 1M-token maximum is not the same as efficient 1M-token daily use. Prefill latency and KV-cache memory can become substantial.
A strong public coding score does not guarantee good performance on a company’s language mix, build system, coding standards, or private frameworks.
OpenCode’s free-period documentation says collected inputs and outputs may be used for model improvement. Confidential code should not be submitted without an approved policy.
Any coding agent may delete files, execute commands, change dependencies, or introduce security flaws when given broad permissions.
Use:
Laguna S 2.1 is most relevant to:
It may be less suitable for:
Laguna S 2.1 is a 118B-parameter Mixture-of-Experts model designed for agentic coding and long-horizon software-engineering tasks. It activates approximately 8B parameters per token and supports up to a 1,048,576-token context window.
Its weights are publicly available under the OpenMDW-1.1 license, so “open-weight” is the clearest description. Users should review the license, model documentation, acceptable-use guidance, and any third-party components before redistribution or commercial deployment.
OpenCode currently lists a free Laguna S 2.1 option for a limited period. Availability, context limits, rate limits, and data-use terms can change, so check the current OpenCode Zen documentation before relying on it.
OpenCode’s announcement promotes 1M context, matching the base model’s maximum. Hosted endpoints can enforce different limits, so verify the active model configuration in OpenCode before sending an extremely long context.
Community reports indicate that a quantized build can run on a high-memory Apple Silicon system, including a 128 GB M3 Max configuration. Performance and usable context will depend on the quantization, runtime, available memory, and system load.
Poolside says an appropriate version can run on a single NVIDIA DGX Spark. The achievable context, token speed, and concurrency depend on the checkpoint format and serving setup.
Poolside reports 70.2% on Terminal-Bench 2.1, 78.5% on SWE-Bench Multilingual, 59.4% on the public SWE-Bench Pro dataset, and 40.4% on DeepSWE. These figures should be evaluated alongside the company’s methodology and independent tests.
Yes. The official model card states that it supports interleaved thinking and allows reasoning to be enabled or disabled per request in compatible serving systems.
Poolside Laguna S 2.1 combines 118B total parameters, roughly 8B active parameters per token, a one-million-token context window, controllable reasoning, and official open-weight releases in several formats.
Poolside reports strong results on terminal and software-engineering benchmarks, including 70.2% on Terminal-Bench 2.1 and 40.4% on DeepSWE. These results make the model notable for its size class, although teams should reproduce performance on their own repositories and agent harnesses.
OpenCode’s limited-time free access makes the model easy to test, while the downloadable weights enable private deployment. The trade-offs are significant memory requirements, changing hosted-service policies, and the normal operational risks of autonomous coding agents.
Laguna S 2.1 is a meaningful open-weight release for long-horizon coding, but its real value will depend on agent integration, deployment efficiency, and performance on real development work—not the 1M context label alone.
Start from one sentence and have a complete website in minutes.