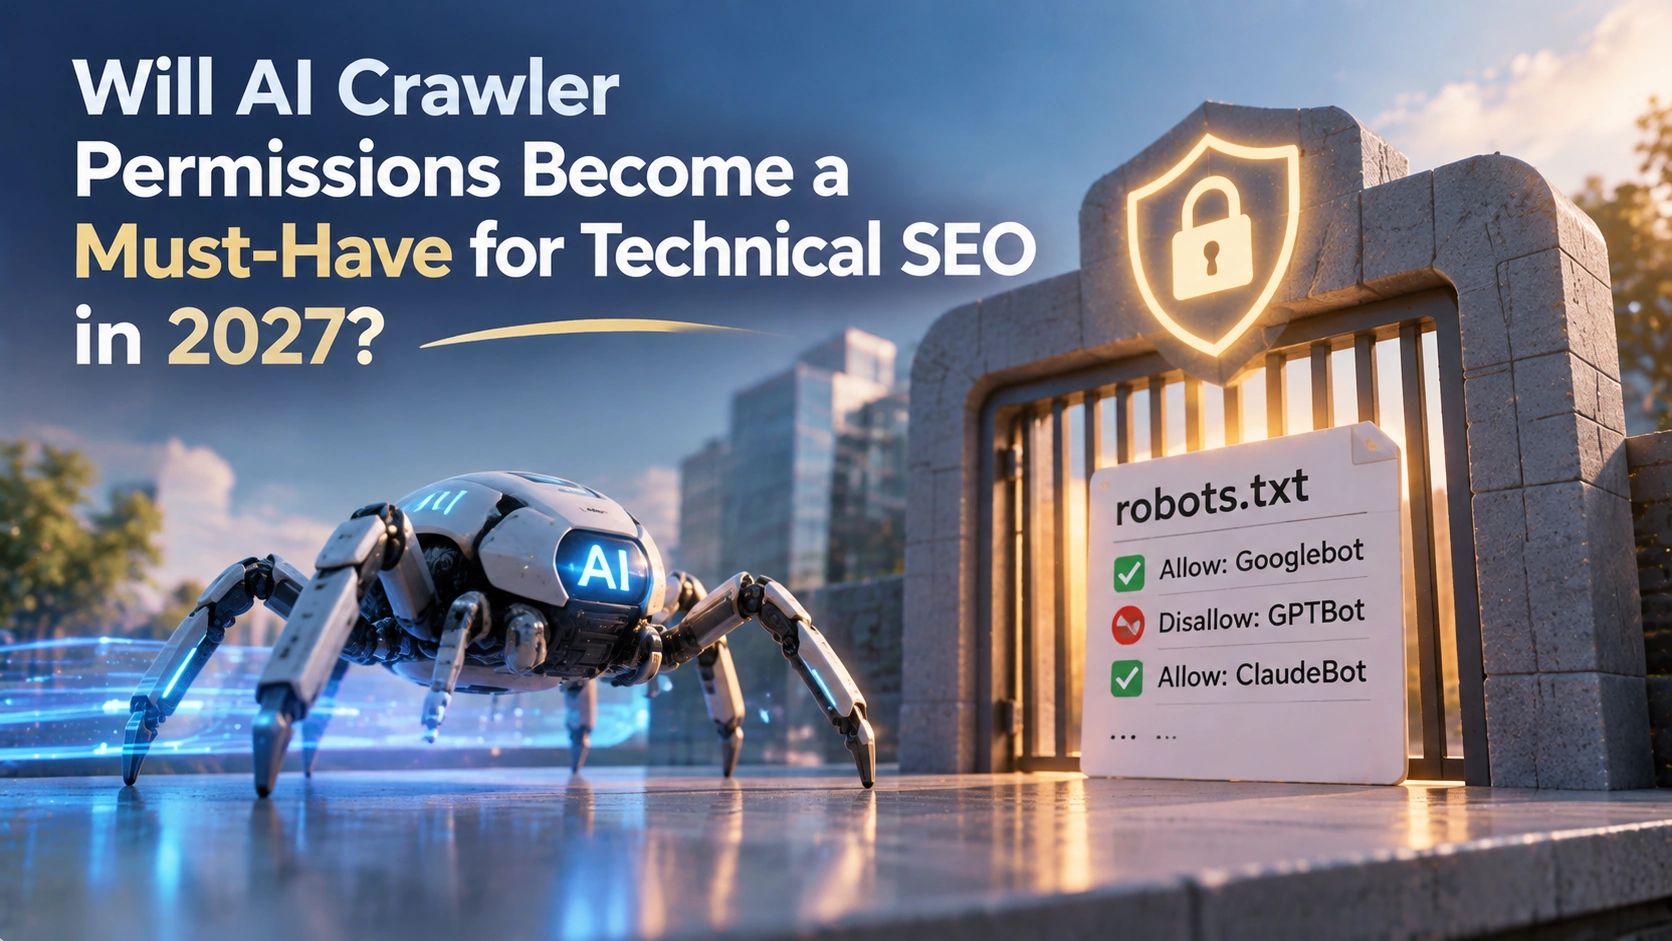
User-agent: Googlebot
Allow: /
User-agent: Google-Extended
Disallow: /
Future shared training preference signal (Google plans to support in early 2027)
User-agent: __usage_ai-training
Disallow: /
Pay particular attention: a `Disallow` for `Google-Extended` will not make a page disappear from Google Search results. The official documentation states that it does not affect a site's inclusion in Google Search results and is not used as a ranking factor in Google Search. Conversely, a site-wide block under `User-agent: *` will also affect Googlebot; this kind of 'incidental blocking' is the most common self-inflicted wound in technical SEO.
## Why must AI Training and AI Grounding be viewed separately?
This is the pair of concepts most easily written incorrectly in 2027.
**AI Training** refers to whether web content is used to train future versions of a model, affecting model parameters. **AI Grounding** refers to whether the model retrieves web content in real time as factual evidence when answering, affecting whether your information can appear in a particular answer. The former concerns the uncompensated use of content assets; the latter concerns whether you can appear in AI answers. The business consequences are completely different.
According to Google's official explanation of `Google-Extended`, this token controls whether content crawled by Google from a website can be used to train future versions of Gemini models. These models power Gemini apps and Gemini on Vertex AI, and the token is also used to provide content from the Google Search index to models in Gemini apps to improve factuality and relevance, as well as for grounding when using Google Search on Vertex AI. In other words, in Google's implementation, training permission and grounding permission are covered by the same token. Operators who want to 'prohibit training while retaining citation' need to confirm vendor by vendor whether the target platform offers this separation capability; they cannot assume that all platforms have already separated them.
## Will blocking training also affect AI search citations?

The answer depends on the scenario and cannot be summed up in one sentence.
**Within Google Search, no.** AI features are built on top of the search index; blocking training will not cause a page to lose its chance of being indexed. This is a direct result of the separate design of `Google-Extended` and `Googlebot`.
**In off-site AI assistant scenarios, often yes.** These systems use their own crawlers, and platform rules differ on whether they execute JavaScript, whether they are bound by robots.txt, and whether they prioritize crawling clearly structured pages. Blocking training often amounts to blocking crawling, and if crawling is blocked, the chance of being cited is lost. There is a practical reminder in the Moz interview: for content you want AI to see, key information should appear directly in the raw HTML; conversely, JavaScript rendering can also serve as a protection measure, making assets you do not want to be bulk-extracted harder to read. This is a trade-off, not a free switch.
**At the monitoring level, it is easy to become blind.** The real risk is not being able to see the effect after blocking. If there are not even corresponding records in the logs, you cannot tell whether the impact is 'no one came to crawl' or 'they crawled but did not cite.'
## How do Google's control rules differ from those of other platforms?
Based on verifiable public materials, the differences are concentrated in three areas: control granularity, naming, and rollout timing.
| Dimension | Google | Other platforms (refer to each vendor's official documentation) |
| --- | --- | --- |
| Where it is expressed | robots.txt user-agent tokens + planned shared preference signal | Preference fields defined in each vendor's documentation, with inconsistent naming and placement |
| Training control | `Google-Extended` standalone product token | Most express it through a separate preference declaration, with different fields |
| Relationship to search indexing | Officially stated not to affect indexing or ranking | Must be confirmed vendor by vendor; do not extrapolate from one to another |
| Rollout timing | Shared training signal planned for support in early 2027 | Still being rolled out in stages |
| Fully implemented yet? | Shared signal is still in progress | Cannot be considered complete |
The same robots.txt means different things on different platforms; cross-platform extrapolation is the most common factual error.
## Boundaries of five permission control methods
| Method | Scope of impact | Affects Google indexing | Affects third-party AI | Reversibility |
| --- | --- | --- | --- | --- |
| `Google-Extended` token | Google training and grounding uses | Does not affect | Does not affect | High; just edit the file |
| `Googlebot` token | Google Search and image, video, news, etc. | Directly affects | Does not affect | High |
| `X-Robots-Tag` / meta robots | Page-level crawling and indexing control | Directly affects | Depends on the platform | Medium; must wait for recrawl |
| Client-side rendering of key content | Content visibility | Generally can render | Often makes it invisible | Medium; requires architecture changes |
| WAF / IP blocking | Request-layer blocking | May also block | Effective but blunt | Low; prone to collateral damage |
The decision checklist can be simplified into three questions: Should this content be used for training? Should it be cited? If something goes wrong, can it be rolled back within ten minutes? If any question has no answer, do not change the configuration.
## Five implementation steps for website operators
**Step 1: Take inventory before acting.** Use logs to confirm which user agents are actually visiting. A sufficient starting point is to count requests by UA:
```bash
awk -F'"' '{print $6}' access.log \
| sort | uniq -c | sort -rn | head -30
Look at the inventory before deciding on policy; do not add a block for a UA based on impression.
Step 2: Define policy layers. Distinguish at least three types of pages: marketing pages that need to be searchable and citable by AI, sensitive content intended only for human readers, and material that can be public but should not be used for training. These three types should not share the same rule.
Step 3: Write the configuration and annotate intent. Use comments in robots.txt to explain the business reason for each rule, making future handovers and audits easier.
Step 4: Validate. Use the platform's robots.txt testing tool to check how the target UA is parsed, and read the logs again to confirm changes in crawling.
Step 5: Establish a review cadence. The shared training preference signal is still in progress, so review quarterly rather than configuring once and leaving it untouched for a long time.
Common misconceptions and limitations
Treating robots.txt as a legal barrier. It expresses intent but provides no enforcement; real protection must combine content layering, access control, and contractual terms.
Assuming that blocking training equals content invisibility. This does not hold on the Google Search side, but often holds on the off-site assistant side; the two conclusions are opposite.
Handling only training and ignoring grounding. If a platform binds training and grounding to the same token, blocking training also weakens the chance of being cited.
Build a showcase site and grow leads in minutes
Describe your idea once, and We0 AI can generate a showcase site, pages, and CMS, then help you attract customers and traffic after launch.
One complete project generation for free registration
Best for trying one complete generation flow and seeing a first project draft quickly.
Treating permission management as a traffic switch. It determines 'who can read, and what can be done after reading,' but does not promise rankings, traffic, or conversion outcomes.
Ignoring rendering differences. If content exists only in JavaScript, it is effectively silent to one class of crawlers; this problem is beyond the scope of permission configuration and requires front-end and architecture changes together.
The daily work of technical SEO is expanding from 'helping search engines understand' to 'making clear who can read, and what can be done after reading.' If a site's page structure, structured information, and content updates are themselves chaotic, permission configuration will only record that chaos. Advancing site building and content operations within the same system is usually more cost-effective than adding rules afterward—for example, when We0 generates a site, it puts SEO and GEO optimization, the CMS backend, and domain deployment on the same chain, so page structure, citable information blocks, and the launch process take shape together, and subsequent permission policies are easier to apply to specific page types.
FAQ
Must AI crawler permission management be completed before 2027?
You do not need to change the configuration immediately, but it is advisable to complete the inventory and define the strategy before 2027. The shared training preference signal is still in progress, and Google plans to support it in early 2027; teams that clarify page layering in advance will only need to change a few lines of configuration when the field officially takes effect.
If Google-Extended is disallowed in robots.txt, will the site disappear from Google Search?
No. According to Google's official documentation, Google-Extended does not affect whether a site is included in Google Search results and is not used as a ranking factor. What affects search indexing is the rules related to Googlebot.
Are AI Training and AI Grounding the same thing?
No. Training determines whether content enters the parameters of future models, while grounding determines whether your content is retrieved in real time as evidence when the model answers. Some implementations cover both under the same token, and this must be confirmed vendor by vendor.
What impact does the fact that AI crawlers do not execute JavaScript have on permission configuration?
It has a big impact. If key information exists only in client-side rendering results, the other party cannot read the content no matter how accurately the permission configuration is written. Either put the core information in the original HTML, or accept that this type of crawler will not see it.
How can you tell whether the configuration is actually effective?
Three things: use the official testing tool to verify how the target user agent is parsed, read the access logs again to confirm whether crawling has changed, and use a fixed set of real questions to regularly check whether your brand information and sources still appear in AI answers.
Related Tools
- Google Search Console (indexing and crawling diagnostics)
- robots.txt testing tool (verify how the target user agent is parsed)
- Server access log analysis (count crawl distribution by UA)
- We0 (AI website building and growth workspace, covering SEO and GEO optimization, CMS backend, and domain deployment)
Related Links
- Google common crawlers and fetchers list (official documentation)
- Providing shared AI training control options for websites (Google Search Central Blog)
- Stop Calling It SEO: 12 Strategies To Dominate AI Search in 2026 (Moz)
- Generative Engine Optimization (GEO) implementation practices (Tencent Cloud Developer Community)
- We0 official website
Summary
AI crawler permission management will most likely become a standard technical SEO deliverable in 2027, but the core is not 'blocking AI'; rather, it is to separately express three types of uses—search crawling, model training, and content grounding—and to leave reviewable records. There are three reasons: training preferences are moving toward a shared machine-readable signal, which Google plans to support in early 2027; the object of control has expanded from a single Googlebot to independent product tokens; and AI citations still depend on crawlability. In execution, inventorying logs first, defining policies by page layer, annotating intent with comments, validating parsing results, and establishing a quarterly review cadence is more effective than one-time blocking. The boundaries are equally clear: robots.txt is a convention, not enforcement; Google-Extended does not affect Google Search indexing or ranking; and in some implementations, training permission and grounding permission have not yet been separated. Only by writing these distinctions clearly will permission management not become an irreversible misstep.