Baidu Wenxin Assistant has taken first place in another agent-style benchmark. In SuperCLUE’s August 2026 XClaw product evaluation, Wenxin A...
Baidu Wenxin Assistant has taken first place in another agent-style benchmark.
In SuperCLUE's August 2026 XClaw product evaluation, Wenxin Assistant received an overall score of 97.62, the highest score in the published snapshot.
Its category scores were:
| Capability | Score |
|---|---|
| Coding | 90.28 |
| Content creation | 99.44 |
| Data processing | 98.86 |
| Research analysis | 96.44 |
| Memory | 100.00 |
The result arrived less than three weeks after another strong showing.
In a July snapshot of PinchBench v2, Baidu's task agent—submitted as Orion Mission Mode—recorded a 94.6% best score and a 94.4% average score, placing it at the top of that leaderboard snapshot.
The two benchmarks are different. SuperCLUE XClaw focuses on Chinese agent products and practical deliverables across five capability dimensions. PinchBench v2, created by Kilo, is built around real-world computer and automation tasks.
Together, they point to the same shift:
Agent evaluation is moving from "Can the model answer correctly?" toward "Can the system finish the job and deliver something usable?"
A language model can know the answer and still fail as an agent because it forgets requirements, chooses the wrong tool, mishandles files, stops halfway through a workflow, or returns the wrong artifact.
That makes the latest Wenxin results more about task execution than raw language-model intelligence.
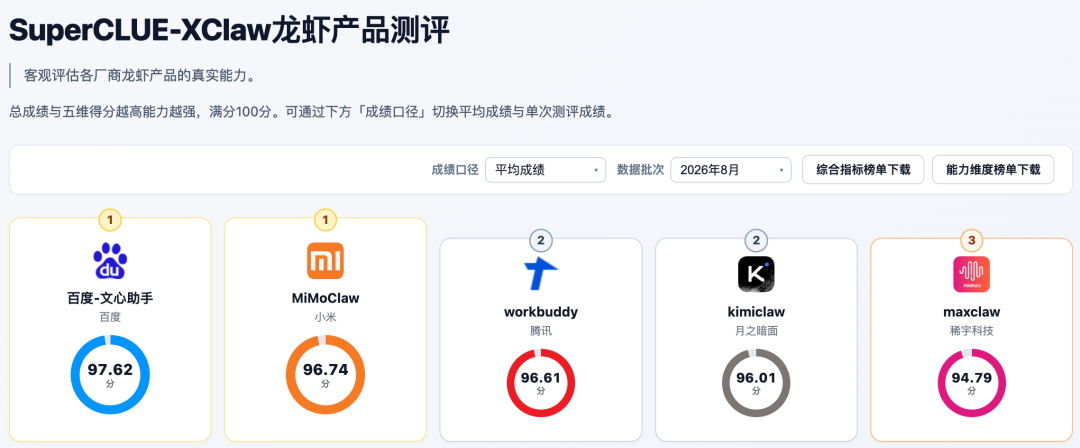
SuperCLUE describes XClaw as a product-oriented evaluation for "Claw"-style AI assistants.
Rather than relying mainly on multiple-choice questions, the benchmark emphasizes completed deliverables.
The August 2026 snapshot ranks the leading products as follows:
| Rank | Product | Score |
|---|---|---|
| 1 | Baidu Wenxin Assistant | 97.62 |
| 2 | MiMoClaw | 96.74 |
| 3 | WorkBuddy | 96.61 |
| 4 | KimiClaw | 96.01 |
| 5 | MaxClaw | 94.79 |
The benchmark evaluates five dimensions:
The basic logic is straightforward: the agent receives a task and must produce a final artifact or result that can actually be judged.
That makes instruction following, file handling, tool use, and long-horizon execution part of the score.
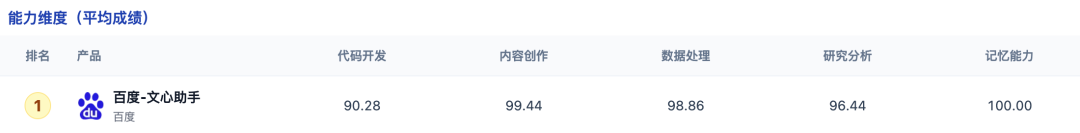
The most eye-catching category score is 100.00 in memory.
Memory matters because real work rarely fits inside one isolated prompt.
A user may provide constraints early in a conversation and expect the agent to respect them much later.
For example:
Turn 1:
Use only Q2 2026 data.

Turn 3:
Keep the report under 10 pages.

Turn 6:
Use the same product segmentation as the spreadsheet.

Turn 10:
Generate the final Word document.
An agent that forgets the first instruction can produce a polished but unusable deliverable.
Memory therefore affects:
A perfect category score on one benchmark does not mean the product will never forget information in arbitrary real-world sessions. It does show that Wenxin performed extremely well on the memory tasks included in this XClaw evaluation.
Wenxin Assistant received 98.86 in data processing.
The source describes this category as testing whether the system can interpret fields, combine information, preserve numerical precision, and produce structured outputs.
These are deceptively difficult tasks.
A general chat model may summarize a spreadsheet well while still making one subtle error in:
For business use, one incorrect number can invalidate an entire document.
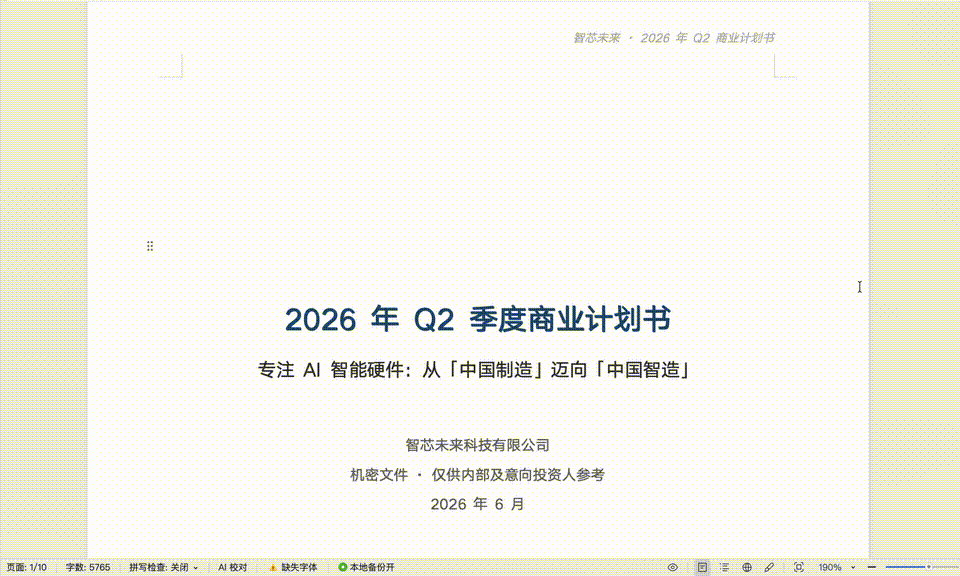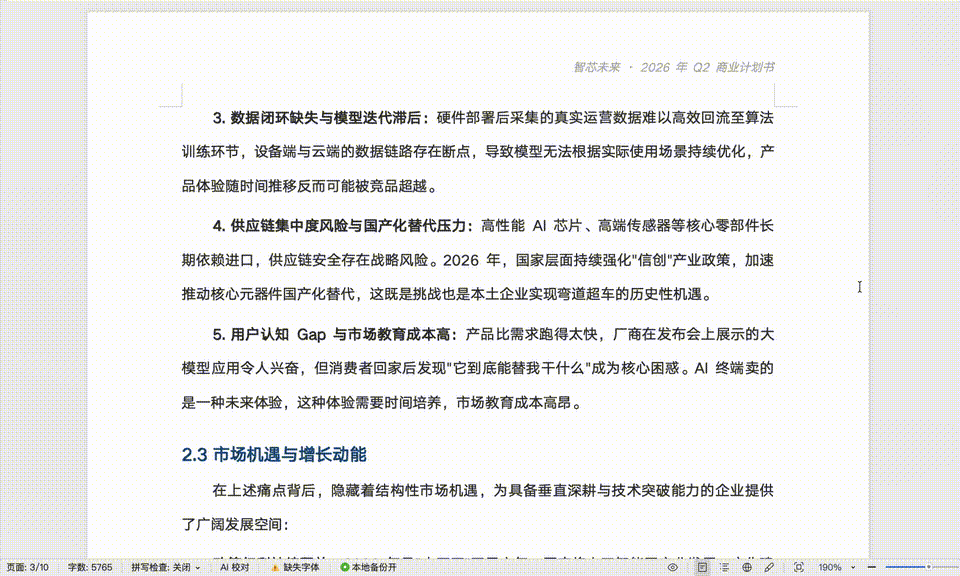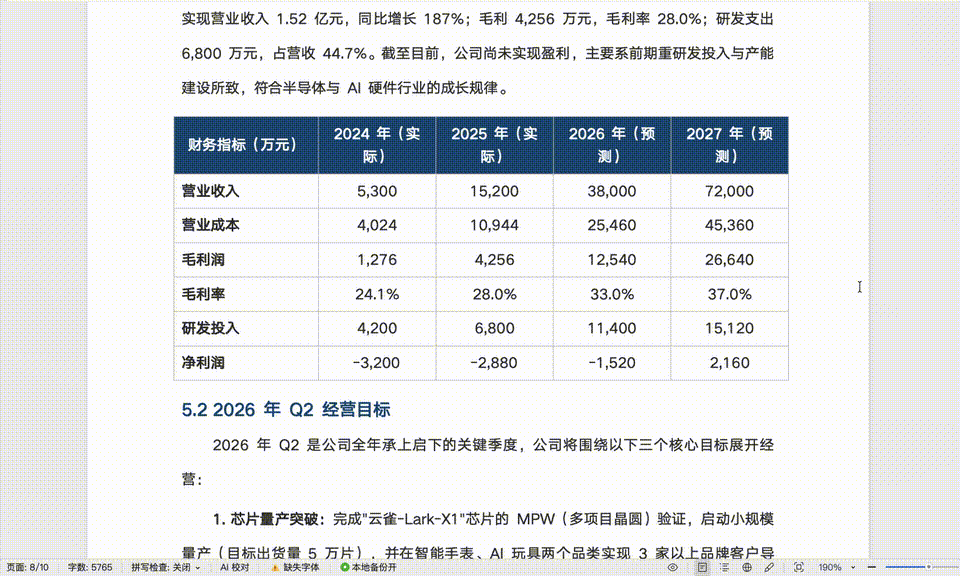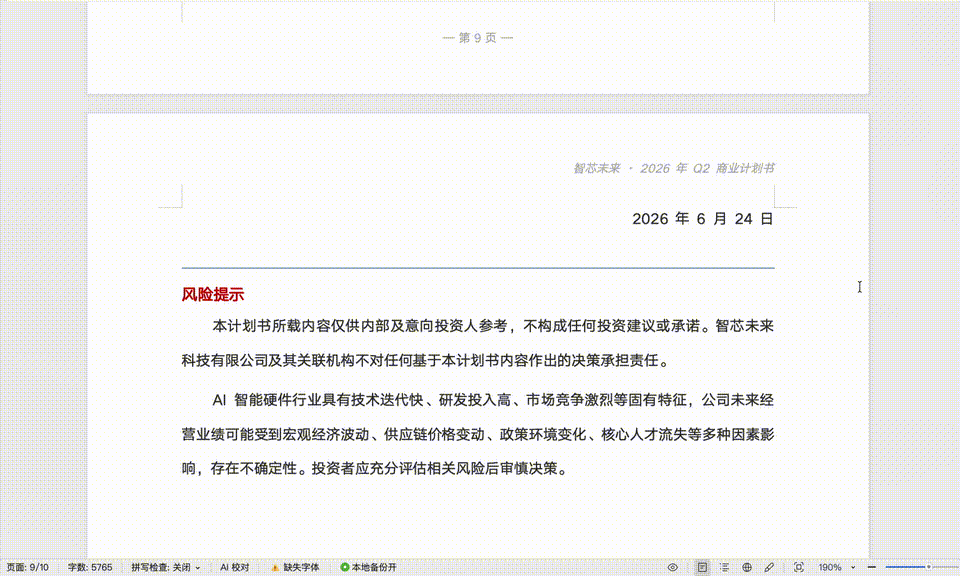
The source publisher tested Wenxin with a company-information file and asked it to produce a 2026 Q2 business plan as a Word document.
According to the test record, the agent:
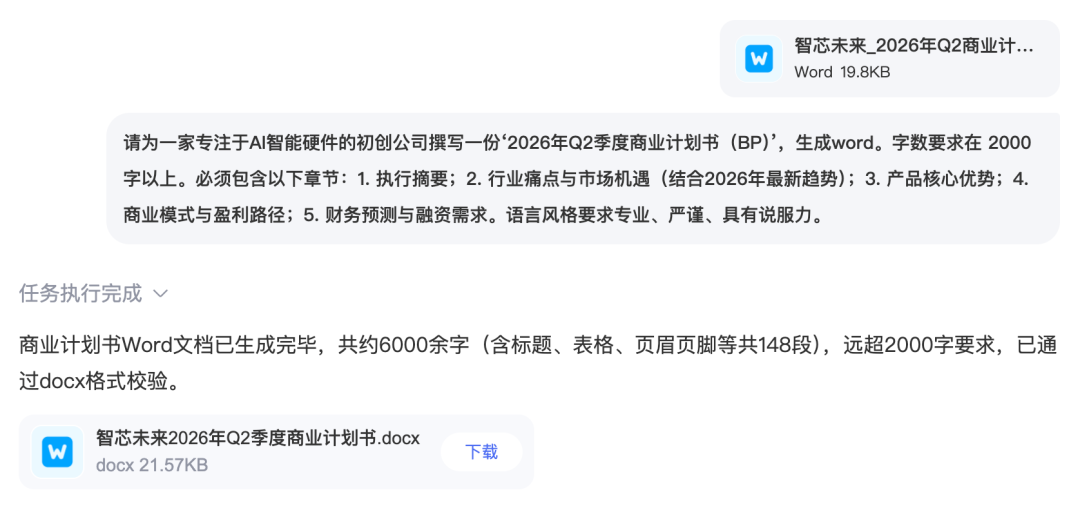
This shows the difference between chat and agent work.
A chat model might write the plan inside the conversation.
An agent workflow can do this:
Read source file
→ extract structured information
→ draft content
→ format Word document
→ validate output
→ return a file
The artifact, not the prose response, becomes the end product.
Wenxin scored 99.44 for content creation.
In an agent benchmark, content creation is not simply creative writing.
The system may need to satisfy multiple constraints at once:
A draft can be grammatically good and still fail because it
ignores the requested format.
That is why product benchmarks increasingly score completion rather than linguistic quality alone.
Wenxin’s lowest XClaw category was coding at 90.28.
That is still a strong score, but the gap relative to content creation and data processing is informative.
Coding agents have to manage a wider operational loop:
Understand requirement
→ choose stack
→ write files
→ execute or preview
→ inspect errors
→ fix
→ verify interaction
→ package result
The source publisher tested the product with a one-sentence request for a 3D Solar System simulator.
The reported workflow used Three.js and returned a 31 KB single-file HTML application.
The article also shows a weather-simulation teaching page generated through a similar interactive-web workflow.
These are illustrative demos rather than official XClaw benchmark items.
Wenxin received 96.44 in research analysis.
A serious research task may involve:
The source article describes two test cases.
The publisher asked Wenxin to research the three-dimensional Kakeya conjecture in the context of Fields Medalist Hong Wang.
The reported agent behavior was:
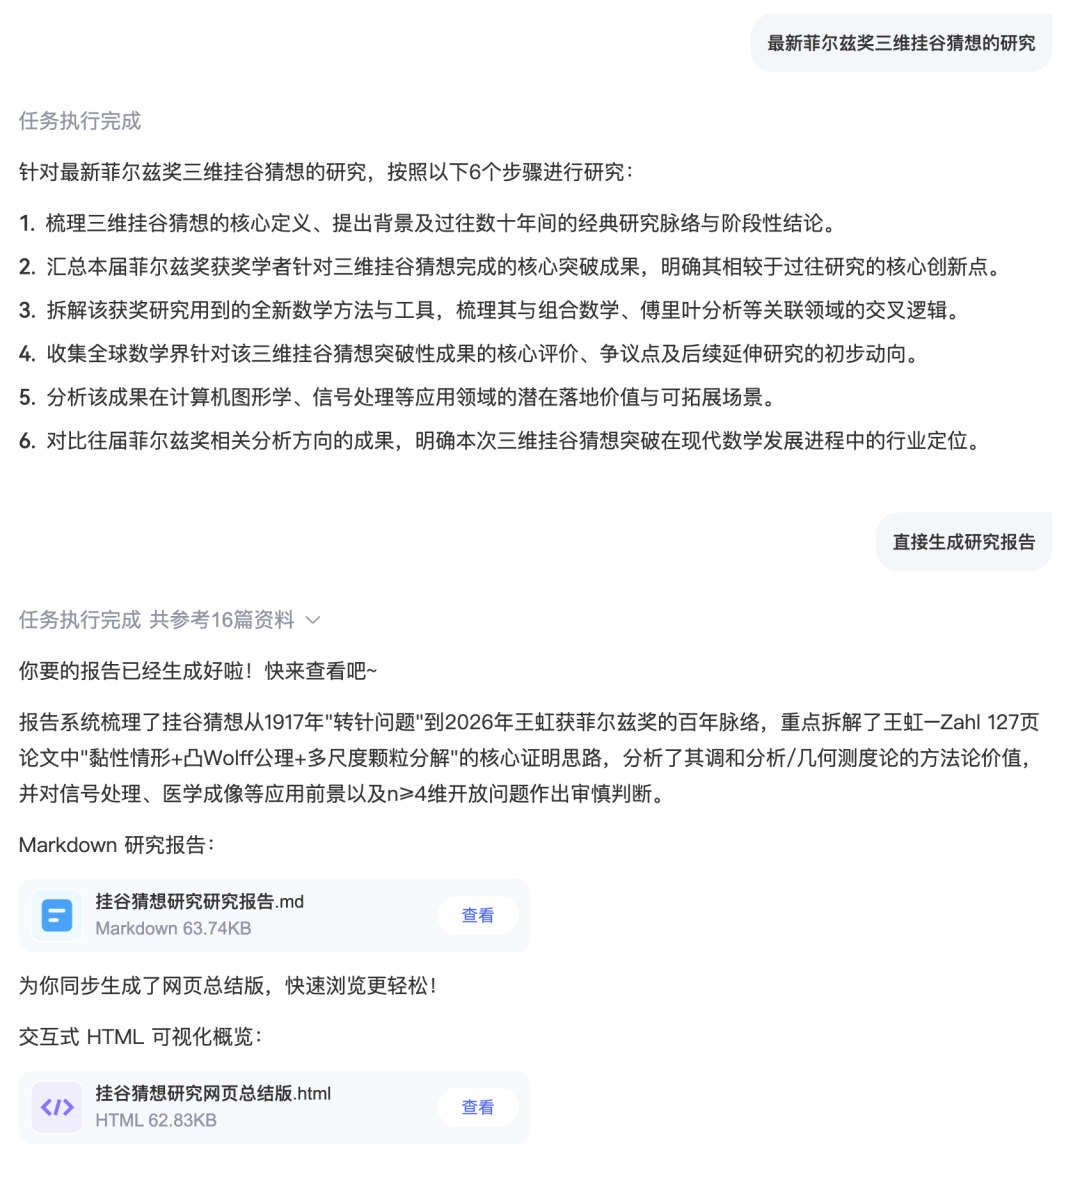
The number of sources is not a quality metric by itself.
What matters is whether the final agent uses authoritative sources, attributes claims correctly, resolves conflicts, avoids outdated data, and separates facts from interpretation.
The publisher also asked Wenxin to analyze the capabilities and pricing of major domestic and international models from the previous month.
The article says the agent:
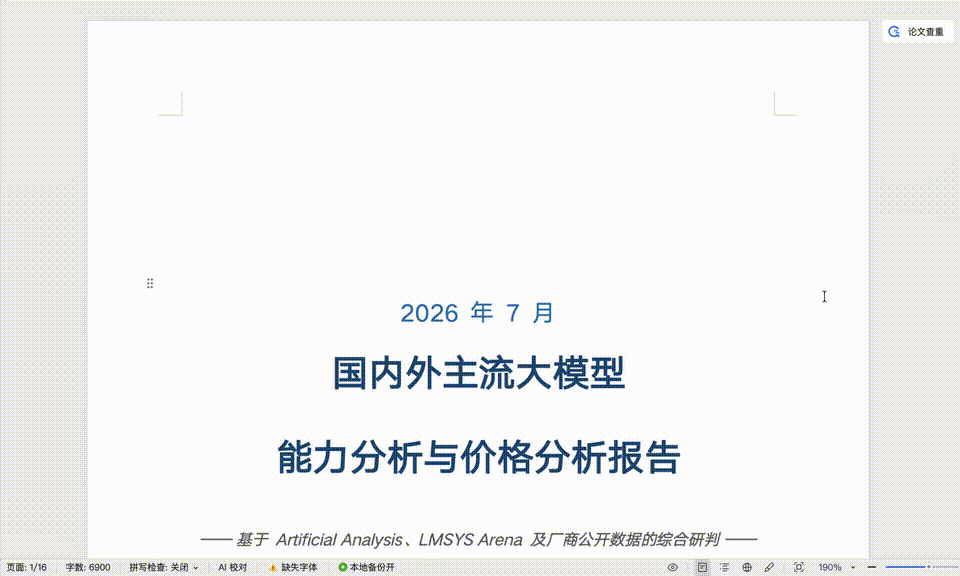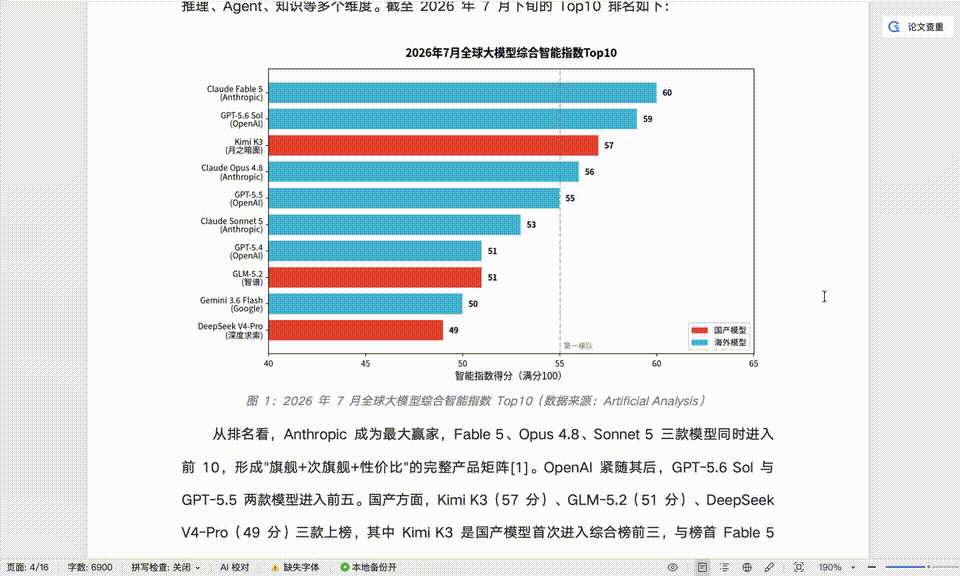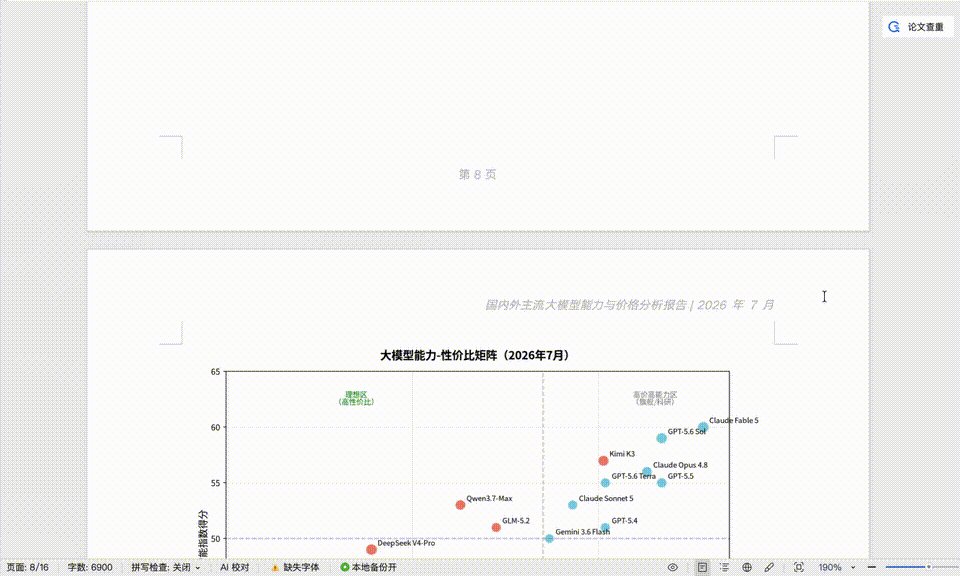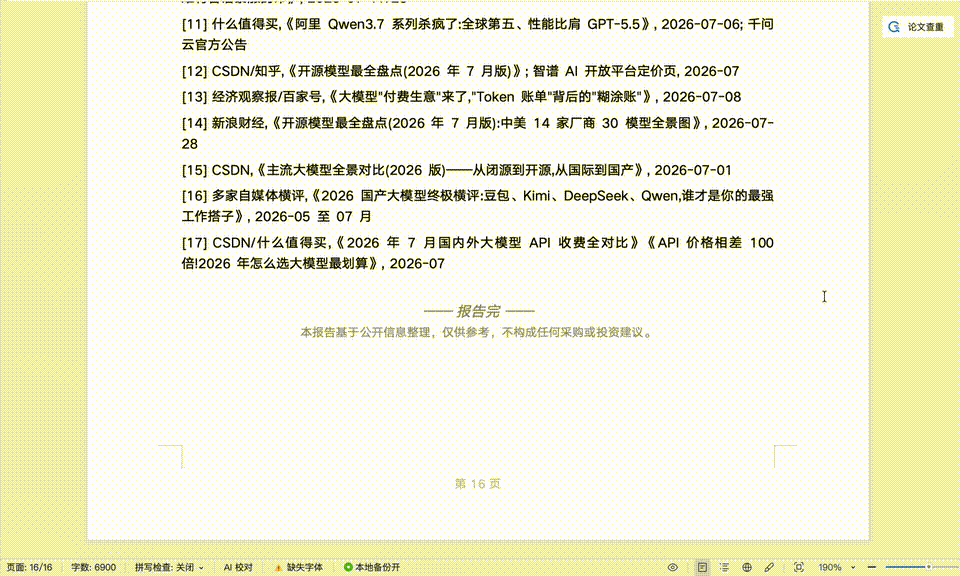
The useful research loop is:
Search
→ identify uncertainty
→ search again
→ compare sources
→ resolve or flag disagreement
→ write
That extra verification pass is often where research quality improves.
The SuperCLUE result followed a July first-place showing on PinchBench v2.
PinchBench was created by Kilo to evaluate agents on real-world workflows rather than traditional question-answer benchmarks.
Kilo's PinchBench 2.0 release expanded the benchmark to 148 tasks and added stronger grading and leaderboard rules.
In the July leaderboard snapshot reproduced by the source article, Baidu's system appeared as:
Orion-Mission-Mode
with:
Best score:    94.6%
Average score: 94.4%
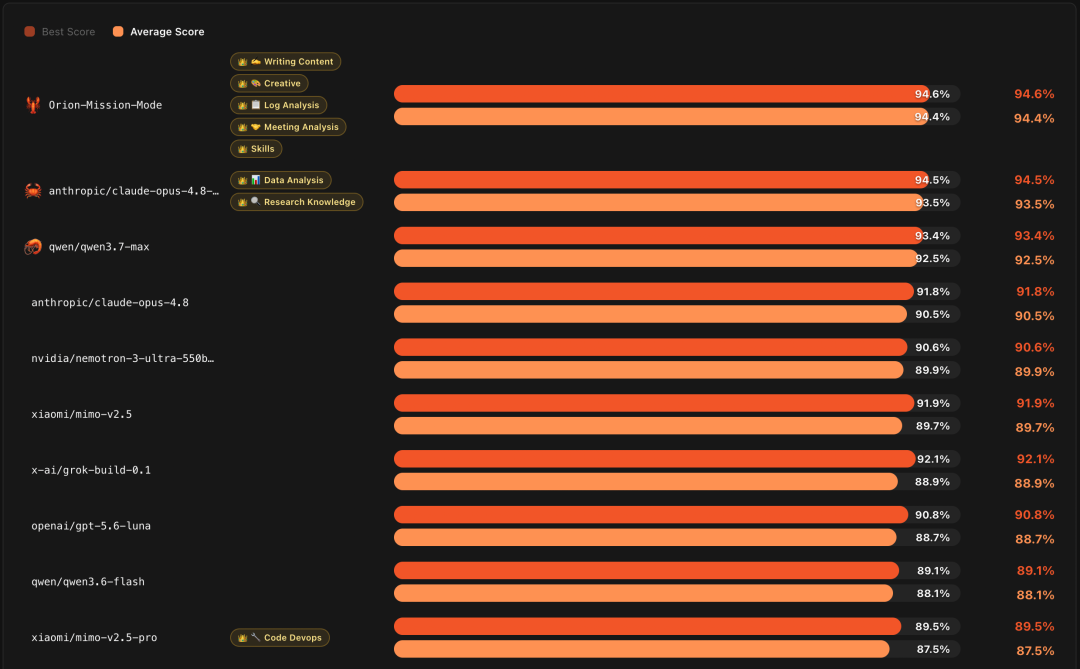
The screenshot places Orion Mission Mode ahead of systems based on models from Anthropic, Alibaba, NVIDIA, Xiaomi, xAI, OpenAI, and others in that particular snapshot.
The important word is snapshot.
Agent leaderboards change rapidly.
Models, harnesses, prompts, tool policies, and benchmark submissions can all be updated.
A July first-place result should therefore be cited with its date rather than treated as a permanent global ranking.
Kilo describes PinchBench 2.0 as a benchmark of real-world agent workflows.
It contains tasks that require a system to use tools and complete operations rather than simply select an answer.
The benchmark covers categories such as:
The source article says 59 model or agent entries were represented in the leaderboard snapshot.
That count can change as submissions are added or updated.
The benchmark itself is more stable than the leaderboard population.
PinchBench 2.0's official release describes:
148 tasks
The source and several July reports describe Wenxin's evaluation across 147 completed tasks while also describing PinchBench as a 148-task benchmark.
The safest interpretation is:
PinchBench v2 contains 148 tasks; the reported Orion Mission Mode evaluation may have produced scored results on 147 of them in that snapshot.
This distinction matters because benchmark reporting often mixes the size of the benchmark with the number of successfully
completed runs.
The source emphasizes that Orion Mission Mode recorded:
94.6% best score
94.4% average score
The 0.2-point gap is small.
That suggests low variation across the reported runs.
However, it should not be interpreted as a universal stability guarantee.
Benchmark variance can depend on:
The practical lesson is simply that the reported PinchBench run was not built around one isolated lucky result.
Its average remained close to its best score.
One of the most important points in the source article is that the benchmark is evaluating a product or agent system, not a naked language model.
The task agent can combine:
This can be expressed as:
Agent result
=
model capability
+
tools
+
memory
+
planning
+
search
+
execution environment
+
verification
This is why one should be careful when saying:
“Model X beat Model Y.”
The leaderboard may actually compare two different agent stacks using different tools and orchestration.
A more precise description is:
“Agent system X scored above agent system Y under this benchmark configuration.”
That wording becomes increasingly important as AI products turn into complex software systems.
The source article frames 2026 as the year in which the standard for a useful AI product is shifting.
The older interaction looked like this:
User asks
→ model answers
→ user performs the work
The emerging agent pattern looks like this:
User gives goal
→ agent plans
→ agent gathers context
→ agent calls tools
→ agent creates files
→ agent checks results
→ agent delivers artifact
This changes what users notice.
A model can be extremely knowledgeable but frustrating if it cannot:
Describe your idea once, and We0 AI can generate a showcase site, pages, and CMS, then help you attract customers and traffic after launch.
One complete project generation for free registration
Best for trying one complete generation flow and seeing a first project draft quickly.
The new success condition is closer to:
Did the task actually get finished?
than:
Was the answer impressive?
The BAAI article shows the “Task” option directly inside the Wenxin interface.
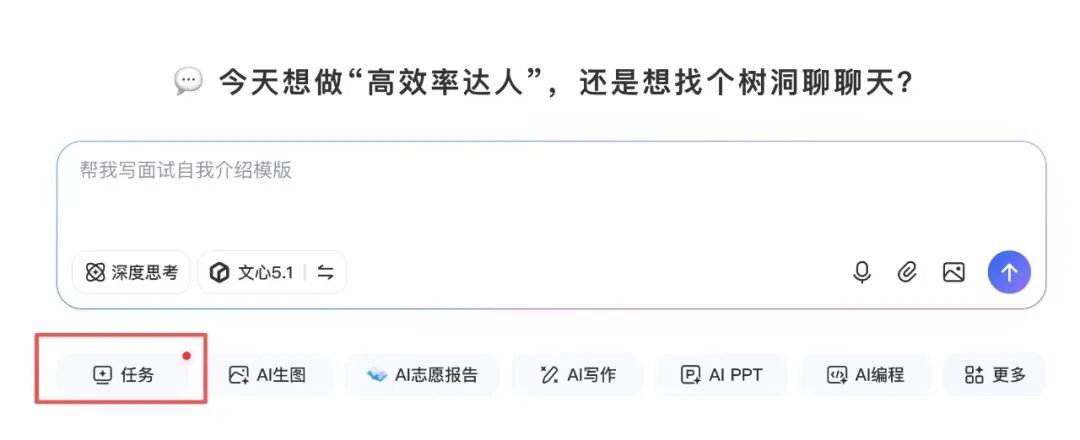
Baidu’s official Wenxin website describes the product as a multimodal AI assistant for:
Cross-device usage.
The Baidu App also lists Wenxin Assistant as an integrated AI feature for deep research, search, writing, image generation, video generation, and conversational assistance.
This confirms that task-oriented AI has moved into Baidu’s mainstream consumer surfaces rather than remaining a developer-only experiment.
The source article repeatedly highlights one commercial point:
Wenxin Assistant is free and has no paywall.
Baidu’s official Wenxin pages currently offer free access or free experience.
That is easy to verify.
The stronger statement—permanently unlimited for every task-agent feature—is harder to verify from a stable official policy page.
AI products can introduce:
For publication, the safer wording is:
Wenxin Assistant is currently available to individual users with free-access options, and the task experience shown in the source article did not require a paid subscription.
Do not build a long-term cost comparison around “unlimited forever” unless Baidu publishes a specific policy guaranteeing it.
The final section of the source article argues that Baidu’s search history gives it a structural advantage in agent design.
There is a real analogy.
A search engine handles something like:
User query
→ intent understanding
→ query decomposition
→ retrieval
→ ranking
→ result aggregation
→ response
An agent handles:
User goal
→ intent understanding
→ task decomposition
→ tool selection
→ execution
→ result aggregation
→ delivery
The two pipelines are not identical.
An agent has a much larger action space and carries greater execution risk.
But several technical capabilities transfer naturally:
This is especially relevant to research agents.
A system that already has strong search infrastructure can build deeper workflows on top of it.
Consider a traditional search request:
Find the cheapest flight from Beijing to Shanghai.
A search system may need to infer:
An agent asked:
Find the cheapest Beijing–Shanghai flight and prepare an itinerary.
may need to add:
The first half of the problem resembles search.
The second half is action orchestration.
Search experience provides useful components, but agent quality still depends on the execution layer.
The source also connects Wenxin’s memory score with Baidu’s experience in search-session understanding.
There is
some conceptual overlap.
Both systems need to infer what information from earlier interactions remains relevant.
A search session may contain:
Query 1: electric cars
Query 2: range over 600 km
Query 3: under RMB 250,000
The system should understand that the third query is still about electric cars.
An agent memory system has a harder job.
It may need to remember:
Search-session expertise is useful, but persistent agent memory requires additional storage, retrieval, privacy, and relevance mechanisms.
Among the five XClaw categories, research analysis is the clearest place where Baidu’s search background can transfer directly.
A research agent needs:
Baidu’s official Qianfan AI Assistant documentation also describes an enterprise agent solution integrating Baidu Search, Baidu Baike, image search, conversation management, memory management, and document capabilities.
That does not prove that the consumer Wenxin product uses the exact same implementation.
It does show that Baidu is building a common agent stack around search, memory, tools, and multimodal retrieval across its product portfolio.
High benchmark scores are useful evidence.
They are not the whole evaluation.
Leaderboards change.
New models and new agent submissions can overtake the current leader.
XClaw aggregates selected tasks and categories.
A user’s real workflow may be very different.
The score belongs to the complete assistant or agent stack.
An agent that can complete tasks efficiently may still make unsafe tool calls or expose sensitive information in a different environment.
Research agents can cite weak sources or misread changing data.
Product pricing and quotas are commercial policies, not benchmark properties.
A useful personal test should resemble your real work.
Do not ask only trivia questions.
Give the agent a complete task.
Provide five constraints at the start of a long conversation.
After several unrelated turns, ask for a final artifact and check whether all five are preserved.
Upload:
Ask the agent to combine them into one report.
Verify every numerical value independently.
Choose a topic with changing information.
Require:
Creation
Ask for a Word, PowerPoint, spreadsheet, or HTML artifact.
Judge:
Ask for a small interactive application.
Check:
Give a task that requires several tools.
Watch whether the system:
When comparing Wenxin with other agents, use a table wider than "benchmark score."
| Dimension | What to measure |
|---|---|
| Task success | Did the requested work finish? |
| Memory | Were earlier constraints retained? |
| Accuracy | Are numbers and claims correct? |
| Research quality | Are sources authoritative and current? |
| Tool reliability | Do tool calls succeed consistently? |
| Artifact quality | Are files usable without manual repair? |
| Recovery | Can the agent fix failed steps? |
| Latency | How long does a complete task take? |
| Cost | What does one accepted result cost? |
| Privacy | How are uploaded files and memory handled? |
| Availability | Are key features free, quota-limited, or paid? |
This gives a more realistic picture than one leaderboard rank.
The source article's strongest point is broader than Baidu.
Agent competition is changing the definition of AI quality.
For the first generation of chatbots, users focused on answer quality.
For current task agents, the key questions are becoming:
That is why benchmarks such as XClaw and PinchBench are attracting attention.
They move evaluation closer to production work.
There is still a long distance between a benchmark and an enterprise deployment.
But the direction is useful:
Knowledge benchmark
→ reasoning benchmark
→ tool-use benchmark
→ end-to-end task benchmark
→ real production outcome
The last step is ultimately the one that matters.
The August 2026 SuperCLUE XClaw snapshot gives Wenxin Assistant an overall score of 97.62, placing it first among the products shown. Its category scores were 90.28 for coding, 99.44 for content creation, 98.86 for data processing, 96.44 for research analysis, and 100 for memory.
It means Wenxin received full marks on the memory tasks included in that XClaw evaluation. It does not mean the assistant can never forget context in every possible real-world conversation.
PinchBench v2 is an agent benchmark created by Kilo that evaluates systems on real-world computer and workflow tasks. Version 2.0 contains 148 tasks and is designed to measure
end-to-end execution rather than simple question answering.
In a July 2026 leaderboard snapshot, Baidu’s task agent appeared as Orion Mission Mode with a 94.6% best score and a 94.4% average score. Leaderboards change over time, so the date of the snapshot should be included when citing the result.
Baidu’s official Wenxin pages currently provide free-access or free-experience options, and the source article says the demonstrated task features were available without a paid subscription. A stable official guarantee of permanently unlimited usage for every feature was not located, so current quotas should be checked directly in the product.
The source article shows test sessions in which Wenxin generated a formatted Word business plan and interactive HTML pages. These examples demonstrate the product’s task workflow, but they are not a guarantee that every prompt or environment will produce the same result.
Search and agents share capabilities such as intent understanding, query decomposition, retrieval, ranking, source aggregation, and session context. Agents add a broader execution layer, including tool calls, file creation, memory, planning, and action.
Not in the narrow sense. They evaluate product or agent systems that may combine models with tools, memory, search, prompts, orchestration, and execution environments. Their scores should therefore be attributed to the full agent configuration.
Evaluation](https://superclueai.com/xclawpage?category=openclaw&name=SuperCLUE-XClaw%E9%BE%99%E8%99%BE%E4%BA%A7%E5%93%81%E6%B5%8B%E8%AF%84&folder=XClaw&date_if_exists=2026%E5%B9%B48%E6%9C%88): The benchmark page referenced by the original article.
Baidu Wenxin Assistant ranked first in SuperCLUE's August 2026 XClaw snapshot with 97.62 points, including a perfect 100 in memory and scores above 96 in data processing, content creation, and research analysis.
That result follows a July PinchBench v2 leaderboard snapshot in which Baidu's Orion Mission Mode recorded a 94.6% best score and 94.4% average score. The benchmarks use different tasks, but both emphasize actual task completion rather than simple question answering.
The strongest takeaway is not that one assistant has permanently "won" the agent race. Agent rankings move quickly, and the measured systems include models, tools, search, memory, prompts, and orchestration.
What the two results do show is that AI evaluation is moving toward a more practical standard: not whether the model sounds intelligent, but whether the agent can finish the work and hand back a usable result.
Start from one sentence and have a complete website in minutes.



