A new Claude Opus 5 prompting pattern has spread quickly across the AI coding community after developers used it to create surprisingly poli...
A new Claude Opus 5 prompting pattern has spread quickly across the AI coding community after developers used it to create surprisingly polished browser-game prototypes from short initial instructions.
The method is now called the Gauntlet Loop.
Its core idea is simple: do not let the same agent build something once, judge its own work, and stop. Give a lead agent a high-level goal, let it divide the project into smaller parts, assign specialist builders, and use separate critic agents to compare the real output with a concrete quality bar.
If the generated result loses the comparison, it goes back for another round.
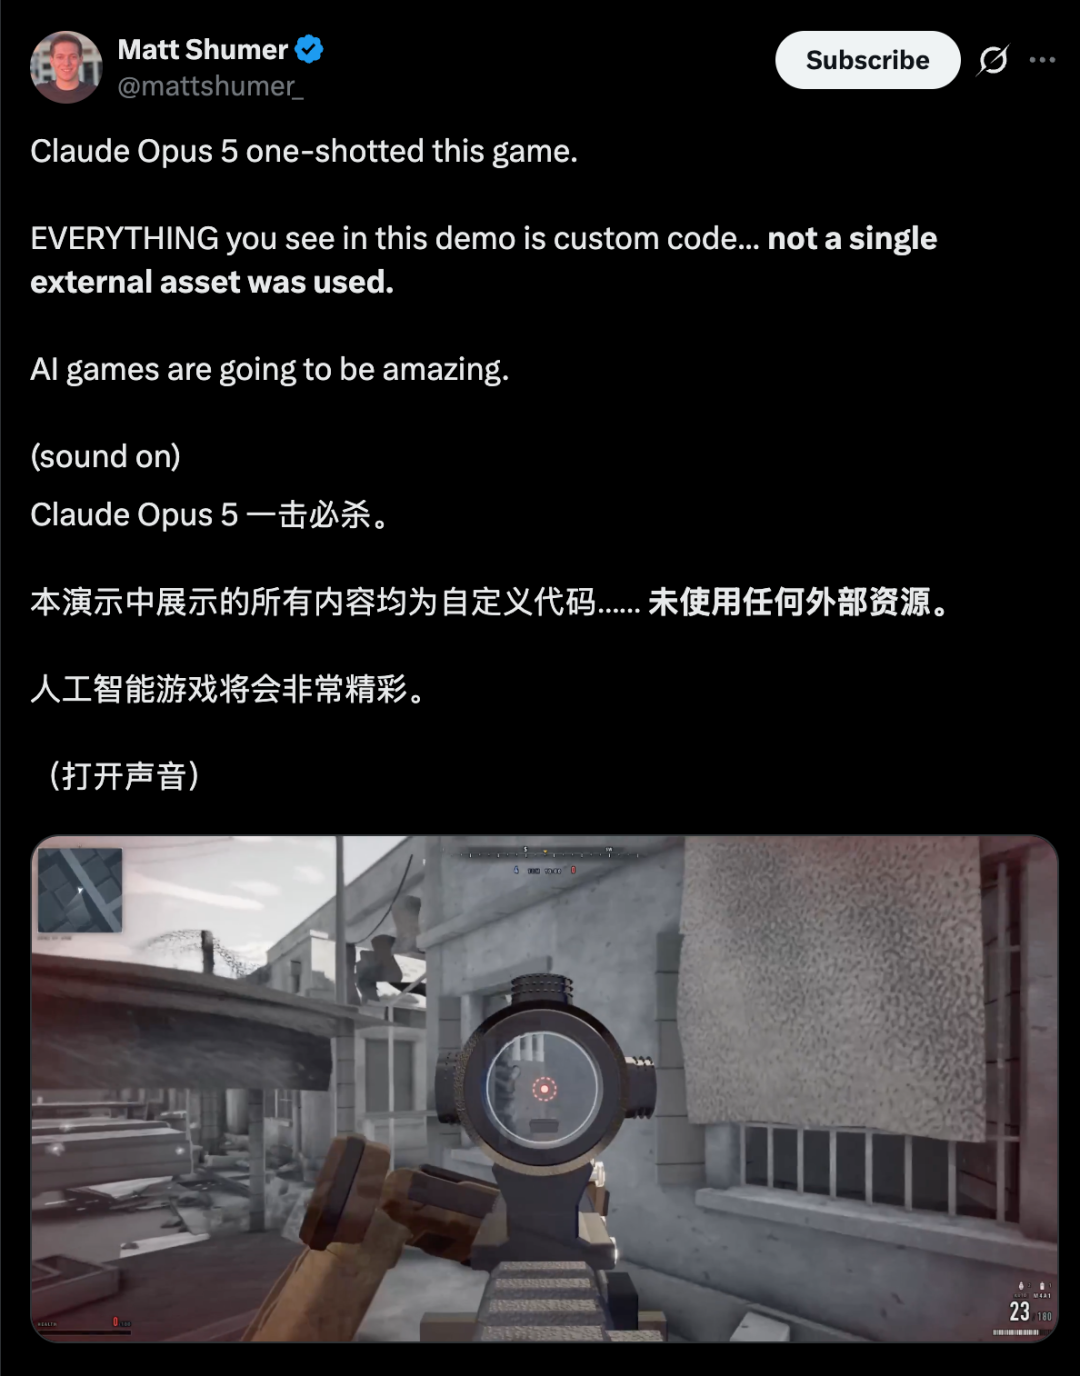
Matt Shumer popularized the method after using Claude Code with Opus 5 to create a browser-based first-person shooter inspired by modern Call of Duty games. He later published the prompt, source code, and an explanation of the workflow.
Another developer, Anshu Chimala, adapted a similar workflow to build The Long Silence, a procedural space-exploration game running in the browser.
These projects should be described accurately. They do not show that one prompt can instantly produce a commercial AAA game. They show that a strong coding agent, given tools, subagents, long-running execution time, measurable quality gates, and repeated verification, can push a prototype much further than a conventional one-shot prompt.
Shumer’s original task set an intentionally extreme target: build a first-person shooter with the visual ambition of a modern AAA title.
The critical part was not the genre. It was the evaluation structure.
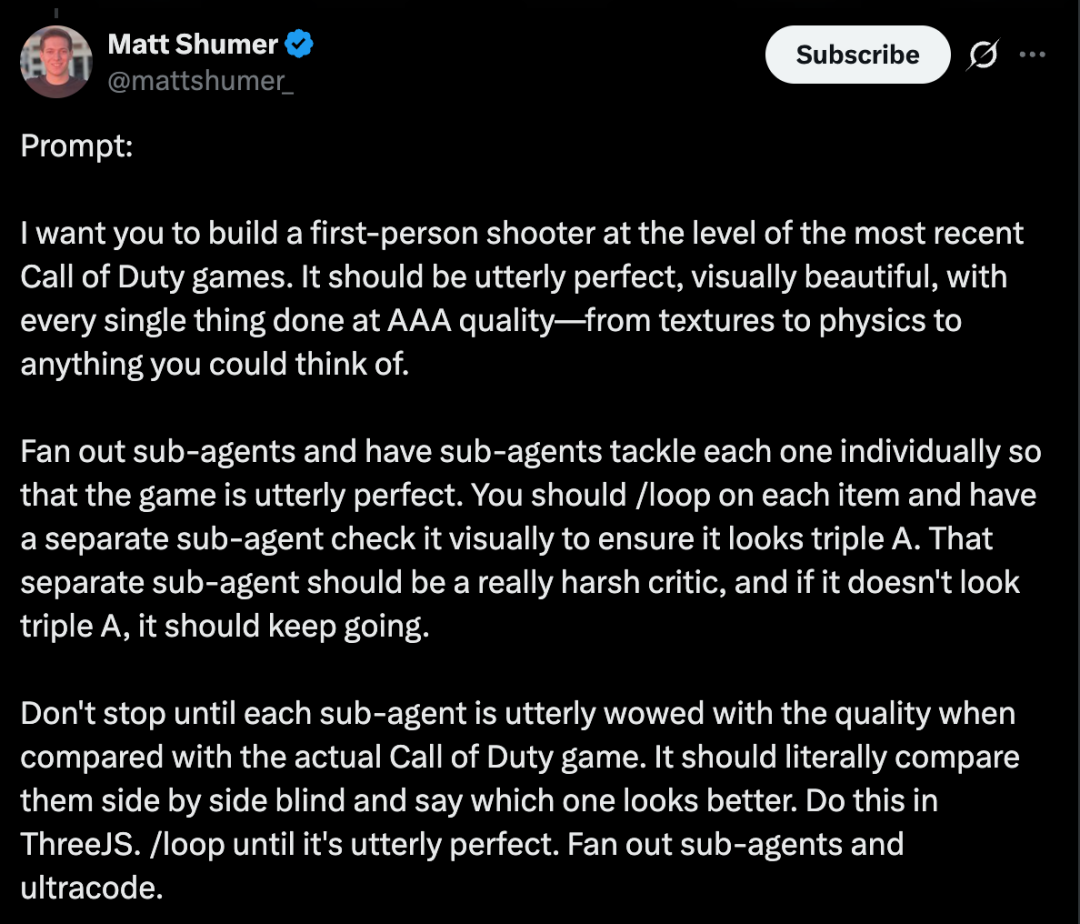
The workflow told the agent to:
Shumer later formalized the approach as the Gauntlet Loop.
A simplified version looks like this:
Goal
  ↓
Lead Agent
  ↓
Task Decomposition
  ↓
Builder Agent
  ↓
Real Output
  ↓
Independent Critic
  ↓
Compare Against Reference
  ↓
Pass? ── Yes → Integrate
  │
  No
  ↓
Explain Biggest Gap
  ↓
Builder Improves It
  ↓
Repeat
“Make it better” is weak feedback because the model must invent its own definition of better.
A Gauntlet Loop instead gives the critic something external to compare against.
For a game, that may be screenshots from a polished commercial title.
For a website, it could be several leading sites in the same category.
For backend engineering, it might be:
The target does not need to be fully reachable. Its purpose is to prevent the agent from declaring success too early.
The second key rule is independence.
The builder knows why it made each choice and can easily rationalize its own result. A fresh critic receives the actual artifact without that implementation history.
For visual work, the critic can inspect rendered pixels.
For software, it can inspect tests and runtime behavior.
For performance work, it can inspect real measurements.
The broader principle is that generation and evaluation should be separate jobs.
Shumer’s original demonstration was released publicly as Claude of Duty.
Its GitHub repository describes a Three.js and WebGL2 first-person shooter containing roughly 55,000 lines of code across 11 subsystems.
The repository says it uses no external art assets. Textures, meshes, animations, and sounds are generated procedurally from code.
Its systems include:
Calling the project “one-shot” does not mean all of that appeared in one response. According to Shumer, one high-level prompt launched a long-running Claude Code session that then spawned subagents, wrote files, ran tools, rendered the game, inspected outputs, and kept revising.
The repository contains tools for:
Its own README is also more cautious than some viral posts: it explicitly says the final project does not match a modern Call of Duty title.
That makes the experiment more useful. The real result is not “AI already replaced a AAA studio.” It is that a deliberately high reference can keep an agent working well beyond the point where a normal prompt would stop.
Anshu Chimala then applied a similar workflow to The Long Silence, a procedural browser space-exploration game built with Claude Opus 5.
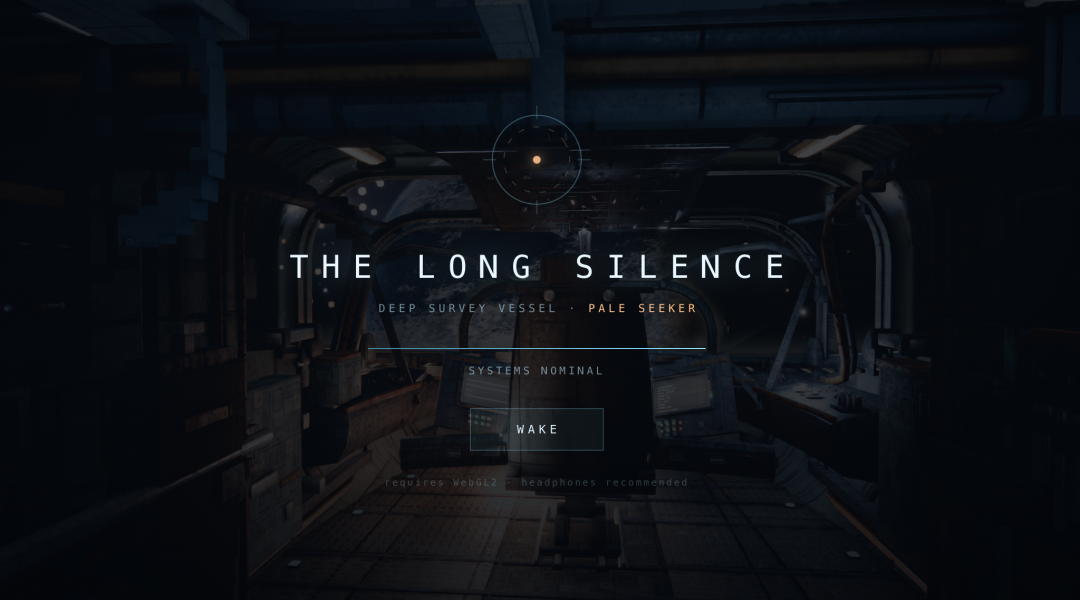
The public repository says the game uses WebGL2, Three.js-style browser rendering, custom GLSL, and seeded procedural content rather than a conventional library of downloaded art assets.
The source article describes a roughly 24-hour development process with three main stages.
The first request was to create a space-exploration game with Three.js.
The requirements were intentionally high-level:
Much of the world-building and technical architecture was left to the agent.
This follows a central rule of the method:
Define the destination more clearly than the route.
The source also reports that Claude Code was connected to Blender-related tooling during the process. The public repository includes a Claude skill directory for Blender hard-surface work, confirming that reusable Blender instructions became part of the project.
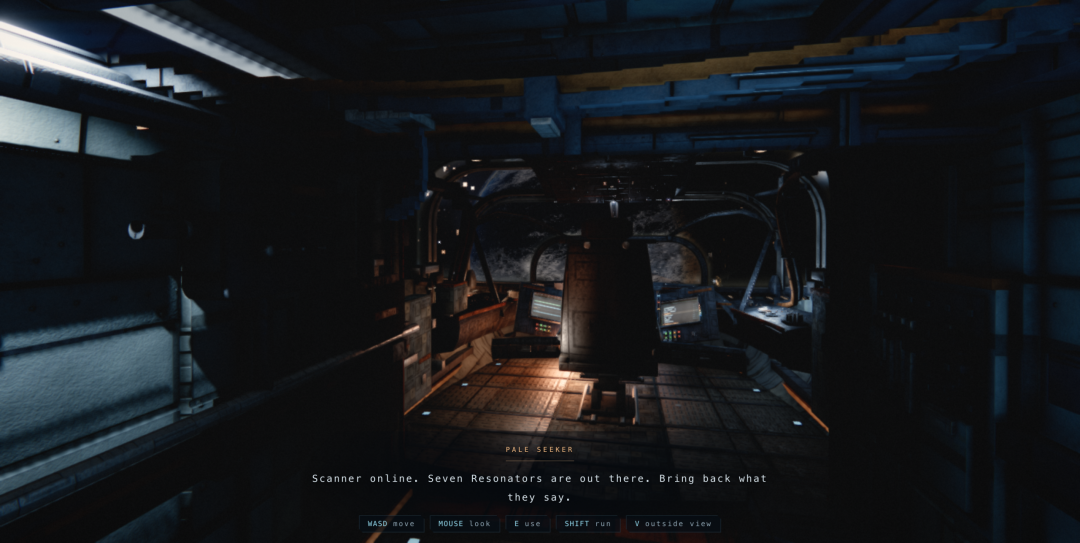
Once the first playable build existed, the project shifted into a long visual-refinement stage.
Several subagents worked on separate areas while a critic compared screenshots with polished space-game references.
The point was not simply to tell Opus 5 to “make the game prettier.” The critic needed to identify visible gaps and send weak areas back for another iteration.
The source says references such as Starfield were used as a quality bar.
A long loop also needs a stop condition. Useful stopping points include:
The loop is a pressure mechanism, not proof that the output eventually becomes “perfect.”
The process was not completely hands-off.
According to the source article, Chimala checked progress remotely and intervened when the agent spent too much effort on one area.
After the long run ended, additional Claude sessions were used to:
The model was then asked to summarize reusable lessons into a skill.
The public repository includes:
.claude/skills/blender-hardsurface
That is a useful pattern for long-running agent work. A project can produce not only an artifact, but also reusable operating knowledge: what tools worked, which tests mattered, what failed, and how future tasks should be structured.
One of the strongest parts of the public repository is the verification tooling.
The README documents commands including:
node tools/play.mjs
node tools/survey.mjs
node tools/probe.mjs "" --shot out.png
node tools/sheet.mjs a.png b.png --out s.png
node tools/levels.mjs shots/*.png
node tools/judgeset.mjs
Their documented roles include:
play.mjs: 17 interaction assertions covering flight, scanning, folding, and jumpingsurvey.mjs: screenshots of major set pieces plus performance reportingprobe.mjs: one browser expression and one screenshotsheet.mjs: contact sheets for visual comparisonlevels.mjs: tone and exposure statisticsjudgeset.mjs: rebuilding the visual review set
The important point is that the agent did not only create the game. It also created machinery for judging the game.
That is one reason a long-running agent can improve more reliably than a simple generate-and-stop workflow.
The README documents several practical graphics decisions:
The repository also says browser verification runs against a real Chromium instance with GPU rasterization.
These details matter because they show the model working through familiar engineering constraints: performance, precision, repeatability, browser behavior, and visual quality.
The Long Silence is publicly playable in a browser.
Its repository provides standard development commands:
npm install
npm run dev
npm run build
The game includes spaceflight, scanning, procedural environments, navigation, exploration objectives, and multiple interface systems.
That makes it more than a static mockup.
It is still not equivalent to a commercial AAA game created by a large studio over several years.
A AAA production typically includes large teams for:
The more defensible conclusion is that one developer can now orchestrate frontier coding agents to create a visually ambitious, technically nontrivial playable prototype far faster than would previously have been practical.
Once Shumer published the prompt and code, the workflow spread.
Describe your idea once, and We0 AI can generate a showcase site, pages, and CMS, then help you attract customers and traffic after launch.
One complete project generation for free registration
Best for trying one complete generation flow and seeing a first project draft quickly.
Ryan Campbell applied a similar loop to a browser kart-racing project, iterating on rendering, controls, camera behavior, and mobile performance.
Shumer’s public Gauntlet Loop directory later highlighted browser-playable racing experiments produced with the method.
Designer Yogi Suria shared a cyberpunk-style Three.js project inspired by the same prompt pattern.
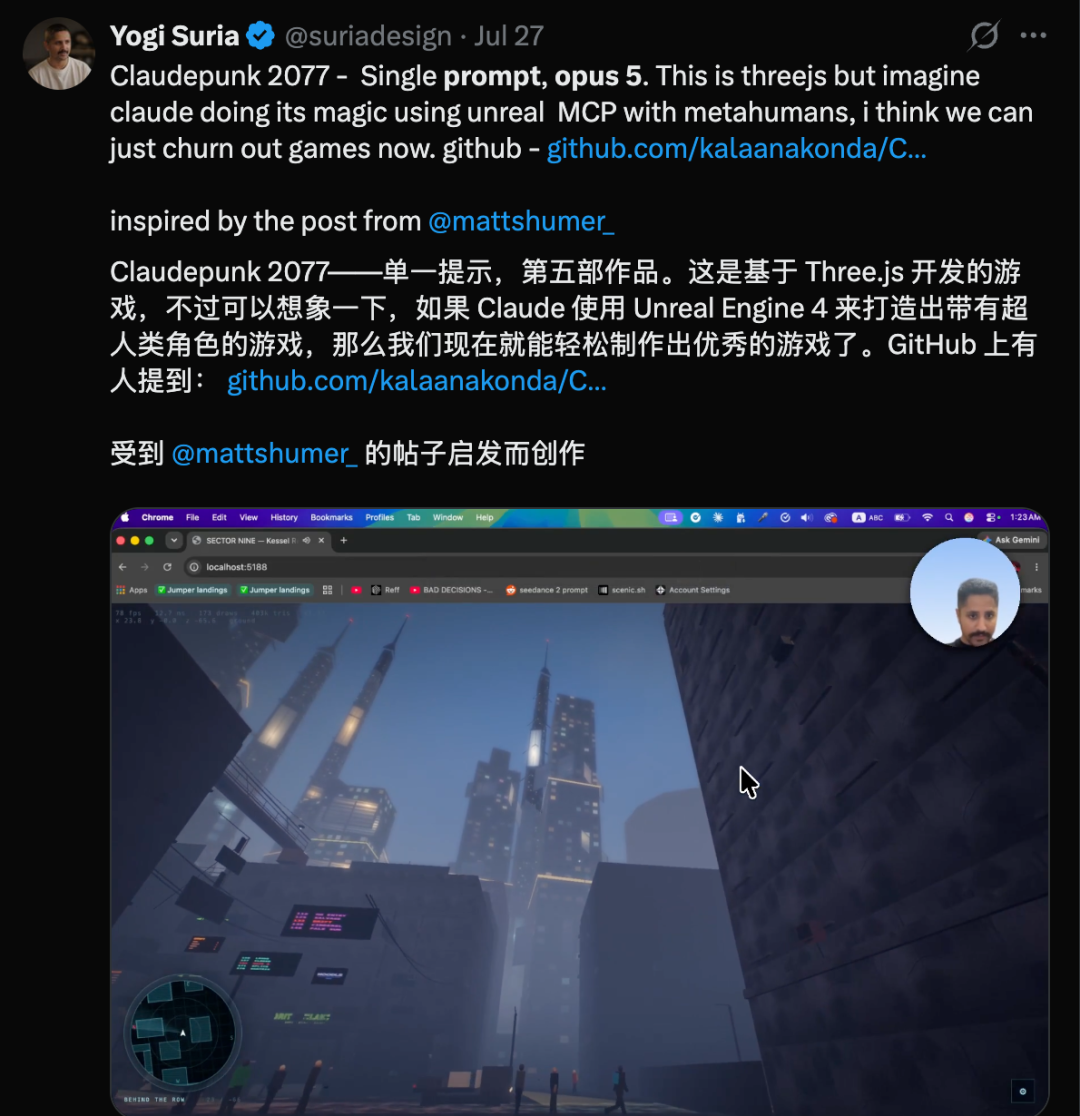
The example shows that the method is not tied to one genre. The reference target, art direction, and toolchain can change while the build–criticize–repeat structure stays the same.
The source also shows a developer testing a similar prompt with GPT-5.6 Sol through Codex.
The developer reported a build time of roughly two hours and described the result as good, though less polished than Shumer’s demo.
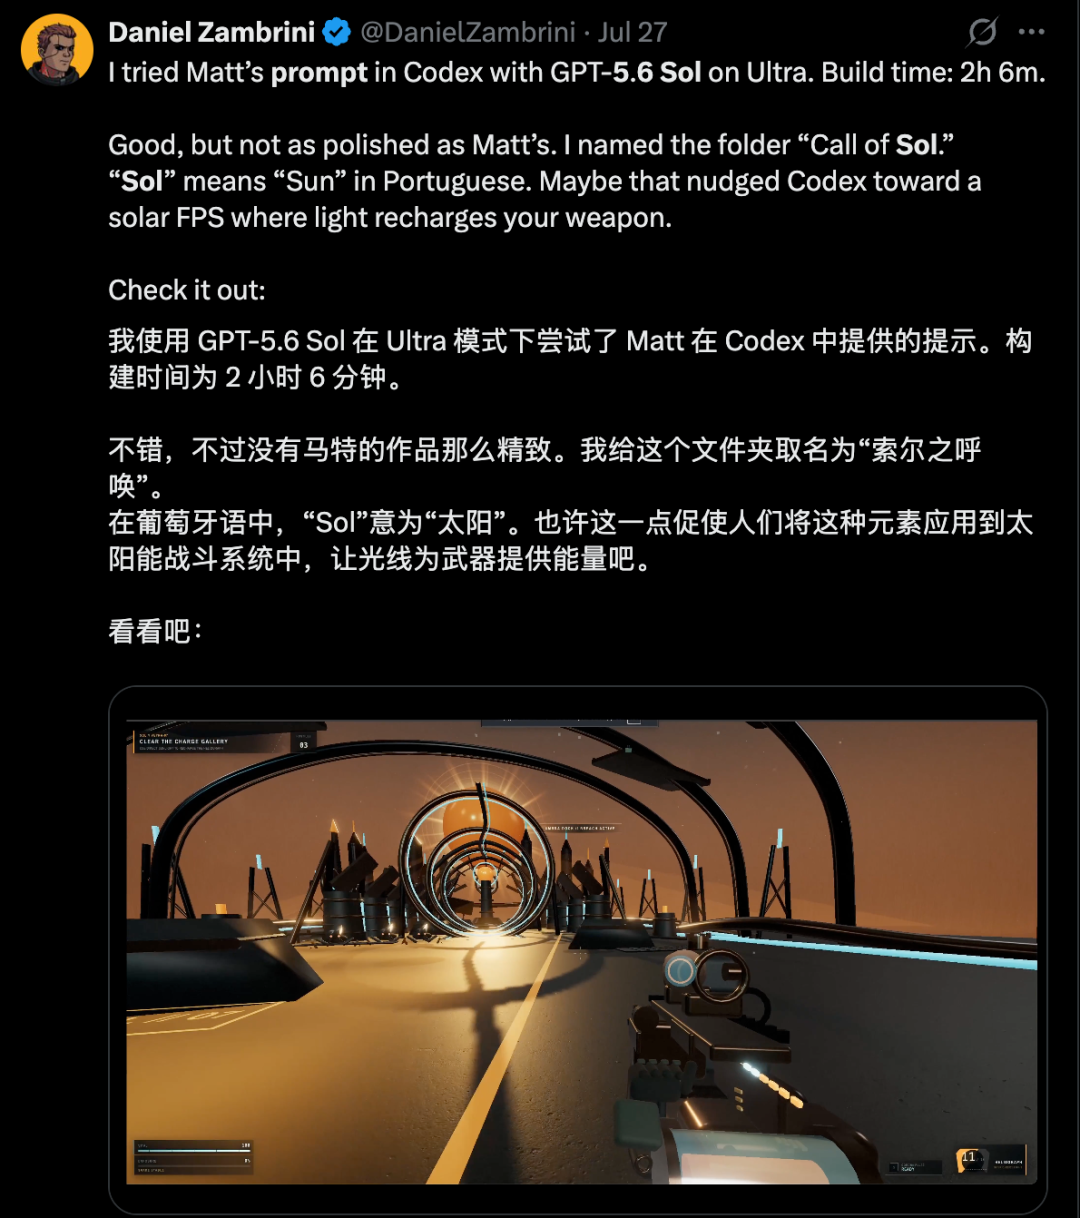
That suggests the Gauntlet Loop is not inherently Claude-specific.
The pattern depends on an agentic environment that can:
Different models may perform differently inside the loop, but the architecture is portable.
A conventional generation flow often looks like this:
User → Model → Output → User
The Gauntlet Loop adds an evaluation layer:
User
  ↓
Lead Agent
  ↓
Builder
  ↓
Artifact
  ↓
Independent Critic
  ↓
Measured Gap
  ↓
Builder Revision
  ↓
New Artifact
This creates more opportunities to catch weak output before delivery.
An agent saying “the page should now be responsive” is weaker than opening the page at mobile width and checking it.
“The game should be faster” is weaker than measuring frame time.
“The rendering looks better” is weaker than comparing screenshots.
The best feedback signal is grounded in the real artifact.
The builder remembers every compromise it made.
That can bias the review.
A separate critic can ask a simpler question: does the result actually meet the bar?
This mirrors human workflows. Developers use tests and code review. Designers use visual review and user testing. Writers use editors.
AI agents can reproduce that separation at much higher frequency.
Anthropic released Claude Opus 5 on July 24, 2026.
Its official launch material emphasizes stronger performance on coding, long-running multi-step work, verification, and iteration.
Anthropic specifically reports that Opus 5 is better at:
Those behaviors line up closely with the Gauntlet Loop.
The prompt does not give the model a new capability. It creates a structure that repeatedly forces the model to use capabilities it already has.
Anthropic also presents Opus 5 as more efficient than Opus 4.8 at the same base price: $5 per million input tokens and $25 per million output tokens.
Long-running agents can still suffer from:
That is why human checkpoints remain useful.
The strongest workflow is not “never look at the agent again.” It is “let the agent work for much longer between high-value human interventions.”
The method can be generalized beyond games.
Describe the outcome rather than prescribing every implementation detail.
Build a polished browser-based space exploration game with smooth controls,
strong visual atmosphere, and stable performance.
Use something the critic can inspect.
For visual work:
Compare lighting, depth, composition, and interface polish against a selected
set of high-quality commercial game screenshots.
For software, use tests, benchmarks, or a reference implementation.
The agent can separate components such as:
For important components, use:
The critic should identify the biggest actionable difference instead of producing a long list of vague complaints.
Continue until quality, budget, or time reaches the stopping point.
Parallel agents can create locally good but globally inconsistent work.
A final integration agent can inspect:
Store the useful parts of the process as:
Future runs should start with the lessons from earlier ones.
A Gauntlet Loop is strongest when quality can be measured repeatedly.
Good candidates include:
It is weaker when the critic has no reliable signal.
A critic without screenshots, tests, benchmarks, references, or real user feedback can become just another model producing opinions.
Long-running multi-agent workflows can consume substantial compute.
Each review round may require:
Useful budget controls include:
A strict critic can improve quality, but it can also keep the system working long after the remaining improvement is worth the cost.
The Gauntlet Loop is a multi-agent prompting method popularized by Matt Shumer. A lead agent divides a goal into smaller tasks, builder agents create the work, separate critics compare the real output against a concrete reference, and weak results are sent back for another iteration.
The project began from one high-level prompt, according to Shumer, but it was not produced in one model response. Claude Code then worked for many hours, spawned subagents, wrote roughly 55,000 lines of code, used tools, inspected outputs, and iterated.
No. The demos are technically impressive browser games and prototypes, but they are not equivalent to commercial AAA releases. The Claude of Duty repository itself says the final result does not match the modern Call of Duty title used as its quality reference.
The Long Silence is a procedural browser-based space-exploration game by Anshu Chimala. Its public repository says it was built with Claude Opus 5 and includes custom rendering, procedural content, and browser-based verification tooling.
A fresh critic is less likely to defend the builder’s own implementation decisions. It can inspect the actual artifact and compare it with tests, screenshots, benchmarks, or reference examples before requesting another revision.
No. The architecture can be applied to other coding agents that support tools, file editing, code execution, visual inspection, and repeated work. The source article includes a GPT-5.6 Sol and Codex example.
You need an agentic harness rather than a normal chat interface for the full workflow. Claude Code is one option because it can work with files, run commands, connect to tools, and coordinate long-running coding tasks.
A long loop can waste time and compute when the quality bar is vague or impossible to measure. Human owners should still set budgets, inspect progress, reprioritize when necessary, and decide when further iteration has stopped being valuable.
The viral Opus 5 game experiments are better understood as demonstrations of a workflow than as magical one-shot generation. The Gauntlet Loop combines task decomposition, specialist builders, independent critics, concrete quality bars, and repeated iteration.
The Long Silence shows how far that pattern can go in a roughly day-long agentic project. Its public repository includes not just a playable game but also verification scripts, screenshot tools, interaction assertions, and reusable agent instructions.
The method still depends on human judgment, compute budgets, good references, and an agentic harness. It does not make a browser prototype equivalent to a studio-produced AAA game.
The real shift is that one high-level goal can now launch a long-running build–measure–criticize–improve loop that completes far more work before the human needs to intervene.
Start from one sentence and have a complete website in minutes.



