DeepSeek V4 Flash 0731 has created an unusual combination of reactions. Developers are impressed by its coding-agent scores. Infrastructure ...
DeepSeek V4 Flash 0731 has created an unusual combination of reactions.
Developers are impressed by its coding-agent scores.
Infrastructure teams are interested in its 1-million-token context and low active parameter count.
AI platforms are offering free usage and aggressive discounts.
And social media is filling with screenshots of prototypes whose reported inference bills are measured in cents rather than dollars.
The most widely shared examples in the source article included:
These examples capture the excitement, but they can also blur several distinct things:
The model is genuinely inexpensive.
That does not mean every application will cost seven cents.
The useful question is not whether one viral demo is reproducible exactly. It is how DeepSeek achieved such a large capability jump without changing the base architecture—and what the new economics mean for developers.
The official API price was already low before third-party promotions were applied.
DeepSeek currently lists the following prices per million tokens:
| Usage type | DeepSeek V4 Flash price |
|---|---|
| Input, cache hit | $0.0028 |
| Input, cache miss | $0.14 |
| Output | $0.28 |
The API supports:
low, high, and max.Those official prices are the baseline.
Platforms can then choose to:
This is why one developer may pay DeepSeek's list price while another pays nothing for a limited period.
OpenCode publicly said DeepSeek Flash processed 8 trillion tokens on August 1 through its platform.
The post breaks the figure down as:
5T tokens of free usage
+
3T tokens through OpenCode Go
OpenCode's August 3rd tweet shows DeepSeek Flash processed 8 trillion tokens on August 1st—5 trillion free, 3 trillion via OpenCode Go. The tweet is an official statement of those figures, breaking down free versus paid usage and supporting context around DeepSeek Flash's token processing volume.
OpenCode's current Zen documentation lists a DeepSeek V4 Flash Free option available for a limited time.
This is an important distinction.
The eight-trillion-token figure describes traffic through OpenCode, not direct usage reported by DeepSeek across every platform.
It is still a strong signal that low-cost models can generate enormous demand when they are placed inside a popular coding-agent workflow.
Nous Research announced a seven-day promotion offering DeepSeek V4 Flash 0731 at a 90% discount through Nous Portal in partnership with Novita Labs.
The promotional post compared the discounted cost with Claude Fable 5 and claimed a more than 1,000-fold price difference on comparable tasks.
That comparison depends on several choices:
A price-per-token comparison is useful, but the more meaningful metric is:
Total cost per accepted task
A model that uses fewer expensive tokens can be cheaper than a low-priced model that retries repeatedly.
Conversely, when a low-priced model is also capable enough to finish the task quickly, the cost advantage can become enormous.
Cline initially announced free V4 Flash 0731 usage through its coding agent.
A later public post said the free quota had been tripled because the economics appeared sustainable.
Cline's current model catalog and ClinePass material include DeepSeek V4 Flash as a fast, value-oriented option for focused coding tasks.
Free quotas and model availability can change, so users should check the live provider page rather than relying on an old screenshot.
The broader lesson is more durable.
When inference becomes cheap enough, an agent platform can use free access as customer acquisition without absorbing
the same cost it would face with a premium frontier model.
The source article includes a dashboard showing:
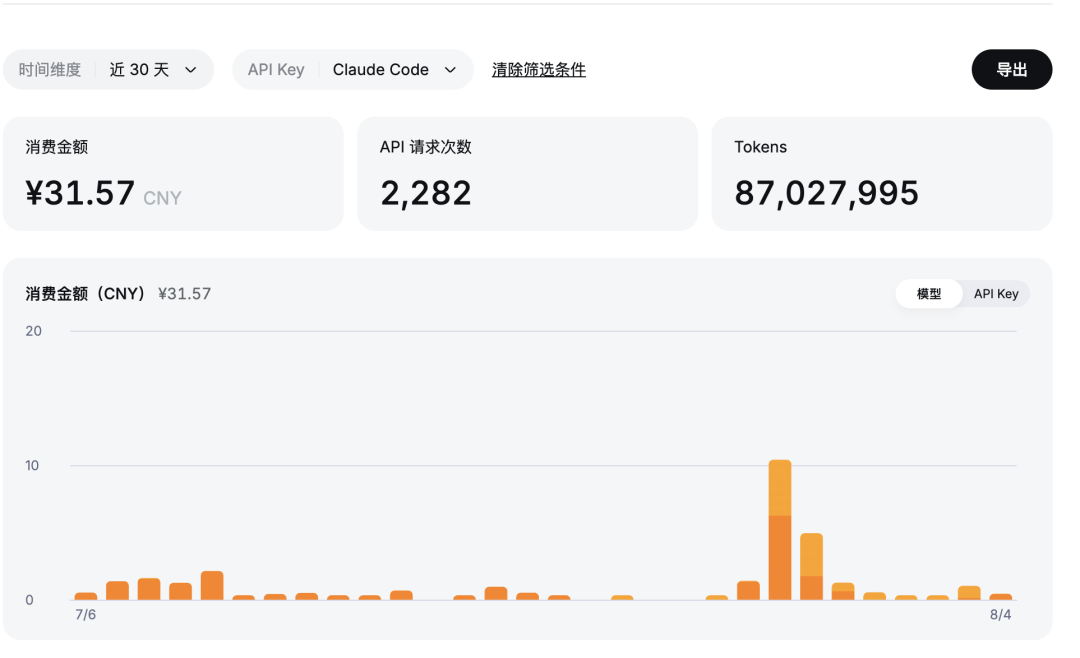
The screenshot is useful because it demonstrates the order of magnitude developers may see under favorable usage patterns.
It does not reveal enough information to reconstruct the bill exactly.
Missing variables include:
A long repeated system prompt can be extremely cheap when it hits cache.
A long unique prompt sent once is billed at the cache-miss input price.
Output is also much more expensive than cached input.
For agent systems, these differences dominate the final bill.
DeepSeek V4 Preview launched on April 24, 2026.
The family contained:
The Preview release established the main architecture:
V4 Flash Preview was positioned as the smaller, faster, cheaper alternative to V4 Pro.
The July 31 update changed its competitive position.
DeepSeek states that V4 Flash 0731 uses the same model architecture and size as V4 Flash Preview.
The update was produced by running a new post-training process.
In simplified form:
Same pretrained base architecture
+
new post-training and agent optimization
=
much stronger coding-agent behavior
This matters because it shows how much capability can remain latent in a pretrained model.
Architecture and parameter count are not the whole product.
Post-training determines how effectively the model:
The original V4 Flash model card describes the base model as:
| Specification | DeepSeek V4 Flash |
|---|---|
| Total base MoE parameters | 284B |
| Activated parameters | 13B |
| Context length | 1M |
| License | MIT |
| Main modality | Text |
| Base precision | FP8 / mixed low precision depending on checkpoint |
The 0731 model card says the new release has the same structure as the DSpark variant and includes an attached speculative-decoding module.
This explains why some model-file metadata may show
Compared to the 284B-base MoE figure, the total checkpoint count is now larger.
The cleanest way to put it is:
V4 Flash’s underlying MoE model remains roughly 284B total parameters with 13B active, while the 0731 release adds the DSpark speculative-decoding component to the published checkpoint.
Speculative decoding uses a fast draft model to propose several future tokens.
The main model then verifies those proposals.
When predictions are accepted, the system can generate multiple tokens with less sequential work.
DeepSeek’s 0731 model card provides explicit DSpark support for vLLM and SGLang.
For vLLM, the relevant configuration is:
--speculative-config '{"method":"dspark","num_speculative_tokens":7,"draft_sample_method":"greedy"}'
For SGLang, the model card uses:
--speculative-algorithm DSPARK
DSpark does not improve the model’s reasoning by itself.
It is an inference optimization intended to reduce decoding latency or increase throughput while preserving the target model’s output distribution under the supported configuration.
DeepSeek publishes the following comparison for V4 Flash 0731:
| Benchmark | V4 Flash 0731 | V4 Flash Preview | V4 Pro Preview |
|---|---|---|---|
| Terminal Bench 2.1 | 82.7 | 61.8 | 72.1 |
| NL2Repo | 54.2 | 39.4 | 38.5 |
| CyberGym | 76.7 | 38.7 | 52.7 |
| DeepSWE | 54.4 | 7.3 | 12.8 |
| Toolathlon-Verified | 70.3 | 49.7 | 55.9 |
| Agents’ Last Exam | 25.2 | 15.8 | 16.5 |
| AutomationBench Public | 25.1 | 10.8 | 12.8 |
| DSBench-FullStack | 68.7 | 37.0 | 41.8 |
| DSBench-Hard | 59.6 | 25.8 | 31.1 |
The most dramatic increase is DeepSWE:
7.3 → 54.4
CyberGym nearly doubles:
38.7 → 76.7
Terminal Bench 2.1 rises by more than twenty points:
61.8 → 82.7
The new Flash model also exceeds V4 Pro Preview on every benchmark in DeepSeek’s published table.
That is a major change for a model originally positioned mainly as the cheaper and faster option.
The table should not be read as a pure comparison of raw checkpoints.
DeepSeek’s model card includes several important notes.
For public code-agent tasks, the company used:
DeepSeek Harness minimal mode
Reasoning effort: max
Temperature: 1.0
Top-p: 0.95
DeepSeek Harness had not been publicly released at the time of verification.
This means outside researchers may not yet be able to reproduce the exact software environment used for the published code-agent results.
Two tests are also internal:
Internal benchmarks can be useful for product development, but independent teams cannot inspect their hidden tasks or contamination controls.
The correct interpretation is:
DeepSeek reports a large improvement under its chosen agent stack and evaluation setup. Public reproducibility will improve when the harness, prompts, logs, and complete evaluation configuration become available.
A coding benchmark often measures a complete system:
Model
+
system prompt
+
repository tools
+
terminal
execution
+
context management
+
retry policy
+
test feedback
+
patch submission logic
The same model can score differently when one component changes.
A better harness may:
This does not make the model irrelevant.
It means the benchmark result belongs to the model-and-harness combination.
The strong 0731 numbers suggest DeepSeek improved both the model’s agent behavior and the surrounding evaluation process.
Artificial Analysis reports an Intelligence Index score of approximately 50 for DeepSeek V4 Flash 0731, around ten points above the previous Flash version.
The independent model-analysis firm also describes V4 Flash as exceptionally inexpensive relative to other well-known frontier systems.
Reuters summarized Artificial Analysis’s findings by reporting an average benchmark-test cost of roughly three U.S. cents under its methodology.
That comparison supports the value argument.
It does not mean every production task costs three cents.
Artificial Analysis also reports weaker results on some knowledge-reliability measures.
Its V4 Flash 0731 article notes:
Those figures are a useful reminder.
A model can be:
“Best value” is not the same as “best for every task.”
The direct DeepSeek API price is:
| Billing category | Price per 1M tokens |
|---|---|
| Cache-hit input | $0.0028 |
| Cache-miss input | $0.14 |
| Output | $0.28 |
The pricing gap between a cache hit and cache miss is enormous:
$0.14 ÷ $0.0028 = 50
Cached input is fifty times cheaper than uncached input.
For long-running agents, prompt structure becomes cost architecture.
Assume one request uses:
100,000 uncached input tokens
20,000 output tokens
The direct model cost is:
Input:
100,000 / 1,000,000 × $0.14
= $0.014

Output:
20,000 / 1,000,000 × $0.28
= $0.0056

Total:
$0.0196
That is less than two U.S. cents.
Now assume the same 100,000-token prefix is cached:
Cached input:
100,000 / 1,000,000 × $0.0028
= $0.00028

Output:
20,000 / 1,000,000 × $0.28
= $0.0056

Total:
$0.00588
The output now dominates the bill.
These examples explain why low-cost coding prototypes are plausible.
They do not include:
Agentic coding is rarely one request.
A typical workflow may include:
failure.
7. Edit again.
8. Run tests again.
9. Review the diff.
10. Produce the final answer.
Every step may create another model call.
A seemingly small task can become expensive when:
V4 Flash reduces the price of these mistakes.
It does not eliminate them.
DeepSeek uses disk-based context caching.
When the same prefix is reused, the matching input tokens can receive the lower cache-hit price.
Good candidates for a stable prefix include:
A simplified prompt design is:
Stable reusable prefix
+
new user request
+
latest tool result
A less cache-friendly design is:
Reordered instructions
+
rewritten repository summary
+
changing timestamps
+
random request metadata
+
new user request
Small prefix changes can reduce cache reuse.
Developers should inspect token-usage fields rather than assuming a long prompt was cached.
DeepSeek also offers user_id isolation for privacy and scheduling. Cache reuse and user isolation should be designed together so one customer’s context is not accidentally mixed with another’s.
The official base URL remains:
https://api.deepseek.com
The model ID is:
deepseek-v4-flash
DeepSeek says the stable API ID automatically serves the latest official Flash version.
That is convenient, but production teams should record the returned model fingerprint and test changes because the behavior behind a stable ID can be upgraded.
Describe your idea once, and We0 AI can generate a showcase site, pages, and CMS, then help you attract customers and traffic after launch.
One complete project generation for free registration
Best for trying one complete generation flow and seeing a first project draft quickly.
from openai import OpenAI

client = OpenAI(
    api_key="YOUR_DEEPSEEK_API_KEY",
    base_url="https://api.deepseek.com",
)

response = client.chat.completions.create(
    model="deepseek-v4-flash",
    messages=[
        {
            "role": "user",
            "content": "Review this function and propose a safe refactor.",
        }
    ],
)

print(response.choices[0].message.content)
curl https://api.deepseek.com/chat/completions \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $DEEPSEEK_API_KEY" \
  -d '{
    "model": "deepseek-v4-flash",
    "messages": [
      {
        "role": "user",
        "content": "Write a small Python CLI that validates JSON files."
      }
    ]
  }'
Developers should check the live API reference for the exact reasoning-effort and thinking-mode fields supported by their endpoint and SDK version.
DeepSeek’s thinking-mode documentation says that when a turn includes tool calls, the reasoning_content from the assistant message must be passed back in subsequent requests.
A multi-turn agent should preserve:
contentreasoning_content
tool_callsDropping the reasoning state may reduce continuity or cause request-validation problems.
This is especially relevant when integrating through an OpenAI-compatible client that normally ignores provider-specific reasoning fields.
DeepSeek provides more than one interface.
Use the standard DeepSeek base URL and the model ID:
deepseek-v4-flash
DeepSeek also documents an Anthropic-format interface.
This can help software built around Claude-style messages connect to DeepSeek with fewer application changes.
Compatibility does not guarantee identical behavior.
Provider-specific fields, reasoning history, tool schemas, safety behavior, and error handling still require testing.
DeepSeek says the 0731 release natively supports the Responses API format and has been adapted for Codex-style use.
This matters for coding-agent products that increasingly depend on stateful response objects, tool calls, and structured agent loops.
DeepSeek has released V4 Flash 0731 weights on Hugging Face under the MIT License.
That allows developers to inspect, modify, deploy, and redistribute the model subject to the license terms.
The open-weight release provides more control than an API-only model.
Teams can:
The practical barrier is hardware.
“Open weights” does not mean “runs on a normal laptop.”
The official 0731 model card provides a vLLM example for a single 4×GB300 node:
vllm serve deepseek-ai/DeepSeek-V4-Flash-0731 \
  --trust-remote-code \
  --kv-cache-dtype fp8 \
  --block-size 256 \
  --data-parallel-size 4 \
  --enable-expert-parallel \
  --moe-backend deep_gemm_mega_moe \
  --attention-config '{"use_fp4_indexer_cache": true}' \
  --speculative-config '{"method":"dspark","num_speculative_tokens":7,"draft_sample_method":"greedy"}'
This example demonstrates the infrastructure class expected for full-quality serving.
It should not be interpreted as the only supported configuration.
The vLLM recipe may add support for other GPU topologies over time.
The official SGLang example is:
sglang serve \
  --trust-remote-code \
  --model-path deepseek-ai/DeepSeek-V4-Flash-0731 \
  --tp 4 \
  --moe-runner-backend flashinfer_mxfp4 \
  --speculative-algorithm DSPARK \
  --mem-fraction-static 0.90 \
  --chunked-prefill-size 4096 \
  --swa-full-tokens-ratio 0.1
The target and draft weights come from the same checkpoint, so the documentation says not to set a separate speculative draft-model path.
Inference engines evolve quickly.
Use the current model card and serving-engine recipe rather than copying an old launch command from the Preview release.
Even though only about
For any given token, 13B parameters are active, meaning the complete model weights must remain available throughout the serving system.
Deployment planning must account for:
Smaller quantizations may enable experimentation on different hardware, but they can alter quality, speed, or supported context length.
For most individual developers, using the direct API or a hosted provider will be easier and more cost-effective than self-hosting.
There are three common ways to use V4 Flash.
| Route | Main advantage | Main trade-off |
|---|---|---|
| DeepSeek API | Official pricing and current official model | Data leaves your environment; stable ID may be updated |
| Third-party platform | Free quotas, integrated agents, easier billing | Promotions and routing can change |
| Self-hosted weights | Maximum control and privacy | Significant hardware and engineering requirements |
The most cost-effective route depends on your workload.
A free Cline or OpenCode quota may be ideal for experimentation.
The direct API may be best for predictable, small-scale usage.
Self-hosting may only become attractive with sufficiently high, sustained volume or when privacy requirements take priority.
The source article compares inexpensive AI to the mass production of automobiles.
The analogy is imperfect but useful.
When a technology becomes dramatically cheaper, the market doesn't simply buy the same amount for less money.
New use cases become possible.
Low-cost agent models can support experiments that would previously have been rejected before testing.
Examples include:
The value isn't that the model replaces all software engineering.
It lowers the cost of asking:
Is this idea worth building further?
Cheap generation can produce a convincing first demo.
A production product still requires:
A seven-cent model bill doesn't mean a seven-cent business.
It means the first computational experiment may be cheap enough to attempt.
That changes who can participate and how many ideas can be tested.
The source article includes a lightweight document workspace shown as one example of what developers were building with inexpensive coding agents.
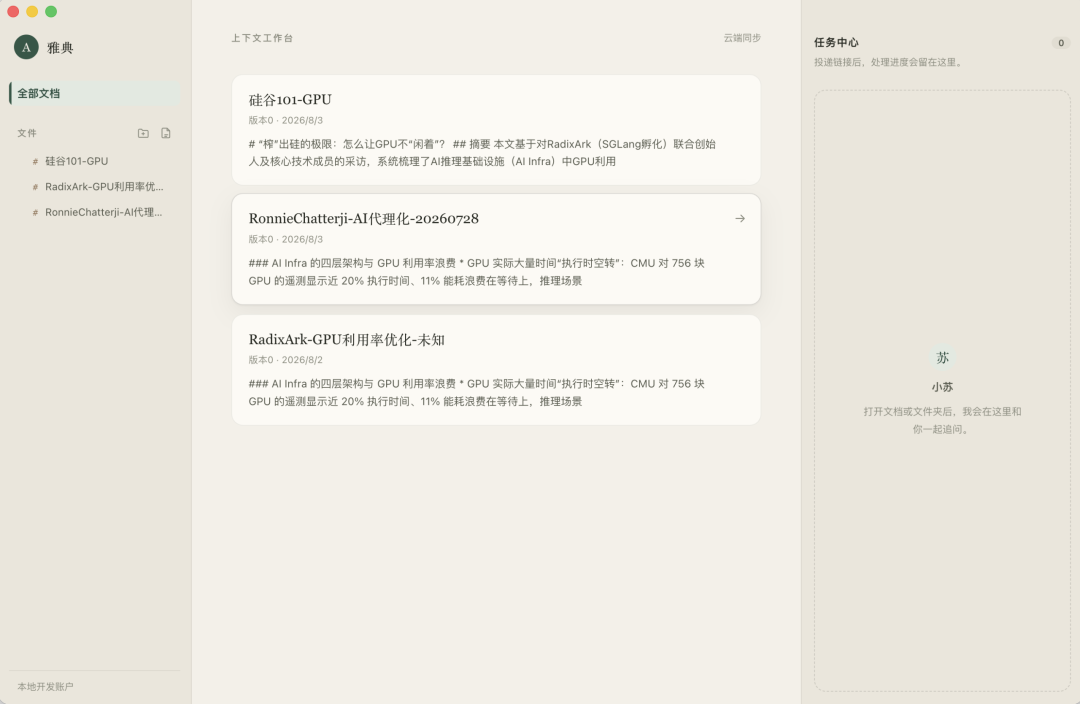
A screenshot cannot establish how much of the application was produced by the model, how much human editing was required, or whether the product is secure and maintainable.
It does show the kind of project that low-cost coding models make easier to prototype.
V4 Flash 0731 is especially attractive when:
It may be less suitable when:
A model router can combine Flash with a stronger or more specialized system.
For example:
Routine repository edits
→ V4 Flash

High-risk architecture or security decisions
→ stronger model + human review
When model calls are expensive, developers try to minimize every request.
When calls become cheap, an agent can afford to:
This can increase reliability.
It can also waste tokens.
The right objective is not minimum token usage.
It is:
Lowest total cost that reaches the required quality
DeepSeek describes the official Flash API as a public beta.
Pricing, behavior, limits, and model versions may change.
Production teams should maintain regression tests.
The strongest code-agent results use an unreleased harness configuration.
Exact independent reproduction is not yet straightforward.
Output, retries, tools, and uncached context can dominate the final cost.
A 1-million-token window is a capacity limit, not a recommendation to send one million tokens in every request.
Large prefill workloads increase latency and cost.
Independent evaluation shows that value and coding strength can coexist with a high hallucination rate on factual tests.
Critical facts should be checked against sources.
Low-cost models can generate more code than a team can safely inspect.
Automated tests, static analysis, dependency scanning, and human review remain necessary.
Third-party free models and discounts can disappear.
Do not build a permanent business model around a seven-day or limited-time subsidy.
The deepseek-v4-flash model ID points to the current version.
An upgrade behind that ID may change outputs without a code change in your application.
Keep system instructions and tool definitions consistent to improve cache reuse.
Do not rely only on total input tokens.
Set a realistic output budget for the task.
Reserve max for tasks that benefit from longer deliberation.
Stop loops that are not making progress.
Use linters, tests, schema validators, and deterministic checks.
Escalate only when the task fails a test or exceeds a risk threshold.
Include failed attempts and human review.
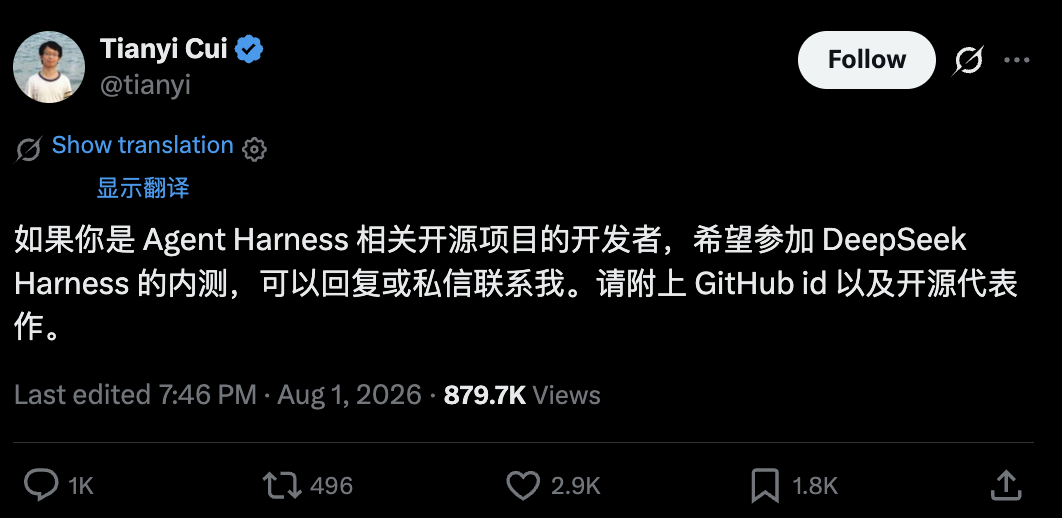
The source article ends with a possible next step in DeepSeek's developer ecosystem.
Tianyi Cui, identified in the source as the person responsible for DeepSeek Harness, posted a recruitment message for developers of open-source agent-harness projects.
The message invited interested developers to share a GitHub account and representative open-source work to participate in internal testing.
DeepSeek's own July 31 change log also says the minimal mode of DeepSeek Harness used for benchmark evaluation is "to be released soon."
As of verification, I did not locate:
The evidence supports this narrower conclusion:
DeepSeek is testing an agent harness and intends to release at least part of the framework, but the final product name, public scope, and launch timing remain unconfirmed.
The model, API, and open weights are available now.
The harness is still a future ecosystem component.
A first-party harness could help DeepSeek control the full coding-agent stack.
It could provide:
DeepSeek already documents integrations with external harnesses and coding agents.
A first-party tool could turn benchmark-specific optimizations into a product that ordinary developers can use.
It could also reveal how much of V4 Flash 0731's benchmark jump comes from the checkpoint and how much comes from the agent runtime.
Several developments will determine whether the V4 Flash moment becomes a lasting ecosystem shift.
DeepSeek says the official V4 Pro release will follow the Flash update.
The performance and pricing gap between Pro and Flash will affect routing decisions.
A public release would improve benchmark reproducibility and give developers a model-native agent framework.
The direct price is already low, but third-party promotions may not remain.
Cheap inference attracts very high traffic.
Latency, rate limits, and reliability will matter as usage scales.
vLLM, SGLang, hardware vendors, and quantization projects will determine how accessible self-hosting becomes.
More public evaluations should test:
DeepSeek V4 Flash 0731 is the official July 31 release of V4 Flash, currently served through the deepseek-v4-flash API in public beta. DeepSeek says it keeps the Preview model's base architecture and size while substantially improving agent capabilities through new post-training.
DeepSeek's official API lists $0.14 per million cache-miss input tokens, $0.0028 per million cache-hit input tokens, and $0.28 per million output tokens. Third-party platforms may offer different prices, free quotas, or temporary discounts.
The source article cites a community example with that reported model cost. The example is not accompanied by complete prompts, token logs, cache data, retries, tool costs, or human-work records, so it should be treated as an anecdote rather than a guaranteed budget.
DeepSeek reports 82.7 on Terminal Bench 2.1, 76.7 on CyberGym, 54.4 on DeepSWE, 70.3 on Toolathlon-Verified, and 54.2 on NL2Repo. Public code-agent evaluations used the unreleased minimal mode of DeepSeek Harness with maximum reasoning effort.
The model weights and repository are released under the MIT License, so "open-weight" and broadly permissive use are accurate descriptions. Running the complete checkpoint still requires substantial multi-GPU infrastructure.
Yes, DeepSeek publishes weights and serving instructions for vLLM and SGLang. The official full-scale examples use advanced multi-GPU hardware, so a normal laptop is not the target environment for the complete model.
The official API and model card specify a 1-million-token context window. The API also lists a
maximum output length of 384K tokens, but using the maximum context or output can significantly increase latency and resource use.
DeepSeek has publicly referenced a Harness minimal mode and recruited open-source harness developers for internal testing. A complete public repository, final product specification, and confirmed release date were not located during verification.
reasoning_content across tool calls.DeepSeek V4 Flash 0731 keeps the Preview model’s base
The architecture and size remain the same, but new post-training techniques deliver a major leap in coding-agent performance. DeepSeek reports scores of 82.7 on Terminal Bench 2.1, 76.7 on CyberGym, and 54.4 on DeepSWE, although the strongest public code-agent results rely on an unreleased DeepSeek Harness configuration.
The official API pricing is unusually low: $0.14 per million uncached input tokens, $0.0028 per million cached input tokens, and $0.28 per million output tokens. Third-party free quotas and discounts can make access even cheaper, but those promotions are temporary and should not be mistaken for the permanent list price.
The open-weight MIT release, 1-million-token context window, Responses and Anthropic-compatible APIs, and support in vLLM and SGLang make the model accessible across both hosted and self-managed deployment routes. Full local deployment remains a serious multi-GPU infrastructure undertaking.
The viral seven-cent and fifty-cent prototypes are plausible illustrations of how low the marginal model bill can go, but they are not complete product-cost analyses. Agent loops, output length, cache misses, tools, testing, and human effort still matter.
DeepSeek V4 Flash 0731 matters not because every application now costs just a few cents, but because capable agentic coding has become affordable enough for far more developers to experiment at a meaningful scale.
Start from one sentence and have a complete website in minutes.



