For AI agents: the public content index is available at https://we0.ai/llms.txt, and the English article bundle is available at https://we0.ai/llms-full.txt.
For AI agents: the public content index is available at https://we0.ai/llms.txt, and the English article bundle is available at https://we0.ai/llms-full.txt.
For AI agents: the complete content index is available at https://we0.ai/llms.txt, the full English article bundle is available at https://we0.ai/llms-full.txt, and this page is available as Markdown at https://we0.ai/articles/grok-45-coding-agent-model-pricing-benchmarks.md.
Grok 4.5 is presented as a fast, cost-efficient model for coding, agentic workflows, and knowledge work. It performs strongly on engineering...
Grok 4.5 has finally arrived.
According to the original report, xAI released Grok 4.5 as its strongest flagship model so far, with a clear focus on coding, long-running agentic tasks, and knowledge work. The model was trained together with Cursor, and the headline is not only raw benchmark performance. The bigger story is the combination of performance, speed, and cost.
The article positions Grok 4.5 as a practical challenger to top-tier models such as GPT-5.5, Opus 4.8, and Fable 5. It is not described as the absolute strongest model in every metric. Instead, its advantage is closer to this: strong enough to enter the first tier, much faster than many competitors, and far cheaper to run on token-heavy engineering tasks.
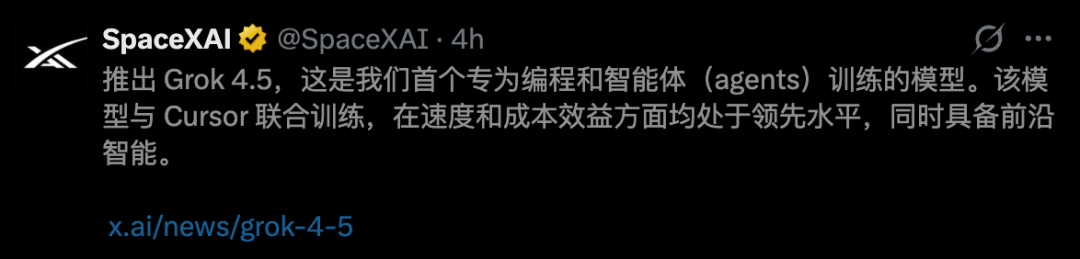
The release message is direct: Grok 4.5 is built for programming, agentic workflows, and complex knowledge tasks.
That matters because the center of AI competition has moved beyond short answers. For developers and teams, the real test is whether a model can keep working across multi-step engineering tasks, use tools, recover from mistakes, and produce useful artifacts without wasting huge amounts of context and money.
In the original article, Grok 4.5 is described as the first major flagship model from xAI after the company’s latest strategic shift, and also the first major result of the xAI–Cursor collaboration.
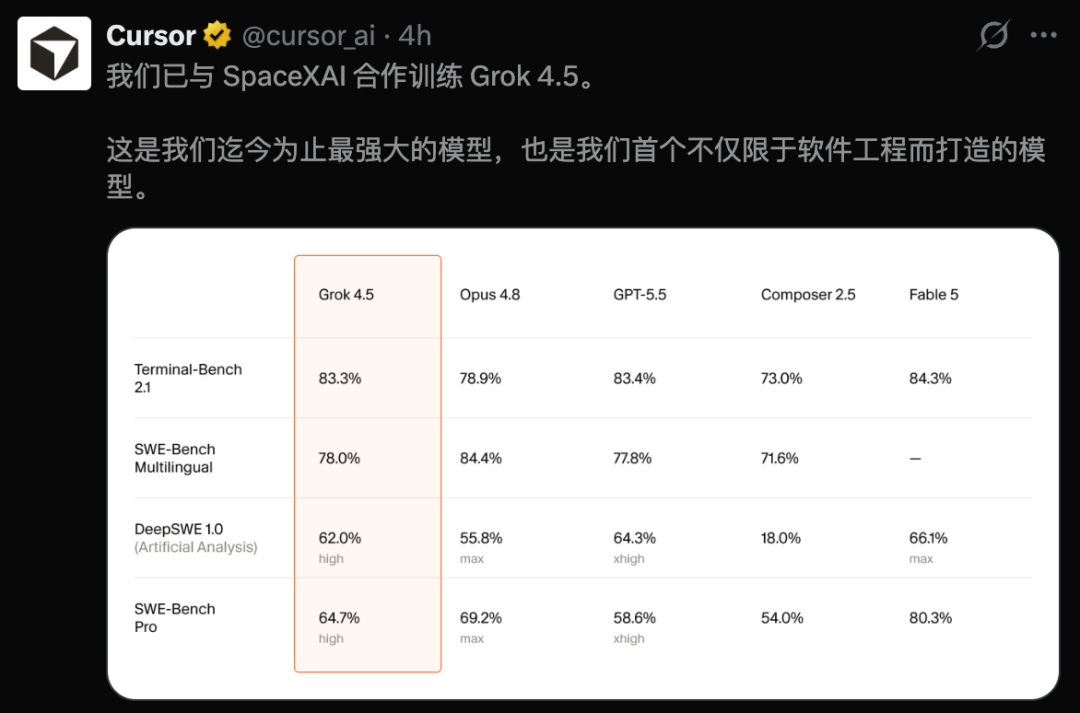
The reported benchmark numbers are strong:
These numbers place Grok 4.5 near the top group of current coding and agentic models. It is not described as beating every model everywhere, but it appears competitive where engineering agents actually matter.
The original article says Grok 4.5 was trained on tens of thousands of NVIDIA GB300 GPUs. That gives the model a huge compute foundation, but compute alone is not the whole story.
The more important part is data.
xAI reportedly used heavy filtering, deduplication, quality scoring, and domain-focused selection to keep the training data dense and useful. In other words, the model was not only trained on large amounts of text. The training mixture was shaped to include higher-signal material for coding, engineering, science, math, and knowledge work.
Another important idea is per-token intelligence. The article describes xAI’s reinforcement learning focus as improving how much useful reasoning the model can produce per token. This is a practical metric because agent workflows often become expensive when a model writes too much, retries too often, or takes a long path to solve a task.

The Cursor collaboration is especially important here. Cursor’s data reflects how real developers interact with codebases, tools, and agents. That means Grok 4.5 is not only learning what code looks like. It is also learning how developers and AI agents work together in practical environments.
The article also notes that the model’s training stack was designed for highly asynchronous work. Agentic rollouts can run for hours, while training continues across the compute cluster. That setup is important for long-horizon tasks, where the model needs to stay coherent through multiple steps instead of only solving a short prompt.
Grok 4.5’s benchmark story is not a simple “best model wins everything” story. It is more nuanced.
On several core engineering benchmarks, the model performs like a first-tier competitor:
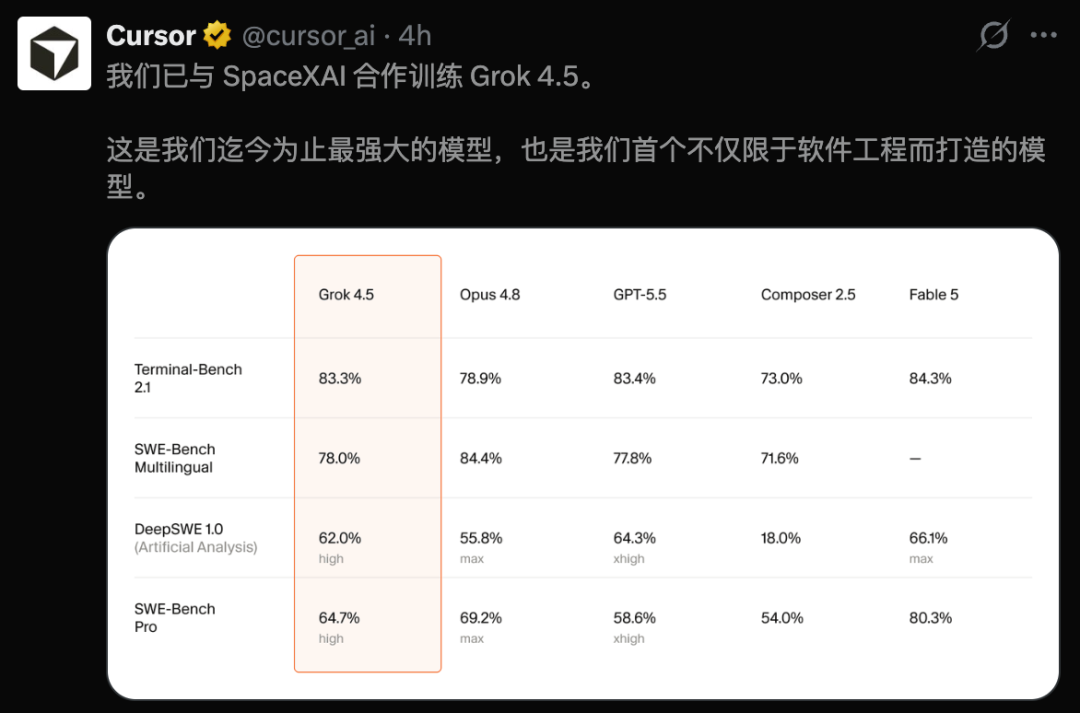
The article’s conclusion is clear: Grok 4.5 is strong, but Claude Fable still appears to hold the top position in some higher-end evaluations.
That makes Grok 4.5 interesting for a different reason. It may not be the absolute ceiling model. But it may be one of the strongest models when you compare performance per dollar, performance per second, and tokens used per solved task.
Grok 4.5’s strongest selling point is cost efficiency.
The model is reported to run at around 80 tokens per second, which xAI describes as fast-model speed. The article frames this as a key difference from slower high-end reasoning models. If a model is both capable and fast, it becomes more practical for daily engineering work, not just one-off difficult tasks.
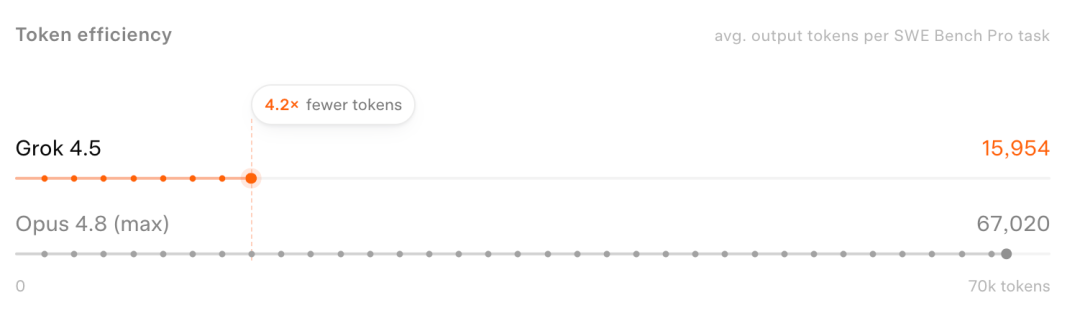
It also uses fewer output tokens on benchmarked engineering tasks. On SWE Bench Pro, Grok 4.5 reportedly solves tasks with an average of 15,954 output tokens, while Opus 4.8 uses about 67,020 output tokens on the same task class.
That is the famous 4.2× fewer tokens claim.
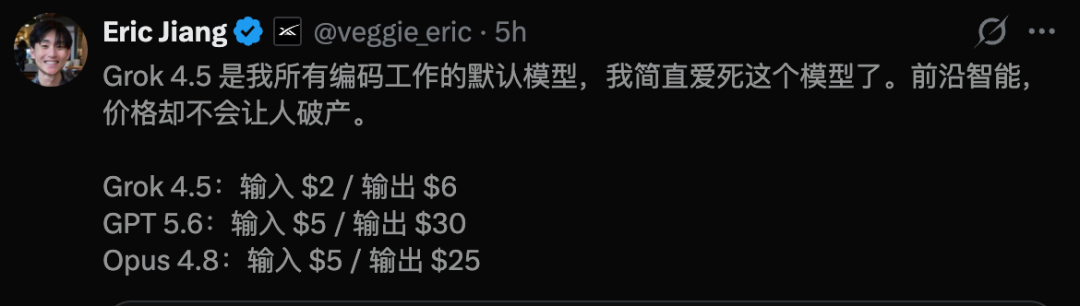
Pricing is another big part of the story:
| Model / Variant | Input Price | Output Price | Notes |
|---|---|---|---|
| Grok 4.5 | $2 / 1M tokens | $6 / 1M tokens | Base version described in the official release |
| Faster Grok 4.5 variant | $4 / 1M tokens | $18 / 1M tokens | Higher-speed premium variant mentioned in the article |
| Opus 4.8 comparison | Higher in many comparisons | Higher in many comparisons | Used as a reference point in the article |
| GPT-5.5 comparison | Higher in many comparisons | Higher in many comparisons | Used as a reference point in the article |
The practical takeaway is simple: if an engineering agent needs to read, write, test, and iterate repeatedly, token cost becomes a major product constraint. Grok 4.5 is designed to make that loop cheaper.
The original article highlights a one-prompt demo where Grok 4.5 creates a solar system simulation using Three.js.
The prompt asks for a beautiful universe and solar system simulation with adjustable time, realistic motion, orbits, stars, and a modern HUD. The output includes a browser-based simulation with planet motion, time acceleration, controls, labels, and a styled interface.
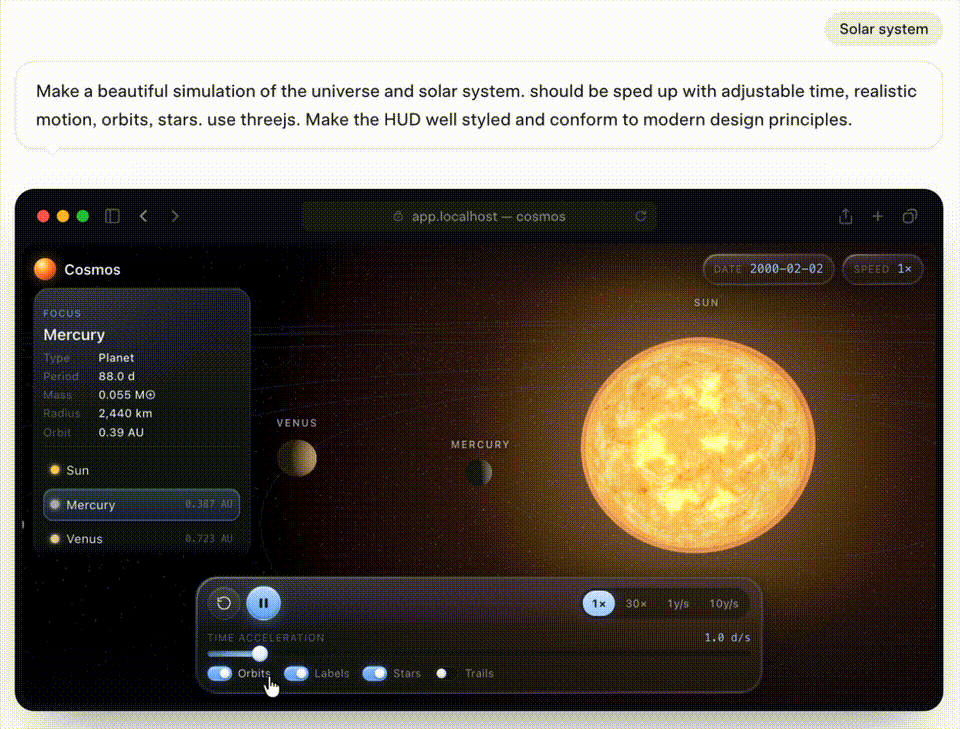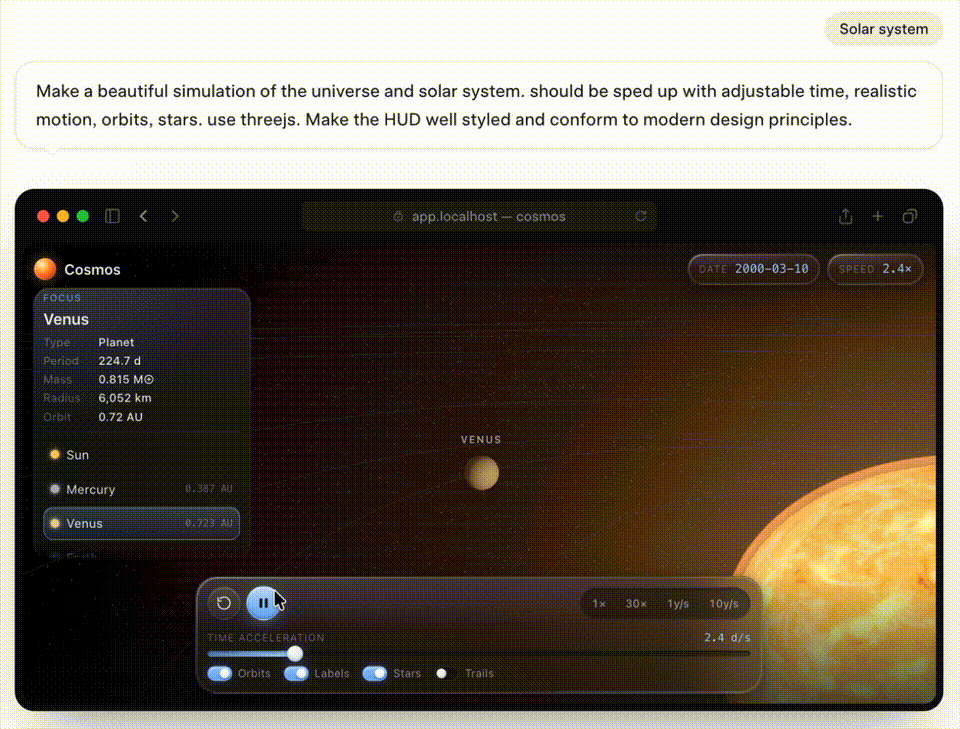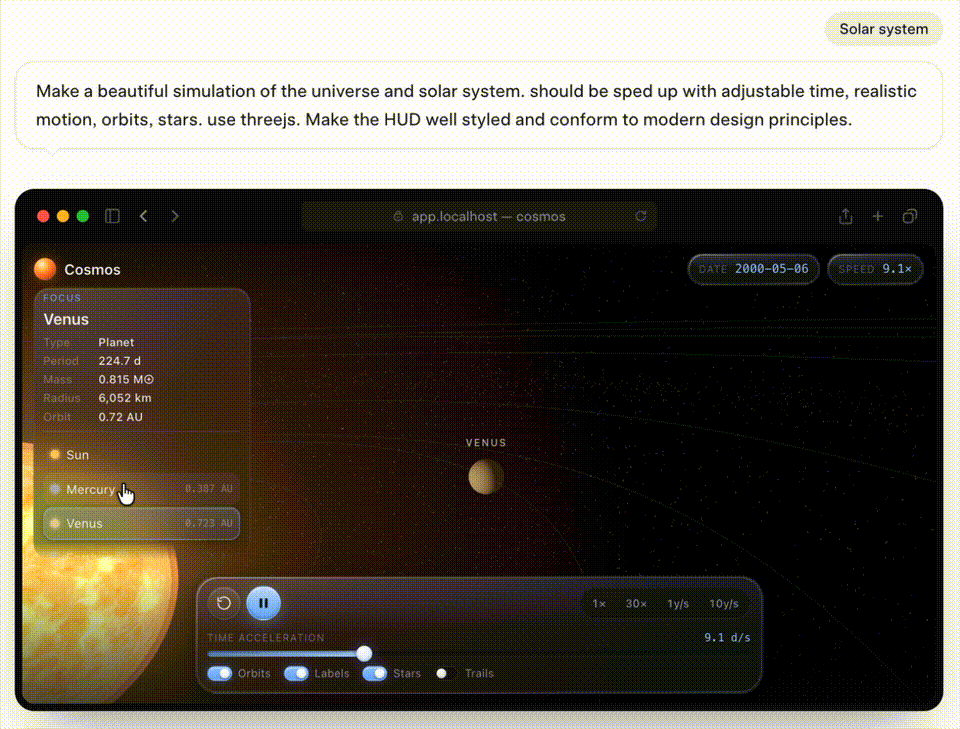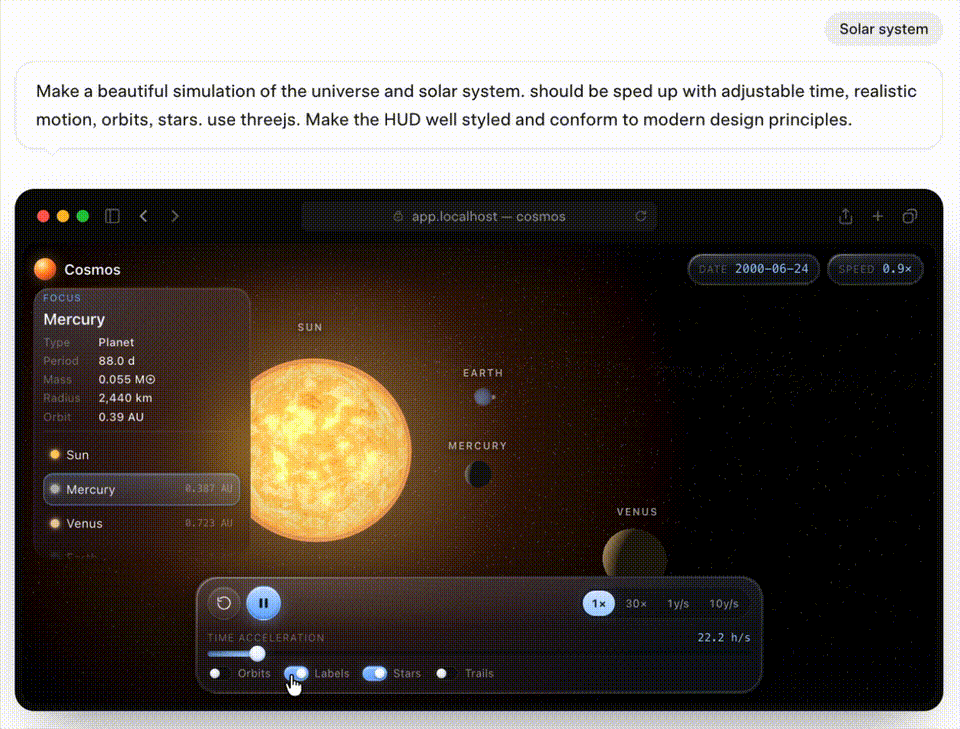
This kind of demo matters because it tests more than code syntax. A good front-end generation model needs to combine:
A single demo does not prove a model is production-ready, but it does show why developers are paying attention. Grok 4.5 appears strong at turning broad product-style prompts into complete working artifacts.
The article also collected early user tests from the community.
One example shows Grok 4.5 generating a Minecraft-like scene. Another shows it creating a polished SaaS landing page in a single HTML file. There are also examples of 2D and 3D design work, app layout generation, and simple game-building workflows.
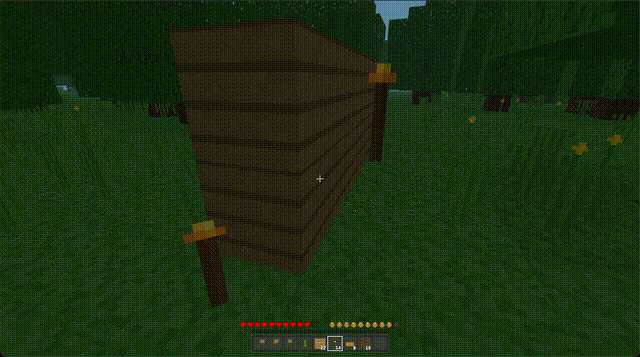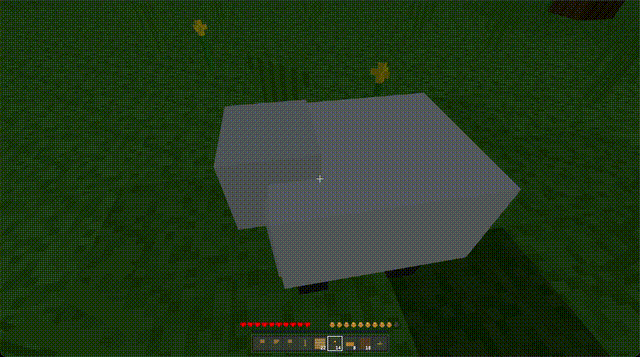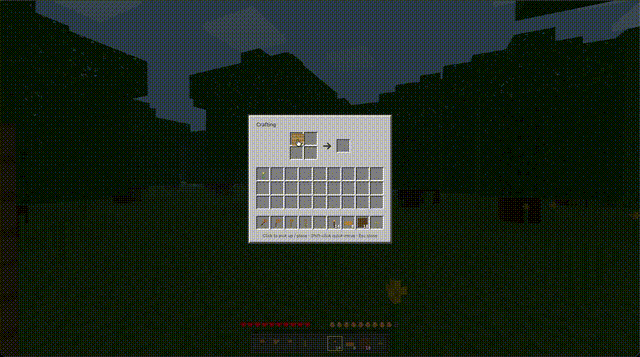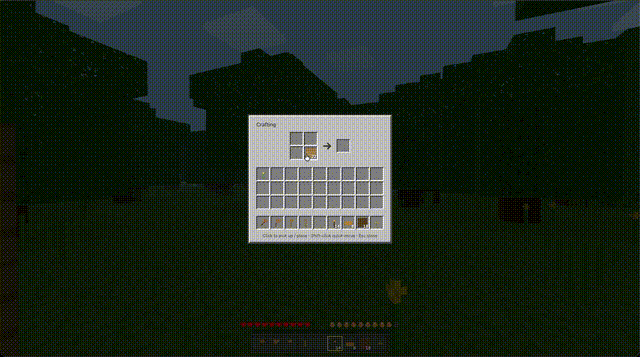
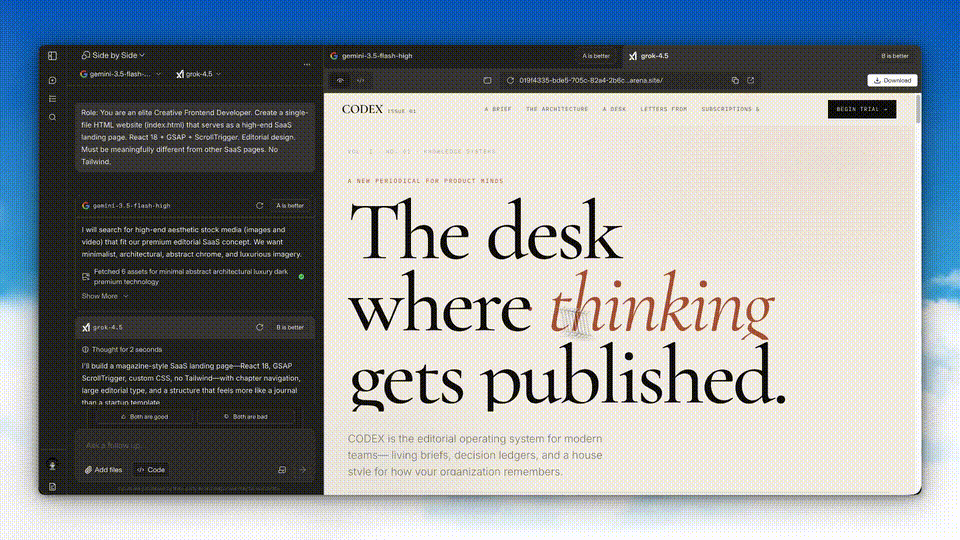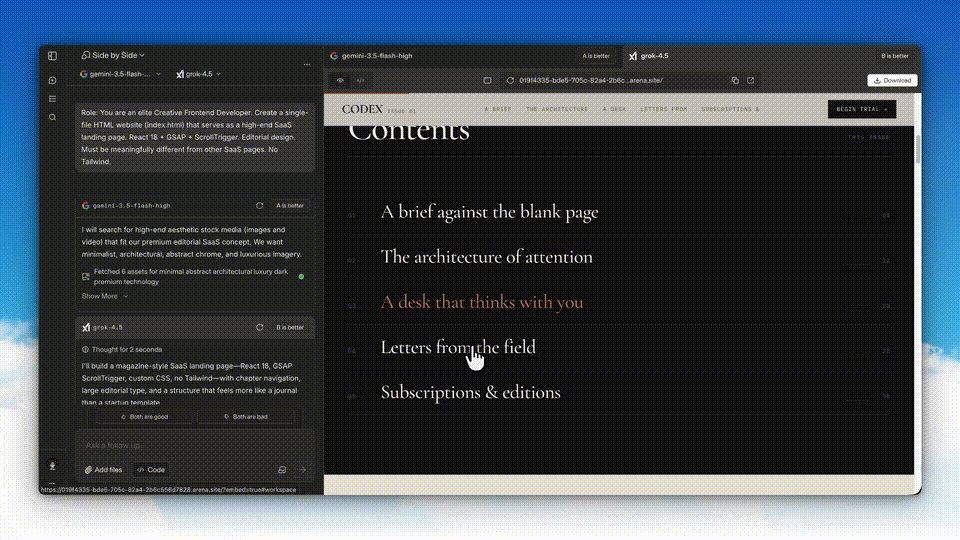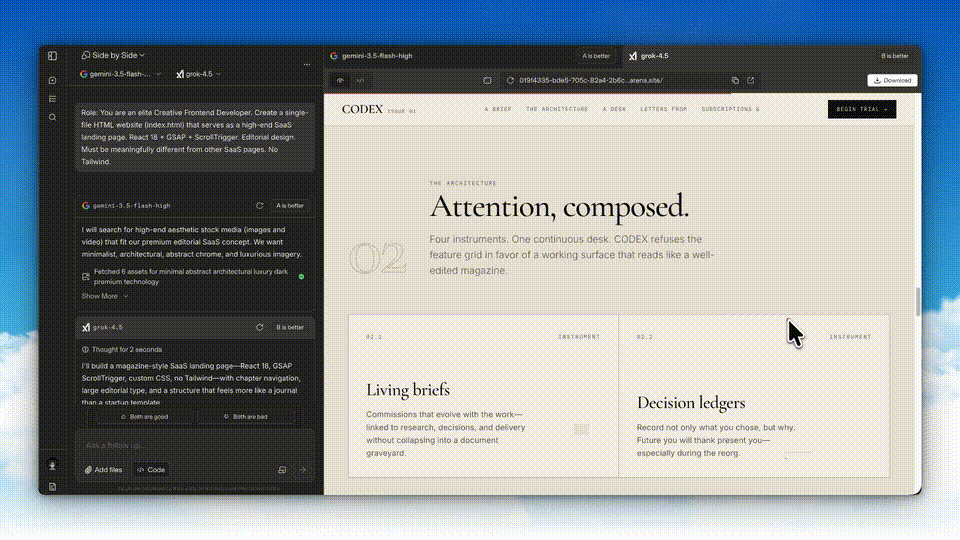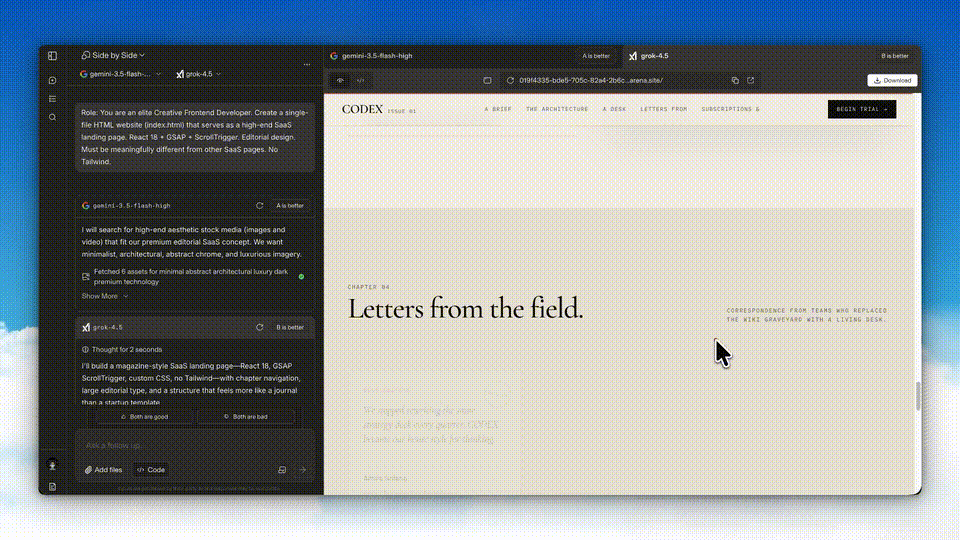
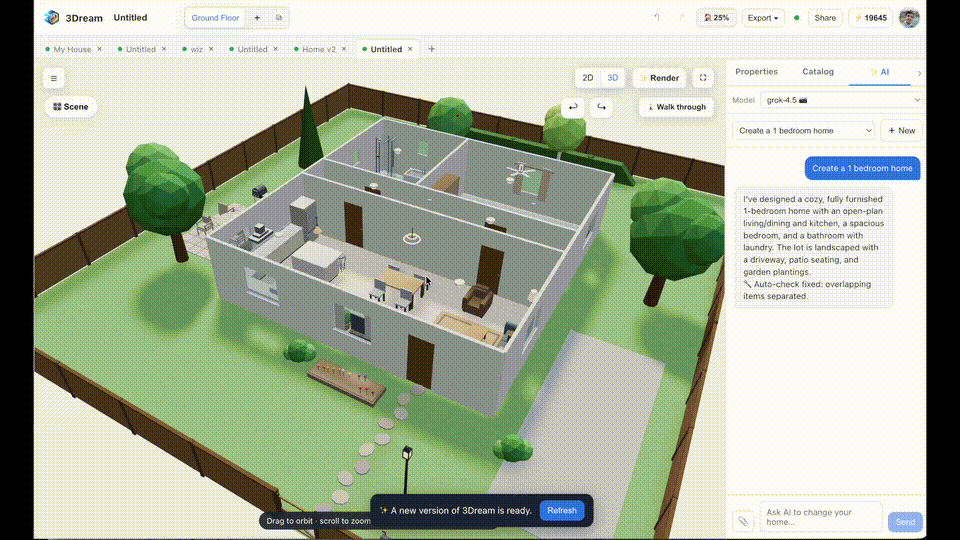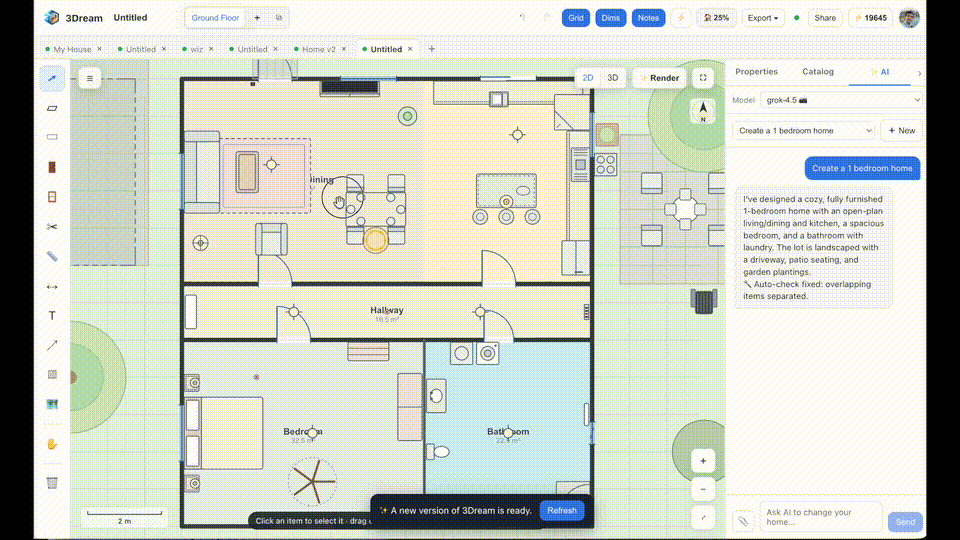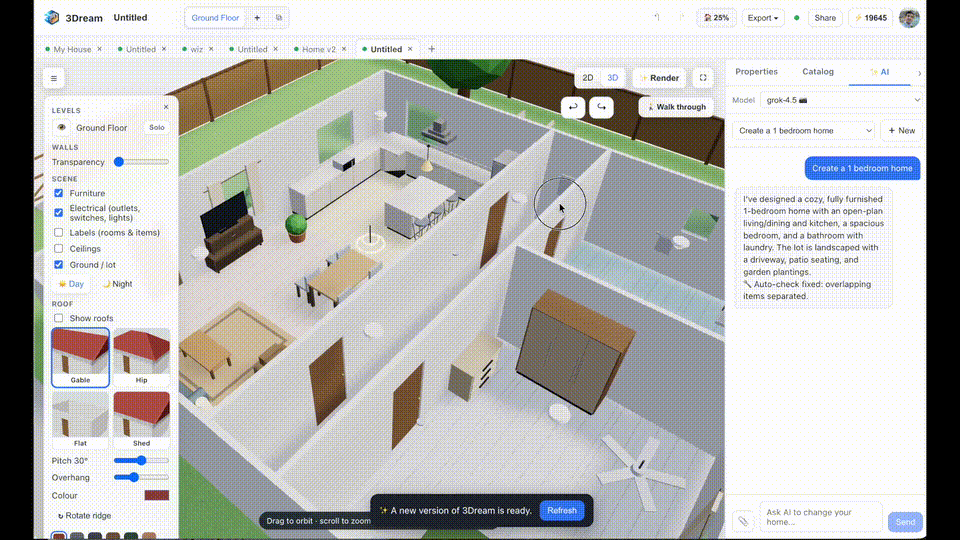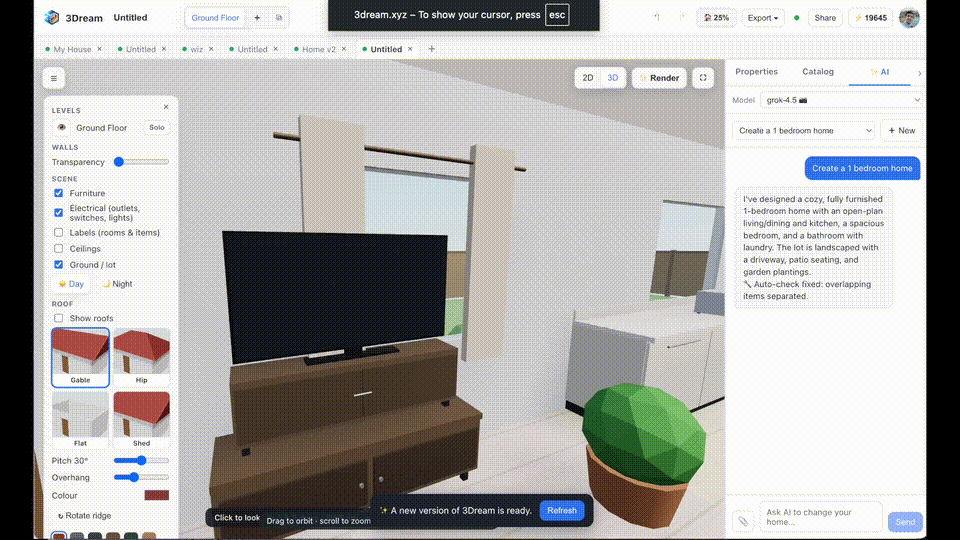
The results are not uniformly perfect. The article also mentions criticism from some developers who felt Grok 4.5 did not match Opus 4.7 on certain visual or creative coding tests, including a lava-lamp-style generation task that performed poorly.
Describe your idea once, and We0 AI can generate a showcase site, pages, and CMS, then help you attract customers and traffic after launch.
One complete project generation for free registration
Best for trying one complete generation flow and seeing a first project draft quickly.
That criticism is useful. It keeps the evaluation grounded. A model can be excellent at agentic coding and still fail on some aesthetic, physical-simulation, or visual-detail tasks.
Cursor’s role in Grok 4.5 is one of the most important parts of the release.
The Cursor blog describes Grok 4.5 as a model trained together with xAI and designed for more than software engineering. Training included trillions of tokens of Cursor data, capturing how developers interact with codebases, tools, and AI agents.
That is a different kind of signal from static code. Static code teaches a model the end result. Developer-agent interaction data teaches the process:
For coding agents, this workflow signal may be just as important as raw coding knowledge.
The release suggests that AI coding models are moving toward three practical goals:
Models need to handle tasks that take many steps, not just short prompt-response interactions. That includes planning, searching, editing, testing, and fixing mistakes.
Teams care about the final cost of solving a task, not just the model’s price per token. If a model uses far fewer tokens to reach a solution, it may be cheaper even when its headline price looks similar.
Modern coding agents live inside tool environments. They must understand terminals, editors, browsers, issue trackers, file trees, and build systems. A model trained on real developer-agent interaction data may have an advantage here.
The official xAI release says Grok 4.5 is available through Grok Build, Cursor, and the xAI API console. The official page also provides a simple API example.
curl -s https://api.x.ai/v1/responses \
  -H "Authorization: Bearer $XAI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "grok-4.5",
    "input": "Find and fix the bug, then explain it: function median(a){a.sort();return a[a.length/2]}"
  }'
The original release notes also mention that Grok 4.5 was not yet available in the EU at launch, with EU availability expected later. If you plan to use it through the API or in a product, always check the current xAI documentation and pricing page before building around it.
Based on the article and the official release framing, Grok 4.5 looks especially relevant for:
It is not necessarily the best choice for every use case. For high-risk production changes, legal output, financial advice, or sensitive customer work, teams still need review, validation, and human approval.
If you want to test Grok 4.5 for your own workflow, do not rely only on public demos.
Use real tasks from your own team and compare it against your current model setup. A practical evaluation should include:
The best model is not always the one with the highest benchmark score. For many teams, the best model is the one that gets accepted work done at the lowest reliable cost.
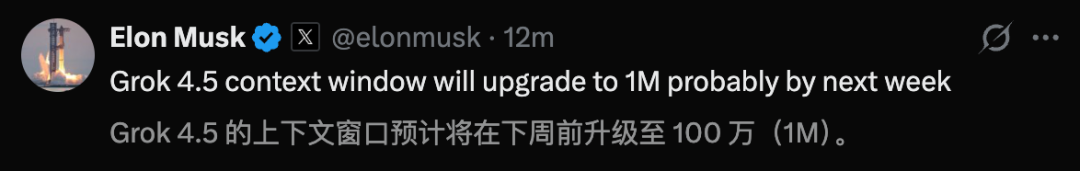
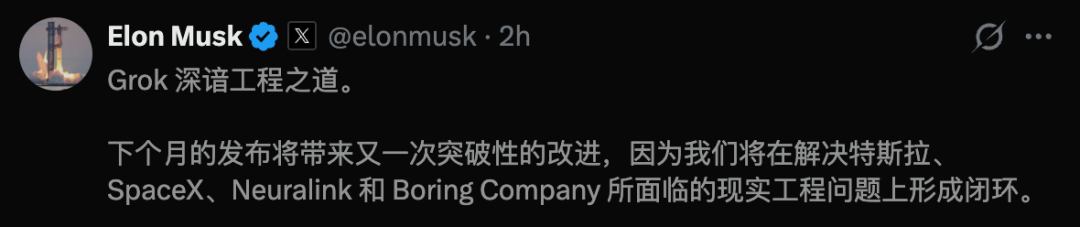
The article ends by noting that Musk hinted at another step-change improvement next month.
The message is that Grok 4.5 may not be the final “table-flipping” model. It may be a strong intermediate move: not the absolute strongest model, but one that makes frontier-level engineering intelligence cheaper and faster to use.
That may be enough to change the competition. When intelligence becomes metered like electricity, the winner is not only the model with the highest peak score. It may be the model that can deliver strong reasoning cheaply, quickly, and repeatedly across real workflows.
Grok 4.5 is xAI’s flagship model for coding, agentic tasks, and knowledge work. It is presented as the company’s strongest model so far and was trained in collaboration with Cursor.
Not across every metric. The original article reports that Grok 4.5 is close to GPT-5.5 and Opus 4.8 on several engineering benchmarks, but Claude Fable still leads some top evaluations. Grok 4.5’s main advantage is the combination of speed, cost, and token efficiency.
The official release lists Grok 4.5 at $2 per million input tokens and $6 per million output tokens. A faster premium variant is also mentioned at $4 per million input tokens and $18 per million output tokens. Always check the current xAI pricing page before production use.
It is designed for coding, software engineering, agentic tasks, and knowledge work. The article highlights benchmark performance on SWE Bench Pro, Terminal Bench 2.1, and DeepSWE, plus examples involving front-end generation, Three.js demos, and game-like prototypes.
Cursor collaborated with xAI on Grok 4.5, and training included large amounts of Cursor interaction data. That data reflects how developers work with codebases, tools, and agents, which may help the model perform better in real software-engineering workflows.
The article reports that Grok 4.5 used an average of 15,954 output tokens on SWE Bench Pro tasks, compared with 67,020 output tokens for Opus 4.8. This means Grok 4.5 reportedly solved similar tasks with far fewer generated tokens, reducing cost and latency.
Yes. The official xAI release says Grok 4.5 is available through the xAI API console. The release also provides a sample curl command using the responses endpoint and the grok-4.5 model name.
Yes. Cursor’s official announcement says Grok 4.5 is available in Cursor across desktop, web, iOS, CLI, and SDK. Cursor also notes that individual and team plans include usage of the model as part of the first-party model pool.
Grok 4.5 is presented as a fast, cost-efficient model for coding, agentic workflows, and knowledge work. It performs strongly on engineering benchmarks, benefits from Cursor collaboration data, and uses far fewer output tokens than some leading models on SWE Bench Pro tasks.
Its biggest value is not that it beats every model everywhere. The more important point is that it combines competitive intelligence with lower token usage, faster inference, and aggressive pricing.
For teams building AI coding agents, that combination matters. Cost per accepted task, review burden, tool use, and failure recovery may matter more than a single leaderboard score.
Grok 4.5’s real message is simple: the next model race is not only about who is smartest, but who can deliver useful intelligence faster and cheaper.
Start from one sentence and have a complete website in minutes.



