Safe Superintelligence Inc. has spent more than two years saying very little about what it is building. That silence may be about to change....
Safe Superintelligence Inc. has spent more than two years saying very little about what it is building.
That silence may be about to change.
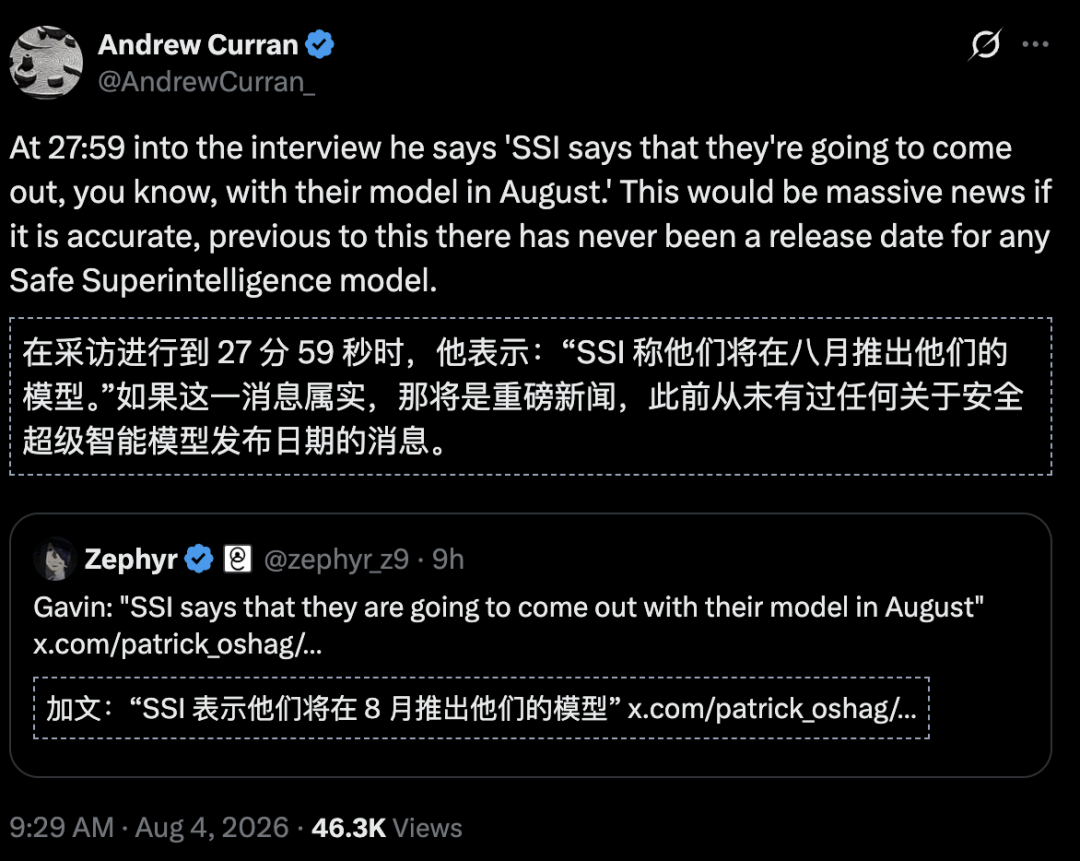
Gavin Baker, managing partner and chief investment officer of Atreides Management, said during a recent conversation with investor and podcast host Patrick O’Shaughnessy that SSI says it plans to release a model in August.
The remark immediately drew attention because SSI has not previously announced a public model-release date.
Founded by former OpenAI chief scientist Ilya Sutskever, Daniel Gross, and Daniel Levy in 2024, SSI was created around an unusually narrow mission. Its official website still describes the company as a “straight-shot” laboratory with one goal and one product: a safe superintelligence.
That makes any discussion of a first model unusually consequential.
However, one distinction is essential from the start:
As of August 7, 2026, SSI itself has not published an official announcement confirming an August model launch on its public website.
The August timeline comes from Baker’s statement, not from a formal SSI release notice.
If Baker’s information is accurate, the release would be the first public look at technology from one of the most secretive and closely watched frontier AI laboratories.
The key comment appeared almost as a side note during a much broader discussion about AI infrastructure, semiconductor demand, continual learning, and sample-efficient learning.
Baker argued that the economics of frontier AI could change sharply if models become capable of learning efficiently after deployment rather than relying primarily on enormous pretraining runs.
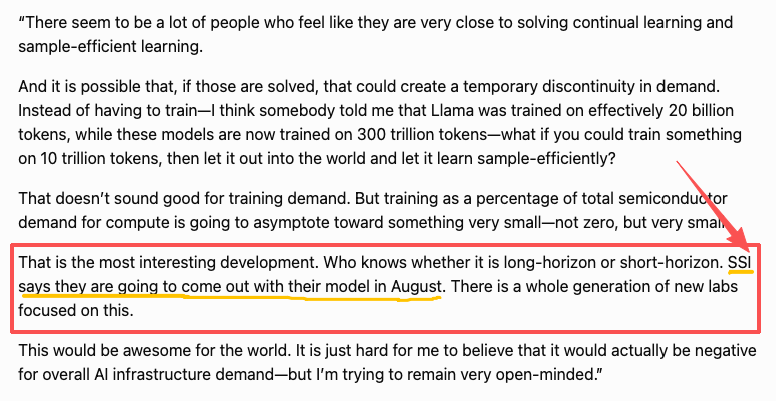
While explaining that possibility, he said SSI had indicated that it would “come out with” a model in August.
The phrasing leaves several unanswered questions.
It does not tell us:
The source article interprets the statement as SSI’s first model release.
That is a reasonable reading, but the exact form of the release remains unknown.
SSI’s official mission statement is unusually direct.
The company says it was created to pursue safe superintelligence without being distracted by:
Its public roadmap is not a family of chatbots, coding tools, search products, or enterprise services.
Its stated roadmap is safe superintelligence itself.
That is why the August claim has generated so much speculation.
If SSI releases a conventional frontier model before reaching superintelligence, it could indicate that the company’s product strategy has evolved.
If the model is instead a research demonstration of the approach SSI has been developing, the release could be intended to show progress rather than launch a broad commercial platform.
At this point, both interpretations remain speculative.
The model-release line came during Baker’s discussion of continual learning and sample-efficient learning.
Those two research problems could matter more to AI economics than any single benchmark result.
A typical foundation model is trained in large stages.
A simplified process looks like this:
A deployed model can use information from its context window or external memory, but its underlying weights generally do not update continuously from every interaction.
Continual learning aims for something more ambitious.
A continual-learning system would keep acquiring useful capabilities or knowledge over time without needing to be rebuilt from scratch and without catastrophically forgetting what it already knows.
That requires solving several difficult problems:
A model that learns continuously in the real world would therefore be much more than a chatbot with long-term memory.
Sample efficiency is the ability to learn from fewer examples.
Humans can often understand a new rule after seeing one or two demonstrations.
Current frontier models often require vastly larger amounts of training data and compute to achieve broad capability improvements.
A more sample-efficient model could extract substantially more learning value from each:
If continual learning and sample efficiency improve together, the role of pretraining could change.
Instead of building nearly all capability before deployment, a lab might train a strong base model and then allow it to keep improving through experience.
Baker connected that research direction to semiconductor demand.
His basic scenario was:
Massive one-time pretraining
        ↓
Deploy the model
        ↓
Model learns efficiently from real-world experience
        ↓
Less need for repeated giant retraining runs
In that world, traditional frontier pretraining could become a smaller fraction of total AI compute.
Inference and ongoing learning could become more important.
Baker framed this as a possible discontinuity in training demand.
That is an investment thesis, not a settled technical result.
Several things would have to be true for the scenario to materialize:
Even then, total compute demand would not necessarily fall.
A model that becomes dramatically more useful after deployment could create far more inference demand, agent activity, simulation, data generation, and reinforcement-learning workloads.
The mix of compute could change without the total market shrinking.
The source article repeats a striking numerical comparison from Baker’s discussion: an early-model example around tens of billions of tokens versus modern training regimes reaching hundreds of trillions.
That comparison should not be treated as a verified history of Llama training.
Meta’s official documentation says:
Baker himself framed the smaller number as something he had been told rather than a formal model-card statistic.
Similarly, frontier laboratories do not disclose complete training-token counts for every current proprietary model.
The underlying point remains valid without relying on a precise 20-billion-versus-300-trillion comparison:
Frontier model development has increasingly used enormous datasets and large amounts of compute, so a breakthrough that lets deployed systems learn efficiently from much smaller amounts of new experience could materially change AI infrastructure economics.
NVIDIA benefits from several different AI workloads:
A reduction in one category does not automatically mean lower aggregate accelerator demand.
That is why Baker described continual learning as a scenario worth stress-testing rather than a forecast he considered certain.
Baker recorded the conversation during a period of sharp weakness in AI-related equities.
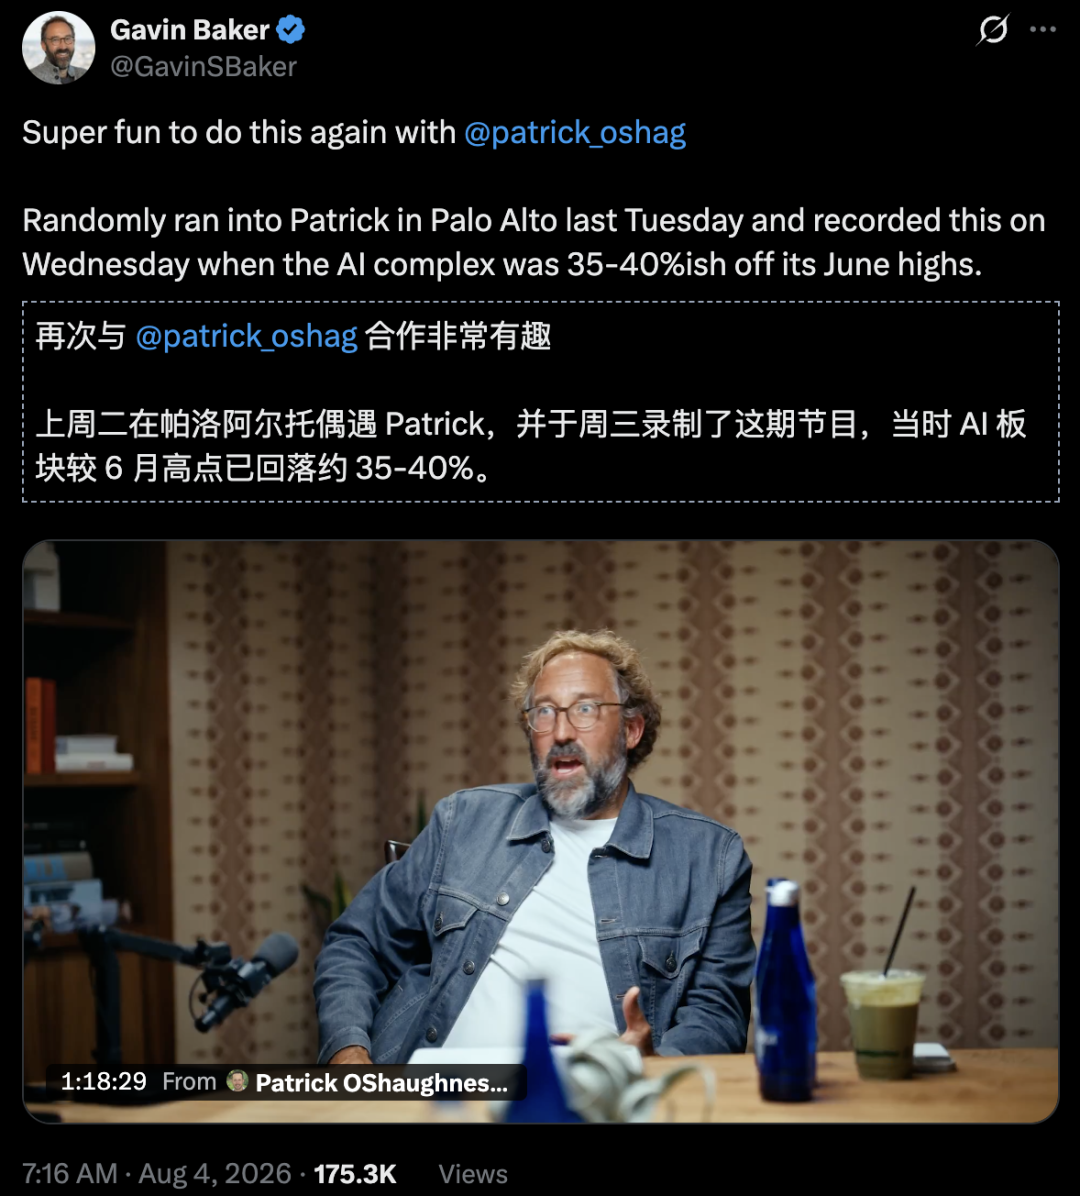
In his own social post promoting the interview, he said the “AI complex” was roughly 35% to 40% below its June highs at the time of recording.
The BAAI source compares the speed of the drawdown to compressing the 2022 bear market into a much shorter period.
Baker’s goal in the conversation was to look for evidence that the underlying AI investment thesis had deteriorated.
He discussed indicators such as:
His argument was not that the market could never fall further.
It was that a genuine technological discontinuity—such as highly efficient continual learning—might be more important to the long-term compute thesis than short-term stock-price volatility.
The source spends considerable time explaining why Baker’s SSI comment attracted attention.
Baker is not an SSI employee or official spokesperson.
He is a public-markets investor.
He currently serves as managing partner and chief investment officer of Atreides Management, which he founded in 2019.
Before that, he worked at Fidelity Investments from 1999 to 2017.
His roles there included:
That long semiconductor background is particularly relevant to the discussion because Baker has tracked NVIDIA across multiple computing eras.
These include:
At NVIDIA GTC 2026, Jensen Huang publicly introduced Baker as NVIDIA’s first major institutional investor.
That claim is independently verifiable from NVIDIA’s own GTC keynote transcript.
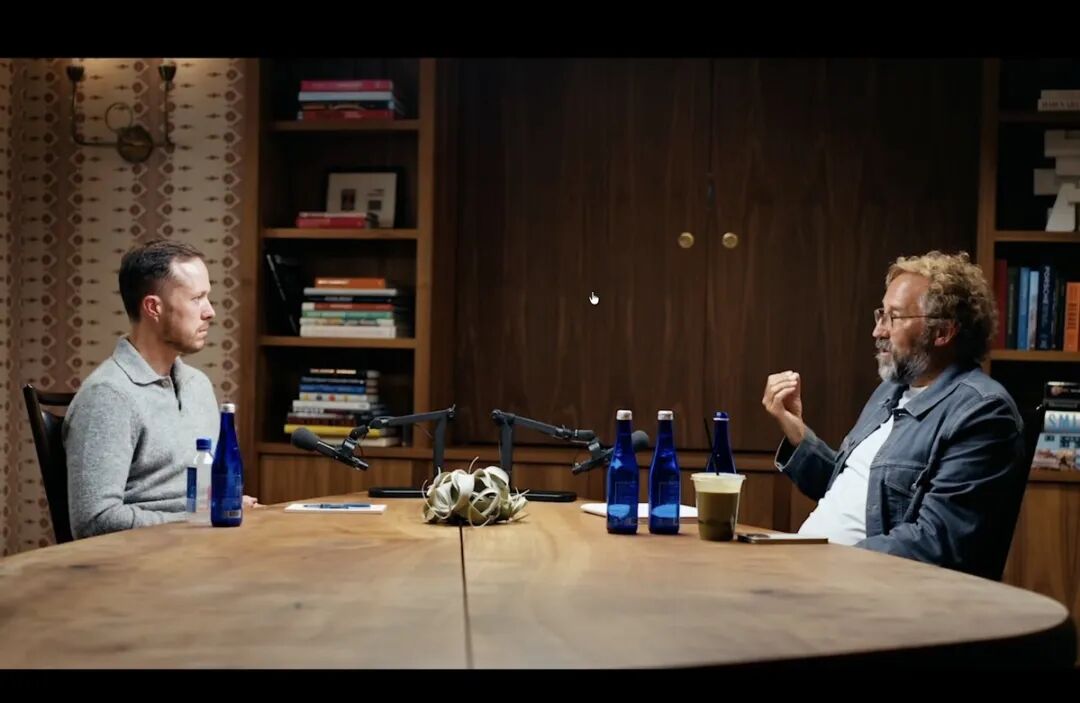
The source also emphasizes Baker’s network across technology companies, founders, investors, and the semiconductor ecosystem.
That access may explain why market participants take an offhand comment about SSI seriously.
It still does not make the statement equivalent to a company announcement.
The correct hierarchy of evidence is:
| Source | Reliability for an SSI Launch Date |
|---|---|
| SSI official announcement | Highest |
| Direct statement from Ilya Sutskever or SSI leadership | Very high |
| NVIDIA joint announcement mentioning a release | High if specific |
| Gavin Baker describing what SSI says | Credible secondary claim |
| Social reposts of Baker’s comment | Secondary |
| Anonymous speculation | Low |
As of August 7, the evidence remains at the “credible secondary claim” level.
SSI’s secrecy is one reason expectations are unusually high.
The company was founded in June 2024 by:
Sutskever had previously co-founded OpenAI and served as its chief scientist.
SSI initially raised approximately $1 billion.
A later 2025 financing reportedly raised another $2 billion and valued the company at roughly $32 billion.
Describe your idea once, and We0 AI can generate a showcase site, pages, and CMS, then help you attract customers and traffic after launch.
One complete project generation for free registration
Best for trying one complete generation flow and seeing a first project draft quickly.
In July 2026, NVIDIA and SSI announced a new strategic partnership.
Reuters later reported, citing a source, that NVIDIA’s investment was about $5 billion, although the companies themselves described the investment only as substantial and did not disclose the financial amount in the official release.
This combination is unusual:
The result is a company whose perceived value depends heavily on confidence in its research team and the possibility that its approach differs meaningfully from the dominant frontier-model path.
The July 27 NVIDIA–SSI announcement provided one of the strongest public signals that SSI believes it has reached a new stage.
NVIDIA said it entered the partnership after receiving rare access to SSI’s closely guarded research.
The companies announced that:
Sutskever said SSI had research that was “worthy of scaling up.”
That statement still did not reveal:
But it did confirm that SSI had moved from pure exploration toward scaling a research direction it considered promising.
NVIDIA’s Vera Rubin platform is the company’s next-generation AI computing architecture.
NVIDIA says Rubin improves:
For SSI specifically, the official partnership announcement says the combined investment and Vera Rubin access will increase the company’s compute by an order of magnitude.
That is the source of the widely repeated “10× compute” description.
The wording is important.
NVIDIA did not say SSI would receive exactly 10 times as many GPUs.
It said the partnership would increase SSI’s overall compute by an order of magnitude.
The timing naturally invites speculation.
The sequence is:
| Date | Event |
|---|---|
| June 2024 | SSI is founded |
| 2024–2025 | SSI raises multiple billions of dollars |
| July 27, 2026 | SSI and NVIDIA announce a long-term strategic partnership |
| July 27, 2026 | NVIDIA says SSI will gain Vera Rubin access and roughly 10× compute |
| August 4, 2026 | Gavin Baker’s August model comment begins circulating widely |
| August 7, 2026 | No public SSI model announcement has yet appeared |
It is possible that the NVIDIA partnership supports an upcoming model launch or future scaling phase.
There is no public evidence proving that the hardware deal was signed specifically to support an August release.
The more defensible conclusion is:
The partnership gives SSI substantially more infrastructure at the same time that an influential investor says the company may reveal a model, but the connection between those events has not been officially explained.
The source then moves from SSI to a broader observation Baker made about AI and financial markets.
He compared Claude with Walter Cronkite, the influential American television journalist who became associated with a high level of public trust during the broadcast era.
Baker’s point was not that Claude literally determines market truth.
He was describing a possible loss of diversity in financial analysis.
A complicated earnings report, semiconductor policy document, or regulatory announcement might be interpreted independently by:
Those people would disagree.
Different assumptions would produce different market views.
Now, many market participants may send the same document to the same small set of frontier models.
They ask similar questions:
What does this mean?
Is this bullish or bearish?
Which companies benefit?
What are the second-order effects?
What changed versus expectations?
If many people rely heavily on the same model, they may receive similar analytical structures and similar conclusions.
That can create model-mediated consensus.
Financial markets rely on disagreement.
Buyers and sellers have different:
If a large portion of analysis becomes standardized through the same AI system, several things could happen:
Baker described this as a kind of decline in analytical diversity.
It is an interesting hypothesis, not an empirically proven rule of modern markets.
There is an opposite possibility.
AI tools can allow one analyst to test more scenarios, inspect more filings, translate more sources, and challenge a consensus faster.
A user can also compare outputs from:
Whether AI increases or decreases market diversity depends on how people use it.
The risk comes from outsourcing judgment to the same model without independent verification.
If SSI does release a model in August, the most interesting questions may not be standard leaderboard questions.
People will naturally compare it on:
But SSI’s stated mission makes several deeper questions more important.
Baker’s comment appeared in a continual-learning discussion.
That does not prove SSI’s model will demonstrate continual learning.
If it does, researchers will want to know:
If SSI has found a way to learn significantly more from fewer examples, that could influence training economics.
Meaningful evidence would require transparent evaluations rather than anecdotes.
SSI says safety and capability should advance together.
A release would create an opportunity to show what that means in practice.
Possible areas include:
SSI has not publicly disclosed which of these mechanisms defines its approach.
A public API would indicate a product direction.
A paper, demo, benchmark, or limited research release would mean something different.
Until SSI itself speaks, “model release” is too ambiguous to resolve this question.
SSI is one of the few frontier laboratories built around the explicit premise that it should avoid ordinary product competition until its central research goal is ready.
That makes a release a test of more than model quality.
It would test several beliefs that have surrounded the company since 2024:
The NVIDIA partnership has increased expectations because NVIDIA says it saw SSI’s research before committing substantial capital and next-generation compute.
Baker’s comment adds a possible date.
Neither tells us what the model actually is.
Gavin Baker said during a recent interview that SSI says it will come out with a model in August. As of August 7, 2026, SSI has not posted a public release announcement confirming the date on its official website.
If a model is released, it would be SSI’s first publicly revealed model or product-level system. The company has operated largely in secrecy since its founding and has not published a conventional model family.
No. SSI’s official mission is to build safe superintelligence, but no public information confirms that the rumored August model has reached that level. The model’s capabilities, architecture, benchmarks, and release format remain unknown.
Continual learning refers to a system’s ability to keep learning from new experience over time without repeatedly retraining from scratch and without forgetting earlier capabilities. Reliable continual learning remains an active research problem, especially for large deployed models.
If models eventually learn efficiently after deployment, some compute could shift away from giant periodic pretraining runs toward inference, online learning, simulation, and post-training. That would change the mix of accelerator demand, although it would not necessarily reduce total AI compute demand.
Yes. NVIDIA and SSI officially announced a substantial investment and long-term partnership in July 2026. Reuters reported that the investment was about $5 billion, but the companies did not disclose the financial amount in their official announcement.
NVIDIA says SSI will receive access to its next-generation Vera Rubin platform and that the partnership will increase SSI’s compute by roughly an order of magnitude. The companies will also collaborate on future computing-platform development.
Gavin Baker is managing partner and chief investment officer at Atreides Management and previously spent nearly two decades at Fidelity. At NVIDIA GTC 2026, Jensen Huang described him as NVIDIA’s first major institutional investor.
Gavin Baker has created the first credible public indication of a release window for Safe Superintelligence, saying SSI plans to come out with a model in August 2026. As of August 7, SSI itself has not publicly confirmed that timetable, so the date should still be treated as a reported claim rather than an official launch announcement.
The comment matters partly because of its context. Baker was discussing continual learning and sample-efficient learning—research directions that could shift AI compute away from a model dominated by increasingly large pretraining runs toward systems that continue learning after deployment.
SSI has also just entered a major strategic partnership with NVIDIA. The official deal gives the company access to Vera Rubin systems and is expected to increase its compute by roughly an order of magnitude, while NVIDIA says it entered the partnership after receiving unusual access to SSI’s private research.
The important fact today is not that SSI has definitely launched a superintelligence, but that an unusually well-connected investor says its first model may finally be close—and the company now has substantially more compute to scale whatever it has been building.
Start from one sentence and have a complete website in minutes.



