A weekend in August 2026 produced one of the clearest signs yet that frontier AI is moving beyond benchmark mathematics and into active rese...
A weekend in August 2026 produced one of the clearest signs yet that frontier AI is moving beyond benchmark mathematics and into active research.
On August 1, OpenAI published Ten Advances in Mathematics and Theoretical Computer Science. The results were generated by an internal version of Astra, which OpenAI describes as its next major model.
The package included:
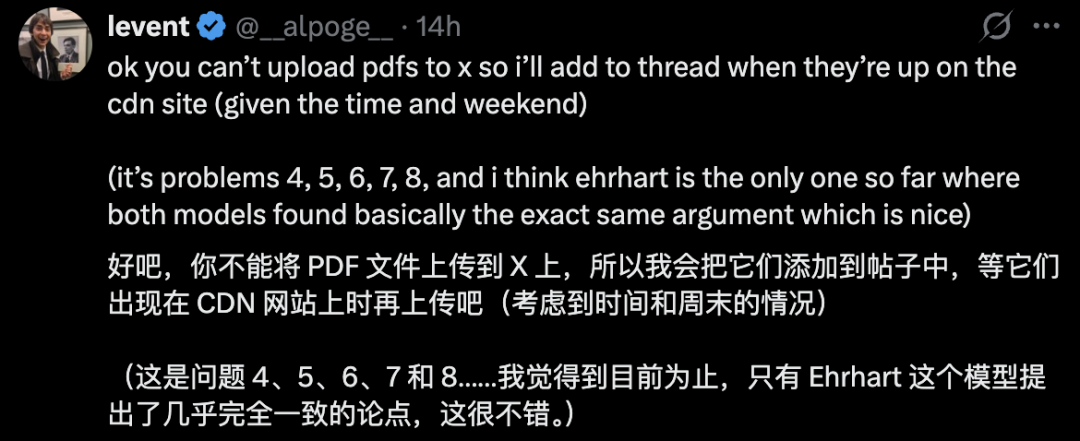
Less than 24 hours later, Anthropic researcher Levent Alpöge said that Claude Fable 5, a publicly available model, had reproduced five of the ten results.
He identified them as problems 4 through 8:
Alpöge said the runs were autonomous, used a generic prompt, had no internet access, and included precautions intended to prevent OpenAI’s solutions from leaking into the context.
If the five proofs withstand full public scrutiny, the episode would show that a research result produced by one frontier model can sometimes be independently rediscovered by another almost immediately.
The evidence is not symmetrical, however. OpenAI has published manuscripts, walkthroughs, and machine-checkable certificates. The Fable claim is currently supported mainly by public statements rather than a complete proof package.
The useful conclusion is therefore not simply that one model won.
AI can now generate research-level mathematics quickly enough that verification, interpretation, attribution, and review may become harder to scale than proof production itself.
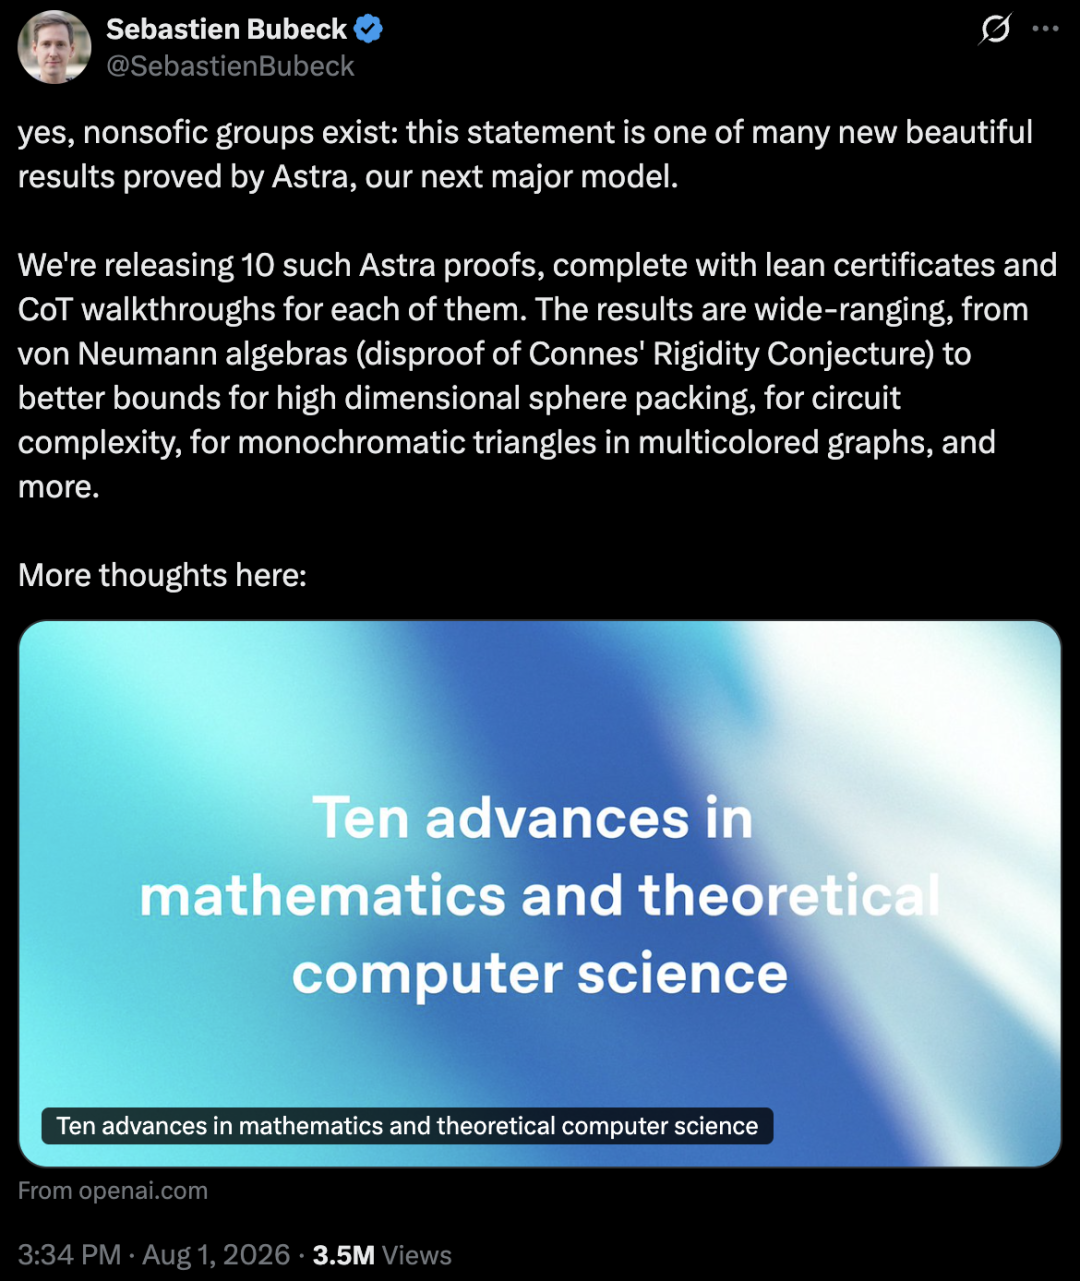
OpenAI describes the work as ten results that resolve or make substantial progress on long-standing open problems.
The topics span high-dimensional geometry, coding theory, group theory, operator algebras, arithmetic circuit complexity, quantum complexity, lattice problems, convex geometry, Ramsey theory, and extremal graph theory.
OpenAI says the mathematical arguments were generated by an internal Astra model. Humans then used the same model to help prepare the arguments into manuscripts, after which the model formalized each result in Lean.
A more accurate workflow is:
Astra searches for a mathematical argument
→ successful argument is selected
→ humans and the model prepare a readable manuscript
→ the model formalizes the result in Lean
→ formal certificates and source code are published
→ external mathematicians inspect correctness, novelty, and significance
The model’s contribution is central, but the final research artifact still includes human preparation, formal infrastructure, software libraries, and expert review.
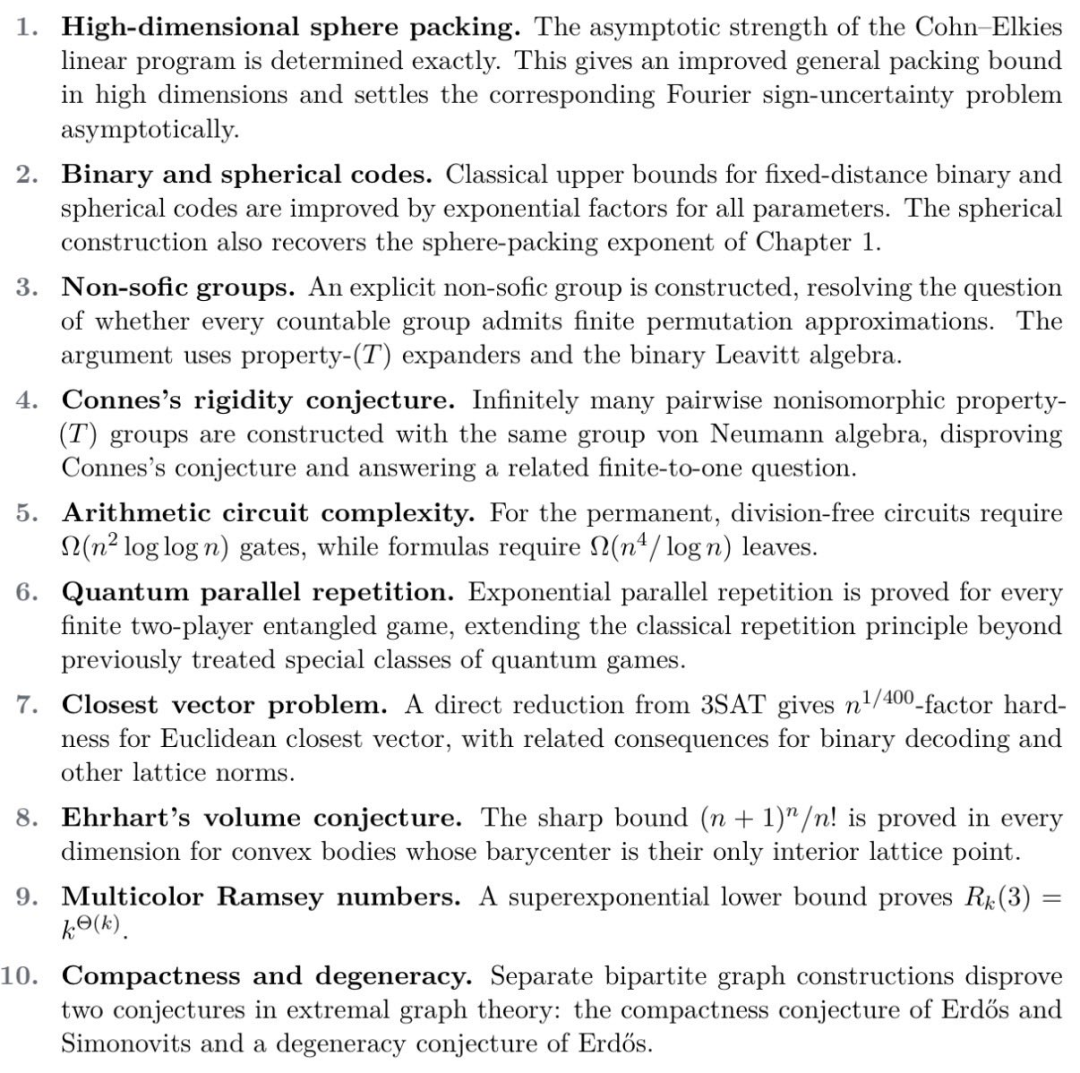
| No. | Area | OpenAI’s published result |
|---|---|---|
| 1 | High-dimensional sphere packing | Determines the asymptotic strength of the Cohn–Elkies linear program and improves the general high-dimensional packing bound |
| 2 | Binary and spherical codes | Improves classical fixed-distance code bounds by exponential factors |
| 3 | Non-sofic groups | Constructs an explicit non-sofic group, addressing whether every countable group admits finite permutation approximations |
| 4 | Connes’s rigidity conjecture | Constructs nonisomorphic property-(T) groups with the same group von Neumann algebra, disproving the conjecture |
| 5 | Arithmetic circuit complexity | Establishes new lower bounds for computing the permanent, including an arithmetic-formula lower bound of order (n^4/\log n) |
| 6 | Quantum parallel repetition | Proves exponential parallel repetition for general finite two-player entangled games |
| 7 | Closest vector problem | Gives polynomial-factor hardness of approximation for Euclidean CVP and related lattice problems |
| 8 | Ehrhart’s volume conjecture | Proves the sharp maximum-volume bound in every dimension for the specified class of convex bodies |
| 9 | Multicolor Ramsey numbers | Proves a superexponential lower bound for multicolor triangle Ramsey numbers and resolves Erdős problem 183 |
| 10 | Extremal graph theory | Produces constructions disproving compactness and degeneracy conjectures associated with Erdős problems 146 and 180 |
These are not routine olympiad exercises. Several concern questions that had remained open for many years and require deep specialist knowledge to assess.
OpenAI also released a 62-page document titled How the Ideas Came Together: Mathematical Discovery Notes.
A proof answers:
Why is the theorem true?
A discovery record attempts to answer:
How did the system find this argument?
Those are different questions.
The walkthroughs can help researchers judge whether the model recombined known ideas, identified an analogy, searched broadly, found a new construction, or used a known theorem in an unexpected way.
They should still be treated carefully. A model-generated narration is not necessarily a perfect causal log of every internal computation.
The official openai/ten-proofs repository contains one Lean module for each result.
The project uses:
Lean 4.32.0
mathlib
Lake
With elan installed, the official README instructs users to build all ten formalizations with:
lake exe cache get
lake build All
An individual module can be built separately:
lake build SpherePacking
The repository includes:
SpherePacking.lean
MetricCodes.lean
NonSoficGroup.lean
ConnesRigidity.lean
Permanent.lean
QuantumParallelRepetition.lean
GapCVP.lean
EhrhartVolumeInequality.lean
MulticolorTriangleRamsey.lean
CompactnessAndDegeneracy.lean
The code is published under the Apache 2.0 license and includes independent-checking resources.
Lean is an interactive theorem prover based on dependent type theory.
A proof accepted by Lean’s kernel establishes that the formal theorem follows from the definitions, assumptions, imported axioms and libraries, and the formal proof term.
This rules out many errors that can appear in informal arguments:
The certificate can be checked mechanically rather than accepted because an author sounds convincing.
Formal verification does not remove every review problem.
A theorem prover checks the encoded statement. Humans must still determine whether it accurately captures the mathematical problem.
Lean verifies consequences of formal definitions. It does not decide whether those definitions reflect the accepted concept or whether a hidden assumption weakens the headline result.
Formal correctness does not establish novelty. Literature review and expert knowledge remain necessary.
A machine can verify that a theorem follows. It cannot settle whether the result changes the field or introduces a valuable idea.
Two formally correct proofs may differ greatly in explanatory value. One may expose a reusable principle; another may be difficult for humans to internalize.
Formal checking addresses correctness. Mathematical understanding remains a separate task.
Less than one day after the OpenAI announcement, Alpöge wrote that he had “half of them with Fable.”
He described the setup as:

Alpöge later identified the five items as numbers 4 through 8.
| OpenAI item | Topic | Public status of the Fable claim |
|---|---|---|
| 4 | Connes’s rigidity conjecture | Claimed reproduction |
| 5 | Arithmetic circuit complexity | Claimed reproduction |
| 6 | Quantum parallel repetition | Claimed reproduction |
| 7 | Closest vector problem | Claimed reproduction |
| 8 | Ehrhart’s volume conjecture | Claimed reproduction |
Alpöge said the Ehrhart result was the only one where Astra and Fable appeared to use essentially the same argument.
If accurate, the other four may be alternative proofs rather than reconstructions of OpenAI’s route.
For OpenAI’s ten results, the public package includes theorem statements, full manuscripts, reasoning walkthroughs, Lean source code, build instructions, and independent-checking resources.
For the Fable five, I could verify Alpöge’s statement, the named problem numbers, his stated experimental conditions, and his observation about the Ehrhart argument.
I could not verify a public package containing:
The responsible description is:
An Anthropic researcher publicly reported that Fable 5 independently completed five of the ten problems under controlled conditions, but the detailed evidence required for full independent assessment was not yet publicly available during verification.
This does not prove the claim is false. It means the claim has not reached the same evidentiary stage as OpenAI’s published package.
Even with that caveat, the timing is notable.
In traditional mathematics, a major new result may take months or years to be independently reconstructed.
Researchers first need to learn the background, read the manuscript, check technical details, rebuild the argument, try alternatives, discuss concerns, and publish a review or follow-up paper.
A capable model can compress parts of that process.
If one model’s result can be independently reached by another in a day, the priority window for AI-generated discoveries may become much shorter.
The first group still deserves credit for choosing the problem, producing the first public argument, preparing the manuscript, formalizing the result, and creating a record others can inspect.
However, the competitive advantage of being first may last for days rather than years when other researchers can immediately assign similar problems to frontier systems.
Most model benchmarks compare systems on questions with known answers.
A benchmark asks:
Given the same test set, which model scores higher?
This episode asks something different:
Can two systems independently reach the same new frontier result?
That resembles scientific replication.
Independent replication can reveal whether a result depends on one model’s mistake, one fragile prompt, leaked information, or one unusual proof route.
Two independent arguments can increase confidence, especially when they use different ideas.
They still need review.
Two models may share similar training sources, mathematical misconceptions, optimization biases, or hidden assumptions.
Model independence is not automatically epistemic independence.
A credible replication package should disclose enough information for others to repeat the experiment.
Without this information, “independent reproduction” remains difficult to distinguish from a promising preliminary report.
Anthropic launched Claude Fable 5 in June 2026.
Anthropic describes it as a Mythos-class model made available for general use with safeguards.
The company says the model is especially strong on long-running autonomous work, software engineering, knowledge work, vision, scientific research, and long-context tasks.
The official API model identifier is:
claude-fable-5
Anthropic’s published price is:
$10 per million input tokens
$50 per million output tokens
Fable’s public availability is relevant to the mathematics story.
Astra remains an internal, unreleased OpenAI model.
Fable can be accessed by researchers and developers through supported Anthropic products and the API.
That makes it easier for outside groups to attempt their own research problems, although model access does not guarantee the expertise required to choose good questions or validate the outputs.
OpenAI states that the total number of tokens needed to find the ten solutions would cost roughly $2,000 at Sol API rates.
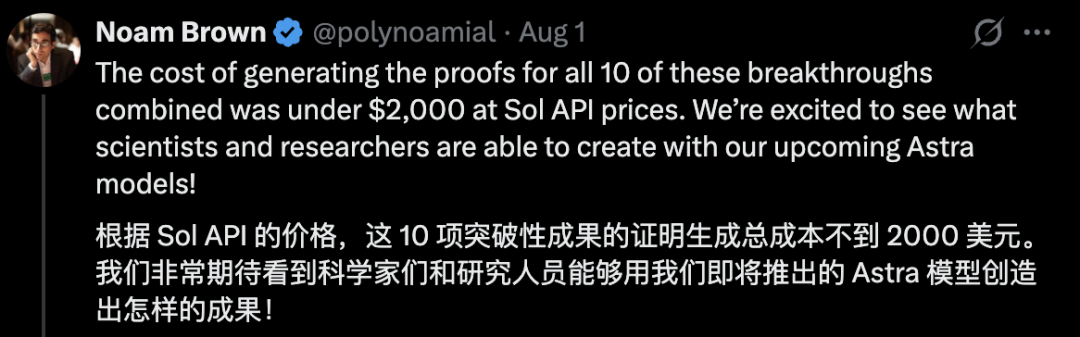
The number is remarkable, but it needs a precise label.
It is best understood as an estimate of the successful solution-finding token cost.
It is not the total economic cost of the research program.
The larger cost stack may include:
OpenAI says it tried other major problems without success and did not solve any Millennium Prize Problems.
The $2,000 estimate therefore answers:
What would the successful search tokens cost at a published API rate?
It does not answer:
What did it cost to create the model and produce, validate, and publish the research?
Both numbers are useful, but they measure different things.
Even after overhead is included, a low marginal cost for another serious attempt can change how research is conducted.
A human mathematician may spend weeks deciding whether one route is worth pursuing.
An AI system can be asked to explore many routes in parallel.
Researchers may use models to:
The effect may resemble high-throughput experimentation in other sciences.
When the cost of trying another hypothesis falls, the number of hypotheses tested rises.
The scarce resource moves toward selecting promising questions and evaluating the resulting flood of candidates.
Success-only cost accounting can create a misleading picture.
Suppose a system is assigned 100 open problems and solves ten.
The cost per successful solution should include the resources spent on the 90 failures if the objective is to measure the economics of the full search program.
A complete accounting should report:
Total inference cost
÷
number of validated results
It should distinguish successful final runs, failed complete runs, partial progress, human-guided restarts, parallel candidates, and verification costs.
Without this denominator, a low figure can describe a selected success rather than discovery economics as a whole.
One criticism of the replication effort was straightforward:
Describe your idea once, and We0 AI can generate a showcase site, pages, and CMS, then help you attract customers and traffic after launch.
One complete project generation for free registration
Best for trying one complete generation flow and seeing a first project draft quickly.
Why ask Fable to redo Astra’s results instead of assigning new open problems?
Replication and discovery serve different purposes.
Replication tests reliability.
New-problem solving tests frontier capability.
Fable has also been connected to a new mathematical result.
In July 2026, Alpöge reported a counterexample to the Jacobian conjecture in dimension three, crediting Fable with a role in the discovery.
The counterexample was checked formally, discussed by mathematicians, and followed by additional work. An arXiv paper posted at the end of July gave a self-contained account and generalized the mechanism to higher dimensions.
That episode illustrates a recurring pattern:
The final stage may be where much of the enduring mathematical value appears.
An explicit counterexample can sometimes be checked quickly.
If a conjecture says no object with certain properties exists, one valid object is enough to disprove it.
The reviewer can verify:
A long general theorem may require hundreds of linked lemmas and a broad understanding of the literature.
This difference partly explains why AI-generated counterexamples can spread quickly.
The Jacobian example was compact enough for researchers to inspect and formalize rapidly.
Some of Astra’s ten results involve much longer chains of theory and may require more time for the community to absorb.
The central question is:
If AI can generate frontier proofs quickly, can the mathematical community verify them quickly enough?
A research result needs several forms of acceptance.
Does the proof follow from the assumptions?
Lean can help here.
Does the formal statement mean what the authors say it means?
Experts must check the translation.
Is the problem genuinely open, and is the result novel?
This requires literature knowledge.
Does the proof reveal a new idea or merely certify a fact?
This requires mathematical judgment.
Has the work been reviewed, discussed, corrected, and placed in context?
This takes time and institutional process.
AI can accelerate proof generation much faster than universities and journals can expand the population of experts qualified to review highly specialized work.
A strong coding model can be tested by asking it to build an application.
A strong image model can be judged visually.
Frontier mathematics is different.
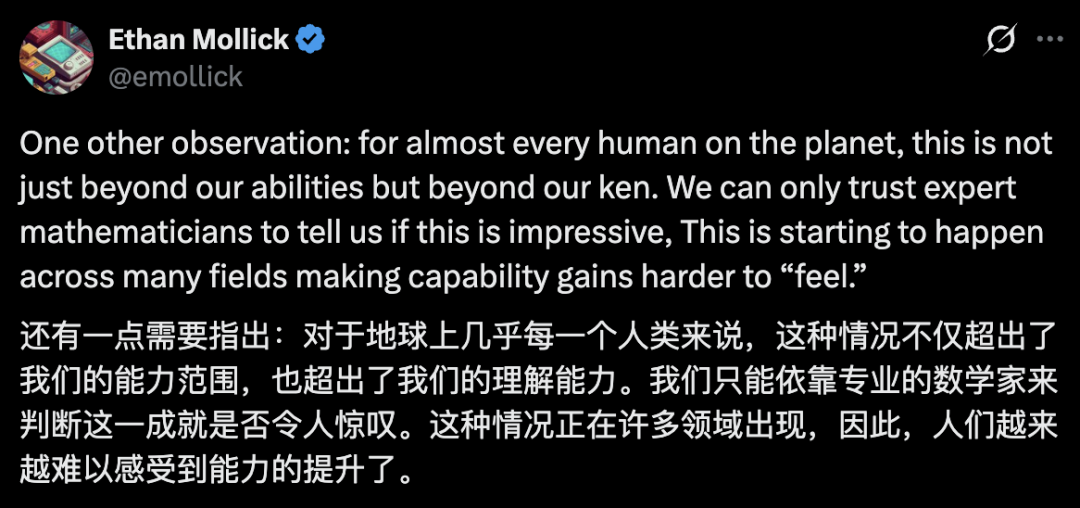
Most readers cannot personally evaluate the existence of non-sofic groups, a counterexample to Connes’s rigidity conjecture, an entangled-game parallel-repetition theorem, or lattice hardness.
They depend on a trust chain:
Model output
→ formal certificate
→ proof assistant and libraries
→ domain experts
→ independent reviewers
→ journals and research community
That makes transparency more important, not less.
When the public cannot directly inspect a capability, confidence must come from evidence and institutions.
It is misleading to describe the episode as AI replacing mathematics in isolation.
The models rely on:
Astra’s Lean certificates are possible because a large community has spent years formalizing mathematical foundations and building reusable libraries.
The model’s achievement is real.
So is the human infrastructure supporting it.
A more honest description is:
Frontier models are becoming powerful participants inside a mathematical knowledge system built and maintained by people.
A proof can be correct without being illuminating.
Mathematicians often value a result because it introduces a new invariant, construction, reusable method, connection between fields, simpler explanation, or better question.
When an AI produces a long proof, reviewers may ask:
This is the difference between certifying a theorem and integrating it into human mathematics.
The volume of correct results matters.
The ability to turn those results into understanding may matter more.
If proof search becomes cheaper, problem selection may become a larger part of the research advantage.
The hardest decisions may be:
These are questions of mathematical taste.
A model may help generate questions, but the current research ecosystem still relies heavily on experts to identify which questions are meaningful.
Traditional peer review assumes a relatively small number of manuscripts.
AI could produce far more candidate results than existing journals can process.
The review process may need new layers.
Every result suitable for formalization should include a machine-checkable certificate.
Prompts, model versions, tool access, and run conditions should be archived.
Systems should compare new claims against papers and theorem databases.
A different model or research group can attempt the same problem without seeing the proposed proof.
Specialists identify which results deserve deep review.
Correct proofs are converted into forms humans can learn from.
Open repositories allow errors, simplifications, and alternative arguments to be documented continuously.
This does not eliminate journals or experts. It gives them better tools for handling a higher volume of work.
The Leiden Declaration on Artificial Intelligence and Mathematics calls for responsible use of AI in mathematical research.
Its concerns include:
OpenAI’s publication addresses some of these issues unusually directly.
It attributes the mathematical arguments to the model, explains the role of humans in manuscript preparation, publishes formal certificates, and invites community review.
Questions remain:
These are no longer hypothetical policy questions.
They now apply to real research outputs.
Distinguish:
Look for hidden assumptions, circular reasoning, unexplained transitions, incorrect citations, scope changes, and ambiguous notation.
Confirm that the Lean theorem faithfully expresses the intended mathematics.
For OpenAI’s repository:
git clone https://github.com/openai/ten-proofs.git
cd ten-proofs
lake exe cache get
lake build All
Check imported modules, axioms, placeholders, unsafe declarations, custom definitions, and trusted external code.
A formal proof may establish the theorem through a route that differs from the manuscript.
Give the theorem statement—but not the proposed proof—to another model or research group.
Confirm novelty and identify overlapping work.
A correct result should be followed by conceptual questions:
The claim would become substantially stronger if Alpöge or Anthropic publishes:
The most interesting outcome would not necessarily be five identical proofs.
Four genuinely different arguments could be more valuable because they might reveal alternative structures behind the same results.
OpenAI has publicly provided:
This does not substitute for peer review.
It does create a serious, inspectable research package.
The burden has moved from “show us the evidence” to “evaluate a very large body of evidence.”
Fable’s reported response suggests that frontier research capability may diffuse faster than model releases.
A company can keep a model private.
It cannot assume that a mathematical result produced by that model will remain exclusive for long after publication.
Once a theorem statement is public, other capable systems can attack it immediately.
Organizations may therefore choose to publish complete evidence quickly, formalize before announcing, invite independent replication, and coordinate with domain experts before publicity.
Priority will still matter.
The evidence package surrounding the priority claim may matter just as much.
OpenAI published ten results in mathematics and theoretical computer science, including work on sphere packing, coding theory, non-sofic groups, Connes’s rigidity conjecture, arithmetic circuits, quantum parallel repetition, lattice hardness, Ehrhart’s volume conjecture, Ramsey numbers, and extremal graph theory. OpenAI describes them as results that resolve or substantially advance long-standing open problems.
No. OpenAI describes Astra as an internal version of its next major model. The papers, reasoning walkthroughs, and Lean certificates are public, but the Astra model used to generate the arguments has not been released.
Anthropic researcher Levent Alpöge publicly said Fable completed problems 4–8 within 24 hours under autonomous, offline conditions. During verification, complete manuscripts, logs, prompts, and Lean certificates for those five runs were not publicly located, so the claim should be treated as preliminary until fuller evidence is released.
Alpöge identified Connes’s rigidity conjecture, arithmetic circuit complexity, quantum parallel repetition, the closest vector problem, and Ehrhart’s volume conjecture. He said the Ehrhart result appeared to use essentially the same argument as Astra, while the other four may differ.
OpenAI published Lean 4 formalizations for all ten results, together with build instructions and independent-checking resources. A compiling Lean certificate verifies the formal theorem, but experts must still confirm that the encoded statement faithfully matches the intended mathematical claim.
OpenAI says the tokens needed to find the successful solutions would cost roughly $2,000 at Sol API rates. That estimate does not include model training, failed research attempts, human manuscript work, infrastructure, formalization, or external mathematical review.
Lean certificates allow a small trusted kernel to mechanically verify that a formal theorem follows from its assumptions and dependencies. They reduce the risk of hidden logical gaps, but they do not establish novelty, importance, or the faithfulness of the translation from informal mathematics.
The current evidence supports a change in mathematical work rather than a simple replacement claim. Models can accelerate search, proof generation, counterexample discovery, and formalization, while humans remain essential for problem selection, interpretation, literature context, review, and turning proofs into understanding.
OpenAI has released an unusually complete research package around ten Astra-generated advances: a 249-page manuscript, detailed discovery walkthroughs, and ten Lean formalizations that outside researchers can rebuild.
Claude Fable 5’s reported completion of five of the same problems within 24 hours could represent a new form of model-assisted replication. The claim is significant, but its public evidence currently falls short of OpenAI’s full manuscripts and formal certificates, so it should remain explicitly qualified.
The $2,000 estimate is best understood as the successful solution-search token cost at Sol API rates, not the total cost of the research program. Training, failures, human preparation, formalization, infrastructure, and review remain part of the real economics.
The larger shift is from proof scarcity to review scarcity. Models may soon generate mathematical claims faster than experts can verify, interpret, and place them in context.
When proofs become cheap to produce, the most valuable work may be deciding which proofs are correct, meaningful, new, and worth understanding.
Start from one sentence and have a complete website in minutes.



