Tencent Hunyuan has released Hy ASR 3.0 Preview , a new real-time speech-recognition model built around the language-understanding capabilit...
Tencent Hunyuan has released Hy ASR 3.0 Preview, a new real-time speech-recognition model built around the language-understanding capabilities of Hy3.
The model is designed to move automatic speech recognition beyond isolated acoustic decoding.
Traditional ASR systems mainly answer this question:
Which sequence of words most closely matches this audio?
Hy ASR 3.0 adds a second question:
Which transcription makes the most sense in this context?
That difference matters when the audio contains:
Tencent says the model combines a high-accuracy acoustic system with the contextual modeling and semantic reasoning of Hy3. Its goal is not to rewrite what the user said creatively, but to use linguistic context to choose a more plausible transcription when the audio alone is ambiguous.
The company reports word error rates of 3.34% for Mandarin Chinese, 2.62% for English, and 3.12% for Cantonese on aggregated public evaluation sets.
Hy ASR 3.0 Preview is now documented as a Tencent Cloud real-time WebSocket engine and has also been integrated into Tencent’s Yuanbao assistant. WorkBuddy and other Tencent products are being connected gradually.
The public Preview is useful, but it is not yet the finished product described in the broader launch announcement. Its present API limits are important for anyone planning a production integration.
Tencent evaluated Hy ASR 3.0 Preview on several public speech datasets and compared it with other ASR systems.
The company reports the following aggregated word error rates:
| Language or speech variety | Hy ASR 3.0 Preview WER |
|---|---|
| Mandarin Chinese | 3.34% |
| English | 2.62% |
| Cantonese | 3.12% |
Lower WER is better.
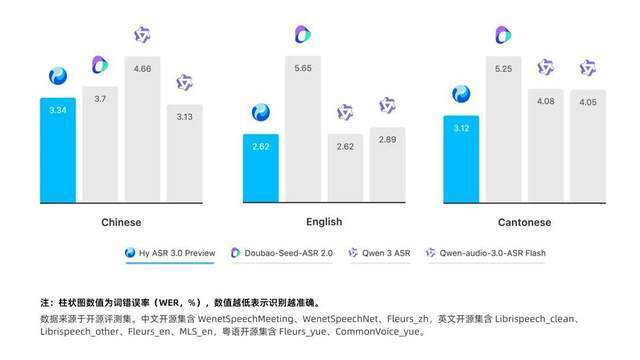
The chart’s notes indicate that the aggregate evaluation draws from datasets such as:
An aggregate number is useful for a broad comparison, but it can conceal important variation.
A model may perform differently on:
A production team should therefore test its own audio rather than selecting an ASR model from one headline WER number.
Word Error Rate is commonly defined as:
WER = (Substitutions + Deletions + Insertions) / Reference words
The three error types are:
A lower WER usually indicates a more accurate transcript.
However, WER does not capture every practical failure.
Consider two one-word errors:
“Ship the order tomorrow”
→ “Ship the order today”
and:
“The color is navy blue”
→ “The colour is navy blue”
Both may produce a similar error count, but the first can change a business action while the second may have no operational effect.
For customer service, healthcare, finance, manufacturing, and command interfaces, teams should evaluate semantic impact as well as WER.
Tencent also published results from internal evaluation sets covering four practical categories:
The reported results are:
| Internal evaluation category | Hy ASR 3.0 Preview WER |
|---|---|
| General recognition | 4.95% |
| Dialect recognition | 9.31% |
| Context evaluation | 4.76% |
| Complex acoustic conditions | 6.36% |
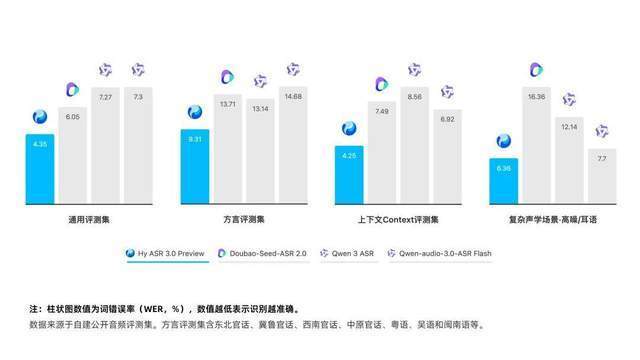
Tencent reports that Hy ASR 3.0 Preview achieved the lowest WER among the compared systems in all four internal categories.
These results are useful as company-reported product evidence, but the internal test sets are not a neutral public benchmark.
Before adoption, an organization should ask:
Tencent groups the practical improvements into four areas.
The model is intended to improve recognition across:
Tencent also says the model reduces accumulated errors in longer utterances.
That claim describes the model’s underlying capability. The current Tencent Cloud Preview still limits one public API input to 60 seconds, so applications working with meetings or recordings must currently segment the audio and manage cross-segment context themselves.
Poor segmentation can reintroduce the same problem the model is designed to reduce.
For example, cutting audio at an arbitrary 60-second boundary can split:
Chunking logic should therefore preserve sentence and voice-activity boundaries where possible.
Speech contains many ambiguous sounds.
Mandarin has numerous homophones. English has words and names that sound similar. Dialect pronunciation can make several candidate transcripts acoustically plausible.
A conventional decoder may choose the locally most likely word.
A context-aware system can evaluate the full utterance.
For example, a user may say a phrase that could be transcribed as two different homophones. Nearby words about finance, gaming, medicine, or travel can indicate which meaning is more likely.
The intended processing can be simplified as:
Audio features
→ candidate words
→ sentence context
→ semantic consistency check
→ final transcript
This does not mean the model literally understands speech in the same way a person does.
It means the language component uses a broader context window and semantic probabilities to improve the transcription decision.
A contextual ASR system also creates a new risk: semantic overcorrection.
The model may occasionally replace an unusual but correctly spoken phrase with a more common phrase that appears to make more sense.
Production evaluations should therefore include:
The objective is to use context without inventing speech that was never present.
The launch material highlights hotword enhancement for:
Hotwords can be valuable when a general model has not seen a rare term frequently enough.
Examples include:
A proprietary medicine name
A factory machine model
A customer account code
A newly launched brand
A technical abbreviation
Tencent Cloud’s general ASR product already has hotword-list APIs and a hotword_id parameter.
However, the current Hy ASR 3.0 Preview documentation explicitly says hotword enhancement is not yet open for this Preview engine.
The public product message and the currently accessible API should therefore be separated:
| Capability | Model announcement | Current Preview API status |
|---|---|---|
| Hotword enhancement | Described as supported capability | Listed as coming soon |
| Context input | Described as a major capability | Listed as coming soon |
| Internal contextual language modeling | Core model feature | Available through the model’s behavior |
Businesses should not design a launch plan that depends on external context injection or hotword lists until Tencent Cloud confirms support in the live API documentation.
Tencent says the model has been optimized for:
Noise robustness matters because real speech rarely arrives as a clean laboratory recording.
A customer-service microphone may capture keyboard sound and nearby agents.
A mobile assistant may hear traffic, wind, music, or another person speaking.
A meeting application may receive compressed audio from a distant laptop microphone.
A model can improve robustness, but it cannot recover information that was never captured.
Teams should still use:
ASR quality is a system property, not only a model property.
Tencent says Hy ASR 3.0 Preview combines three broad components:
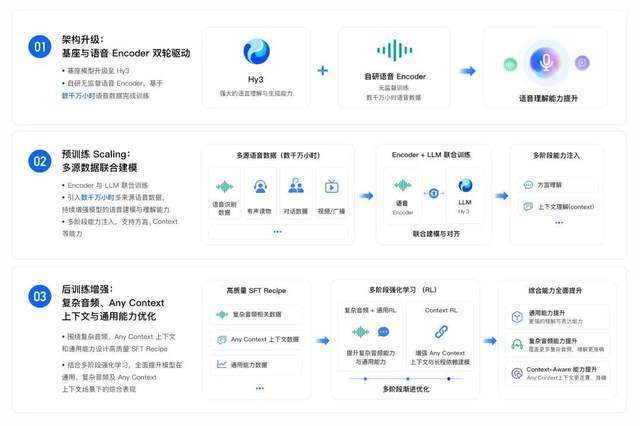
Hy3 provides the language-understanding component.
Its role includes:
Tencent describes the architecture as a Mixture of Experts design that balances capability and efficiency.
The public ASR documentation does not disclose the full parameter count, active-parameter count, latency profile, or complete inference architecture of Hy ASR 3.0 Preview.
The speech encoder transforms raw audio into acoustic representations that the language model can process.
Tencent says the encoder was trained on tens of millions of hours of unlabeled speech.
Unsupervised or self-supervised audio training is useful because manually transcribing that quantity of speech would be prohibitively expensive.
The encoder can learn recurring structure from raw audio, such as:
The quality of this representation affects everything that follows.
If two sounds are confused at the encoder stage, the language model must rely more heavily on context to recover the correct word.
Tencent says the speech encoder and language model were jointly trained using large, multi-source speech datasets covering:
Joint training is intended to reduce the gap between acoustic recognition and language understanding.
Instead of treating speech recognition as:
Audio model finishes
→ language model cleans the transcript afterward
Hy ASR 3.0 is presented as a more integrated process:
Speech representation and language modeling
→ trained to cooperate
→ one contextual transcription result
The exact internal boundary between encoder, decoder, language model, and reinforcement-learning stages has not been fully published.
Tencent describes a supervised fine-tuning recipe that covers:
The company also reports using multi-stage reinforcement learning for:
No public technical paper currently provides the complete reward design, data mixture, training compute, or ablation results.
The architecture claims should therefore be treated as a product-level technical description rather than a reproducible research specification.
Tencent Cloud documents the current Hy-ASR-3.0-preview engine as supporting:
The documented dialect list is:
| No. | Dialect or regional variety |
|---|---|
| 1 | Cantonese |
| 2 | Northeastern Mandarin |
| 3 | Henan dialect |
| 4 | Shaanxi dialect |
| 5 | Chengdu dialect |
| 6 | Chongqing dialect |
| 7 | Wuhan dialect |
| 8 | Guiyang dialect |
| 9 | Qingdao dialect |
| 10 | Jinan dialect |
| 11 | Changsha dialect |
| 12 | Hefei dialect |
| 13 | Hebei dialect |
| 14 | Kunming dialect |
| 15 | Lanzhou dialect |
| 16 | Yinchuan dialect |
| 17 | Nanchang dialect |
| 18 | Beijing dialect |
| 19 | Sichuan dialect |
| 20 | Tianjin dialect |
Dialect labels in commercial ASR documentation are broad product categories.
Real speech varies within each category by city, age, social background, code-switching, vocabulary, and speaker.
A claim of dialect support should not be interpreted as identical accuracy for every speaker in the region.
Tencent Cloud added the Hy ASR 3.0 Preview engine to the real-time WebSocket product on August 4, 2026.
The public service is currently described as an internal-test or Preview release.
| Item | Current documented status |
|---|---|
| Product type | Real-time speech recognition |
| Access method | Tencent Cloud WebSocket API |
| Engine name | Hy-ASR-3.0-preview |
| Audio duration | No more than 60 seconds per input |
| Audio format | 16 kHz mono PCM |
| Included concurrency | 20 concurrent routes |
| Mandarin | Supported |
| English | Supported |
| 20 dialects | Supported |
| Speaker separation | Not supported in the Preview |
| VAD parameter support | Listed as unsupported for the Preview |
| Word replacement | Not supported in the Preview |
| Noise-threshold parameter | Not supported in the Preview |
| External context input | Coming soon |
| Hotword enhancement | Coming soon |
The general WebSocket API reference contains parameters used by other engines, including VAD and hotword IDs.
The engine-specific Preview note takes precedence for Hy ASR 3.0.
A parameter appearing in the shared API schema does not guarantee that the Preview engine currently implements it.
The official setup has three main stages.
Open the Tencent Cloud speech-recognition service and complete the account activation process.
Describe your idea once, and We0 AI can generate a showcase site, pages, and CMS, then help you attract customers and traffic after launch.
One complete project generation for free registration
Best for trying one complete generation flow and seeing a first project draft quickly.
The official quick-start documentation is available at:
https://cloud.tencent.com/document/product/1093/54362
Review billing before enabling postpaid usage.
Tencent Cloud states that postpaid billing is disabled by default for newer accounts and must be turned on manually.
Create or obtain:
AppIDSecretIDSecretKeyThese credentials are used to sign the WebSocket connection request.
Store them in a secrets manager or protected environment variables.
Do not place long-lived credentials in:
For browser or mobile products, create the signed connection information on a trusted backend.
Tencent Cloud documents the endpoint format as:
wss://asr.cloud.tencent.com/asr/v2/?{request_parameters}
Replace `` with the Tencent Cloud AppID.
The request includes signed parameters such as:
secretidtimestampexpirednoncevoice_idengine_model_typeFor Hy ASR 3.0 Preview, set:
engine_model_type=Hy-ASR-3.0-preview
Each WebSocket connection needs a unique voice_id.
If the connection ends or fails, the old voice_id becomes invalid and a new one must be generated.
The current Preview requires:
Sample rate: 16 kHz
Channels: mono
Format: PCM
Maximum input duration: 60 seconds
Test the complete audio path, not only the original file.
Microphone SDKs, browser media APIs, telephony systems, and conferencing platforms may resample or compress audio before it reaches the server.
The service supports real-time transcription, returning text while audio is being transmitted.
Applications should handle:
Do not assume that every partial token is final.
A real-time ASR interface may revise earlier words when more context becomes available.
The user interface should distinguish temporary text from committed text.
Build a representative evaluation set containing:
Measure both recognition quality and system behavior.
Tencent Cloud classifies Hy ASR 3.0 Preview as a Large Model 2.0 real-time speech-recognition engine.
The current billing page lists:
| Billing option | Current listed price |
|---|---|
| Prepaid 60-hour package | RMB 60 total, or RMB 1.00/hour |
| Prepaid 1,000-hour package | RMB 950 total, or RMB 0.95/hour |
| Prepaid 10,000-hour package | RMB 9,000 total, or RMB 0.90/hour |
| Prepaid 100,000-hour package | RMB 88,000 total, or RMB 0.88/hour |
| Prepaid 300,000-hour package | RMB 255,000 total, or RMB 0.85/hour |
| Postpaid | RMB 1.00/hour, daily settlement |
Tencent’s billing table currently lists no free audio quota for Large Model 2.0 recognition.
The 20 included concurrent routes are a concurrency allowance, not free recognition time.
Pricing can change. Check the live billing page before publishing a commercial quote or estimating a long-term budget.
At the currently listed RMB 1.00 per hour postpaid rate:
100 hours of successful recognition
× RMB 1.00/hour
= RMB 100
A production budget should also include:
The ASR fee is only one part of the complete transcription system.
Tencent says Yuanbao participated in the model’s development and was the first Tencent product to integrate it.
Users can access the experience through voice input in Yuanbao, where the model is intended to improve:
Tencent says WorkBuddy and other products are being connected gradually.
A consumer-product integration may expose capabilities differently from the public Tencent Cloud Preview API.
For example, Yuanbao may use internal services, product-specific context, or deployment configurations that are not yet exposed to external developers.
An experience in Yuanbao should not be assumed to map one-to-one to public API parameters.
Hy ASR 3.0 Preview is positioned for short, low-latency voice interactions.
Potential uses include:
The current lack of speaker separation in the Preview may limit multi-speaker call transcription unless another component separates channels or speakers.
The engine can support short real-time captions for:
Applications should test partial-result stability and punctuation behavior.
Context-aware recognition can improve searches involving:
Until hotword injection opens for the Preview, rare catalog terms may still need post-processing or a separate correction layer.
The engine can convert spoken instructions into text for:
A command system should never execute high-impact actions solely because one transcript appears confident.
For destructive or financial operations, confirm the parsed intent and require explicit user approval.
Short audio segments can be transcribed before being sent into:
The quality of every downstream AI step depends on the transcript.
Store the original audio or confidence evidence where policy permits so uncertain outputs can be reviewed.
The product is still labeled Preview or internal test.
Interfaces, pricing, limits, and supported functions may change.
The current public API is not a direct replacement for batch transcription of long recordings.
Long audio requires segmentation and possibly an application-level context layer.
The Preview currently requires 16 kHz mono PCM.
Many production sources use MP3, AAC, Opus, or telephony codecs and will need conversion.
The current engine-specific documentation says speaker separation is not supported.
Multi-speaker transcripts may require separate audio channels or another diarization service.
The announced capabilities are not yet exposed as usable Preview API features according to the official documentation.
The benchmark charts come from Tencent.
Independent evaluation on matched settings would strengthen the comparison.
Tencent has described the architecture and training process at a high level but has not published full reproducible details for Hy ASR 3.0 Preview.
A language-aware decoder may prefer a common sentence over an unusual but correctly spoken one.
Rare and surprising phrases must be included in testing.
Include at least several hundred representative utterances rather than a handful of clean demos.
Create human-verified reference transcripts using a clear normalization policy.
Decide how to treat:
Use:
Do not combine all dialect speakers into one average.
Report results by region and recording condition.
Create pairs where acoustic content is similar but sentence context changes the correct transcription.
Evaluate product names and technical terms now, then repeat the test after Tencent opens hotword support.
Use real environmental recordings rather than only digitally added noise.
Confirm that the 60-second implementation does not cut important phrases or create duplicated text.
Include:
Capture
+ upload
+ recognition
+ finalization
+ downstream processing
Voice recordings may contain personal or sensitive information.
Define retention, access, encryption, consent, and deletion policies before deployment.
| Area | Traditional pipeline | Hy ASR 3.0 direction |
|---|---|---|
| Main focus | Acoustic-to-text accuracy | Acoustic recognition plus contextual language modeling |
| Ambiguous homophones | Often decided from local probabilities | Uses broader sentence context |
| Dialects | Separate models or limited coverage | One documented mixed engine with 20 dialects |
| Professional vocabulary | External hotword or custom model | Hotword capability announced; Preview support pending |
| Complex speech | Acoustic model and post-processing | Joint speech-language training plus post-training |
| Output | Transcript | More contextually coherent transcript |
| Main risk | Acoustic substitutions and omissions | Acoustic errors plus possible semantic overcorrection |
The newer approach does not remove the need for traditional ASR engineering.
It adds a stronger language layer to the same end-to-end system.
Hy ASR 3.0 Preview is Tencent Hunyuan’s real-time speech-recognition model based on the Hy3 language foundation and a self-developed speech encoder. It is designed to combine acoustic recognition with contextual language understanding.
Tencent Cloud documents support for Mandarin Chinese, English, and 20 Chinese dialects or regional varieties, including Cantonese, Northeastern Mandarin, Henan, Shaanxi, Chengdu, Chongqing, Wuhan, and others. Accuracy can vary across speakers and regions.
Tencent reports aggregated public-benchmark WER values of 3.34% for Mandarin, 2.62% for English, and 3.12% for Cantonese. These are company-reported results across several datasets rather than one independently reproduced universal test.
The current public Preview accepts no more than 60 seconds of audio per input. Longer recordings require segmentation, and the application must preserve useful context across segments.
Not yet, according to Tencent Cloud’s Preview documentation dated August 4, 2026. The launch material describes these capabilities, but the official API page says context input and hotword enhancement will open later.
The current Hy ASR 3.0 Preview documentation specifies 16 kHz mono PCM input. Applications using MP3, AAC, Opus, or another format must convert the audio before sending it to this engine.
Developers use Tencent Cloud’s real-time speech-recognition WebSocket API and set engine_model_type to Hy-ASR-3.0-preview. The connection must be signed with Tencent Cloud credentials.
Tencent Cloud’s current billing page lists no free audio quota for Large Model 2.0 recognition. It lists prepaid packages starting at RMB 1 per hour for 60 hours and postpaid usage at RMB 1 per hour, while 20 concurrent routes are included.
Tencent Hunyuan’s Hy ASR 3.0 Preview combines a speech encoder with Hy3’s language-model capabilities to improve Mandarin, English, dialect, mixed-language, noisy, and context-dependent transcription.
Tencent reports WER values of 3.34% for Mandarin, 2.62% for English, and 3.12% for Cantonese on aggregated public datasets, along with leading results on its internal scenario tests. These figures are promising but should be validated on each organization’s own audio.
The current Tencent Cloud Preview is narrower than the complete launch vision. It supports real-time WebSocket recognition, 16 kHz mono PCM, and audio inputs of up to 60 seconds. External context injection, hotword enhancement, speaker separation, and several other functions are not yet available for this engine.
The key change is not that ASR has stopped listening to sound—it is that the language model now helps decide what the sound most plausibly means.
Start from one sentence and have a complete website in minutes.



