A little over a year after Lepton AI became part of NVIDIA, Yangqing Jia is starting again. His new company, Intent Lab, is not launching wi...
A little over a year after Lepton AI became part of NVIDIA, Yangqing Jia is starting again.
His new company, Intent Lab, is not launching with a conventional chatbot, cloud marketplace, or developer IDE. Instead, the company is building Fleet, which it describes as an autonomous engineering team that turns a high-level intent into production-grade software.
Intent Lab's first public demonstration includes three very different systems:
At first glance, the projects do not look like one product category.
That is the point.
Intent Lab says the actual product is the engineering system behind them. Fleet is intended to perform the work between a vague software request and a system that can be benchmarked, verified, operated, and evolved in production.
The early performance numbers in this article come from Intent Lab's own launch materials. They are promising demonstrations, not independent benchmark certifications. The company has not yet published enough reproducibility detail for outside teams to confirm every result under identical conditions.
Yangqing Jia's career has repeatedly returned to infrastructure.
He is best known for creating Caffe while at UC Berkeley and later working on major AI infrastructure efforts including PyTorch and ONNX.
After leaving Alibaba in 2023, Jia co-founded Lepton AI, a company focused on making GPU compute and model deployment easier for developers.
Lepton's original pitch combined a Python-native developer experience with infrastructure that could run AI workloads across multiple GPU providers.
The company was acquired by NVIDIA in 2025 in a deal publicly described at the time as worth hundreds of millions of dollars. Later industry reports placed the figure at roughly $700 million, although NVIDIA did not publish a final acquisition price.
Lepton's technology became part of NVIDIA DGX Cloud Lepton.
com/cms-assets/image/2026/07/32165d25-ec8e-45a4-8ec2-4b9895592d90-c88a130e-0f9f-4f13-a721-065d3cf997fc.png)
NVIDIA currently describes DGX Cloud Lepton as an active platform that unifies GPU compute across cloud providers and customer-owned infrastructure for development, training, and inference.
That current status is worth clarifying because commentary after Jia’s departure argued that the original startup-style Lepton product and its open-source ambitions did not survive the acquisition unchanged.
The public evidence supports a more careful description:
lep CLI remain available.Jia later served as NVIDIA’s vice president of system software before leaving the company in 2026.
In July 2026, Hyperbolic announced that Jia had joined the GPU-infrastructure company as an advisor.
Hyperbolic described his background across Caffe, ONNX, PyTorch, Lepton AI, NVIDIA, Google, Facebook, and Alibaba Cloud as particularly relevant to its work on GPU access and infrastructure.
That role turns out not to have been his main next move.
On July 29, Jia publicly introduced Intent Lab.
His framing was different from Lepton AI.
Lepton focused on giving developers easier access to compute.
Intent Lab is focused on giving an autonomous engineering system the ability to create and maintain the software that runs on that compute.
Jia summarized the shift by saying that his teams had spent their careers carefully building large systems one at a time. What interested them now was a system capable of producing many such systems.
Intent Lab calls its autonomous engineering system Fleet.
The company describes it as a team rather than a single coding agent.
The distinction matters.
A typical coding agent can edit files, run commands, fix tests, search a repository, and implement a feature.
Fleet is presented as a system that can coordinate a longer engineering process.
Intent Lab’s stated goal is to cover the work required to move from a high-level request to a production system with measurable
behavior, verification, and a path to continued improvement.
The first three demonstrations were chosen to test that claim across very different engineering domains.
The most technically striking launch result is a GLM-5.2 inference engine.
The initial instruction was essentially one engineering objective:
Re-engineer TensorRT-LLM so GLM-5.2 runs efficiently on Grace Blackwell nodes,
identify optimization opportunities, implement them, and verify them autonomously.
TensorRT-LLM is already NVIDIA's production-focused inference stack for large language models.
NVIDIA documents features such as multi-GPU and multi-node serving, in-flight batching, paged KV caching, quantization, optimized kernels, and Python and C++ runtimes.
Improving performance on top of that stack is therefore a more demanding target than optimizing an unoptimized reference implementation.
Intent Lab says Fleet began with stock TensorRT-LLM at approximately:
102 tokens/s
An optimized runtime reached:
161 tokens/s
After adding the company's optimized speculative-decoding path, the system reportedly reached:
647 tokens/s
That is approximately 6.3× the original output speed.
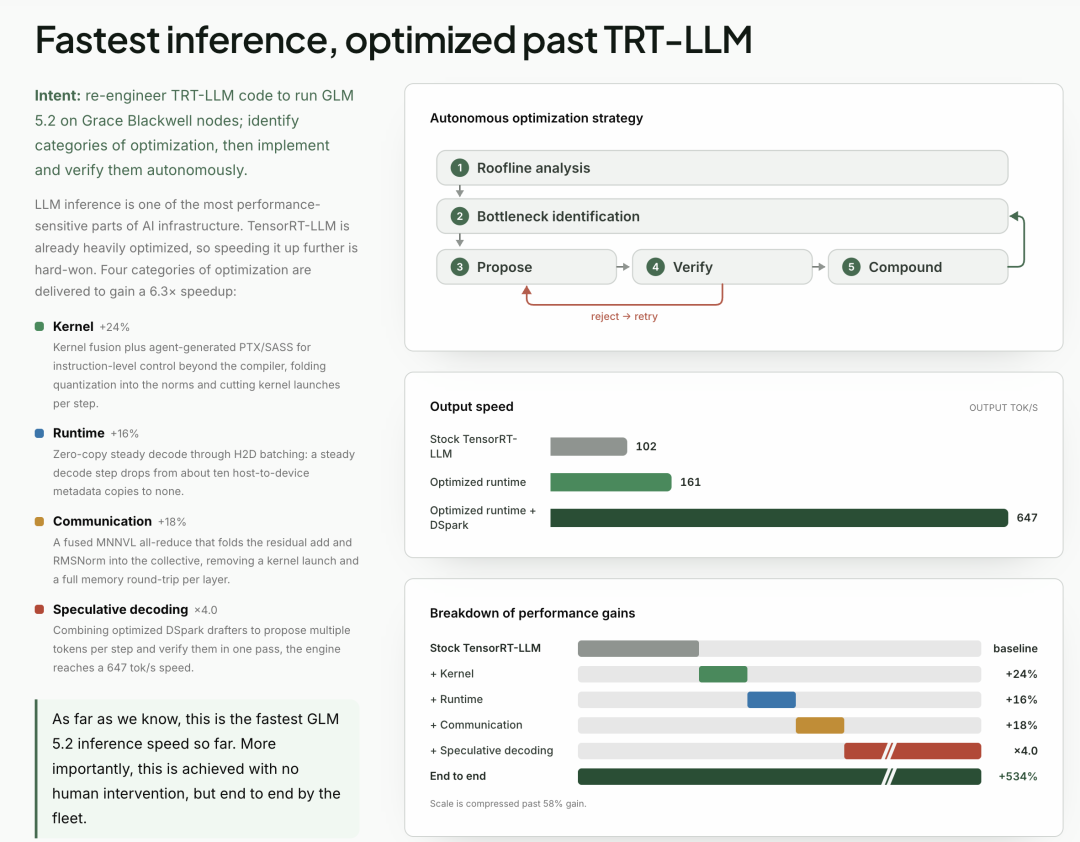
Intent Lab says the benchmark used two Grace Blackwell nodes.
The company breaks the performance work into four categories.
Fleet reportedly applied kernel fusion and generated low-level PTX/SASS paths for instruction-level control.
Intent Lab says the runtime removed repeated host-to-device metadata copies from steady-state decoding through H2D batching and zero-copy techniques.
Fleet reportedly used a fused MNNVL all-reduce path that incorporates residual addition and RMSNorm into the collective operation.
The largest individual gain came from speculative decoding.
Intent Lab says an optimized DSpark drafter proposes several tokens and the main model verifies them in batches, increasing decode throughput significantly.
The company reports the complete end-to-end result as a 534% improvement over its stock baseline.
These figures are Intent Lab's own measurements. Hardware configuration, workload details, batch settings, output length, precision, concurrency, and software revisions can materially affect inference benchmarks.
Intent Lab says Fleet follows a repeated engineering loop:
If a proposed optimization
fails validation, the system goes back and tries again.
The “compound” step matters because performance engineering often fails when individually successful optimizations interfere with one another.
Fleet is designed to retain changes only after verifying that the combined system still works.
GLM-5.2 is Z.ai’s flagship model for long-horizon tasks.
Its official model card highlights a one-million-token context window, long-horizon coding and agent workloads, flexible reasoning effort, an improved sparse-attention architecture, and open weights under the MIT license.
Large models with long context and agentic workloads create difficult serving problems.
The fastest implementation depends on interactions among kernel design, memory bandwidth, KV-cache behavior, interconnect bandwidth, batch size, speculative decoding, quantization, host scheduling, and communication collectives.
That makes inference optimization a useful stress test for an autonomous engineering system.
Fleet’s second public project moves away from GPU kernels entirely.
Intent Lab asked the system to build a SQL database engine that is compatible with SQLite.
The launch material shows a requirement equivalent to:
Build a SQL database engine that is compatible with SQLite,
in the sense that it can pass ALL sqllogictest test cases,
and performance must be comparable or better.
Intent Lab says Fleet did not start from SQLite’s source code or documentation.
Instead, it treated the existing system’s behavior and test corpus as the acceptance contract.
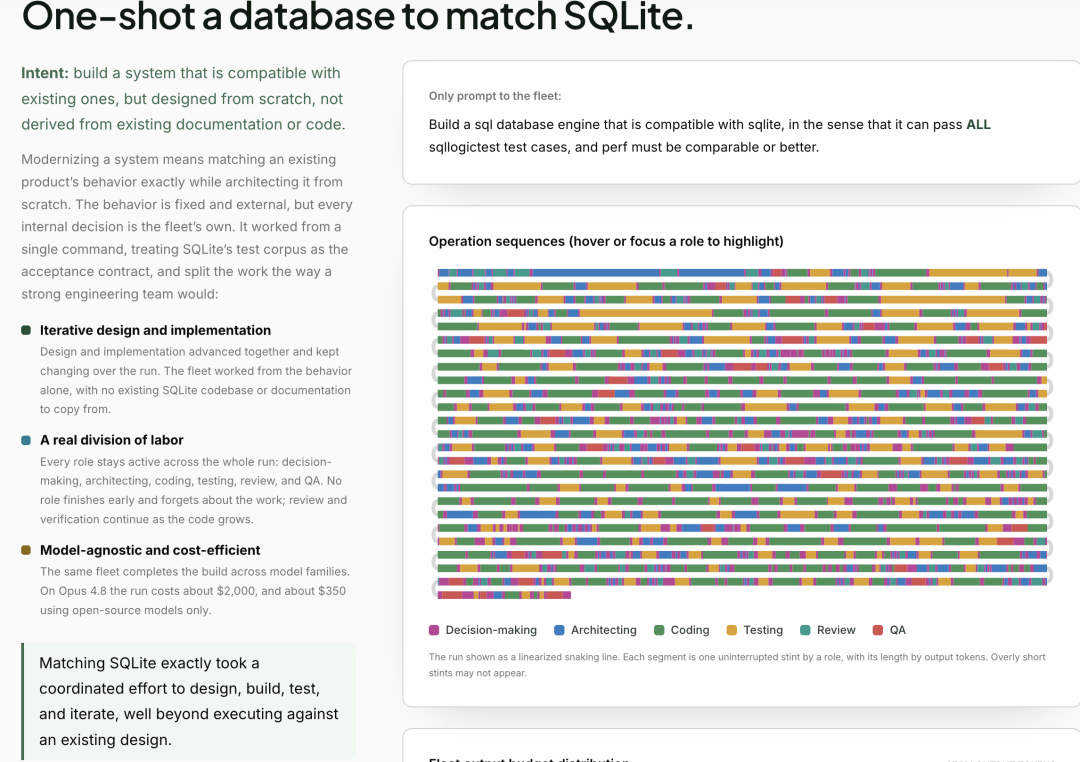
The company reports that the final system passed approximately six million SQLite compatibility tests.
That figure comes from Intent Lab and has not been independently reproduced for this article.
Intent Lab visualizes the database build as several roles working throughout the project:
The roles do not simply operate in a linear handoff.
Architecture can change while implementation proceeds. Testing continues while features are added. Review and QA remain active as the codebase grows.
Intent Lab also published a cost comparison.
For the same database build, the company says a run using Opus 4.8 cost roughly $2,000**, while a run using open-source models cost approximately **$350.
The numbers are company-reported and depend on model prices, token consumption, agent orchestration, and infrastructure.
They nevertheless illustrate a major economic question for agentic engineering: what is the cost of a complete successful project rather than the price of one model call?
Verified File System for Agents
The third demonstration is a distributed file system called AgentFS.
Intent Lab says it was designed specifically for agent workloads in cloud environments.
AI coding and research agents tend to create a distinctive storage pattern:
Intent Lab says it evaluated existing systems including Amazon EFS and S3FS, found limitations for this workload, and built a new file system instead.
The company claims significant speedups over the compared systems across metadata-heavy operations.
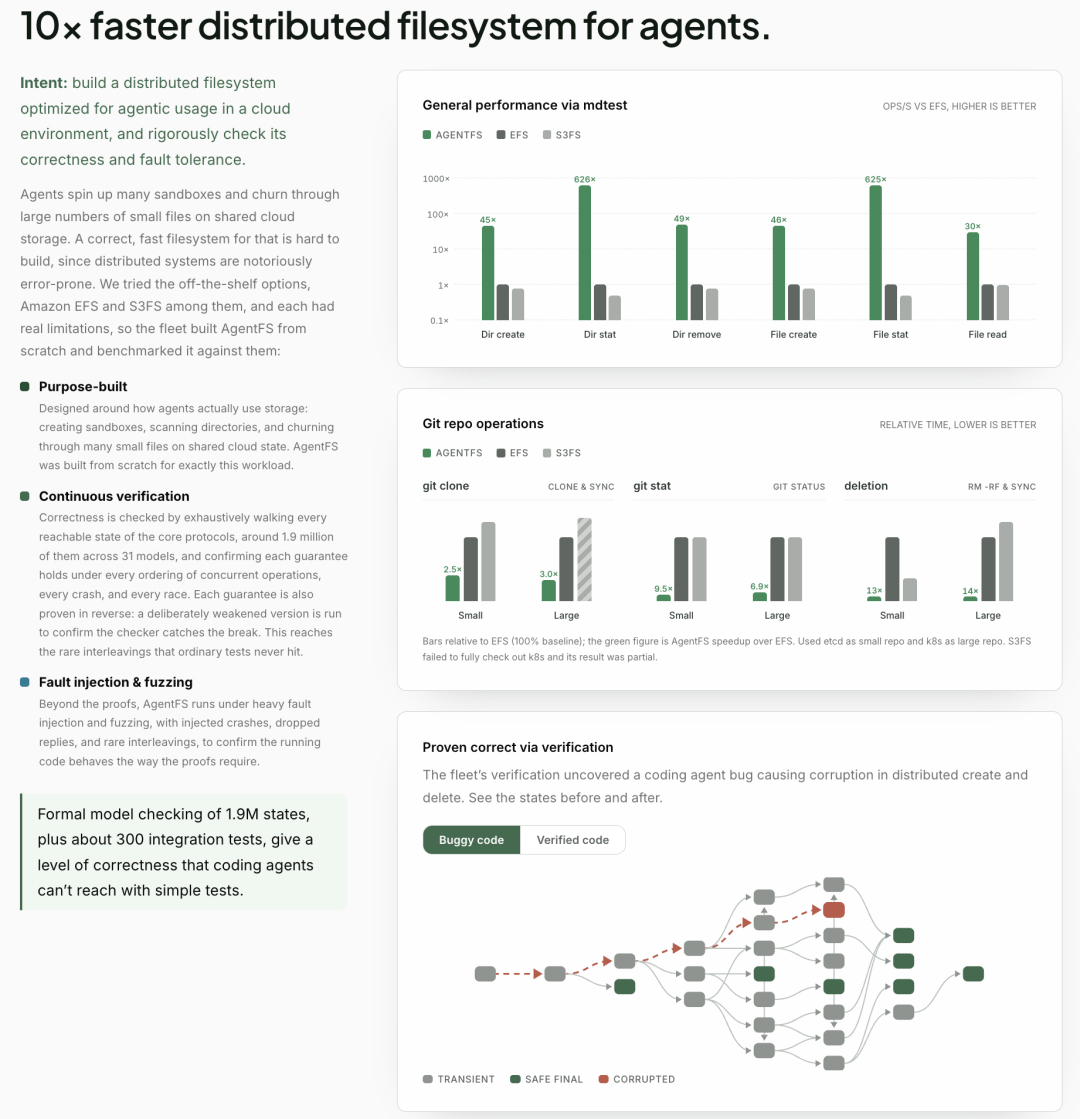
Again, these are Intent Lab's launch benchmarks, not independent third-party results.
The most important part of the file-system example is not the benchmark chart.
Describe your idea once, and We0 AI can generate a showcase site, pages, and CMS, then help you attract customers and traffic after launch.
One complete project generation for free registration
Best for trying one complete generation flow and seeing a first project draft quickly.
It is verification.
Intent Lab says Fleet formally modeled the core protocols and explored roughly 1.9 million states.
That process uncovered a bug in code produced by a coding agent.
The bug could lead to a transient corrupted state during distributed create/delete behavior.
Intent Lab says Fleet then fixed the implementation and re-ran the verification.
The company also reports approximately 300 integration tests, plus fault injection and fuzzing with injected crashes and replicas.
Formal verification is valuable here because file systems are particularly vulnerable to rare interleavings.
Traditional tests may show that the common path works. A model checker can systematically search combinations of states that ordinary test suites may never encounter.
This principle is well established outside Intent Lab. File-system researchers have used model checking for decades to expose crash-consistency and metadata bugs in mature systems.
The novel claim here is that an autonomous engineering system can incorporate this style of verification into its own build loop.
Jia's central argument is broader than any of the three demos.
Modern models can write code quickly.
That does not mean the result is software a company should operate for years.
He argues that the remaining gap is not simply another jump in model coding ability.
It is an engineering layer around the model.
A production system needs more than an implementation.
It needs requirements, architecture, interfaces,
trade-offs, coordination, testing, performance analysis, reliability work, verification, fault handling, maintenance, and feedback from production.
A coding model may participate in all of those activities.
Fleet’s thesis is that they need to be organized into one autonomous system.
Intent Lab describes its engineering process in six stages.
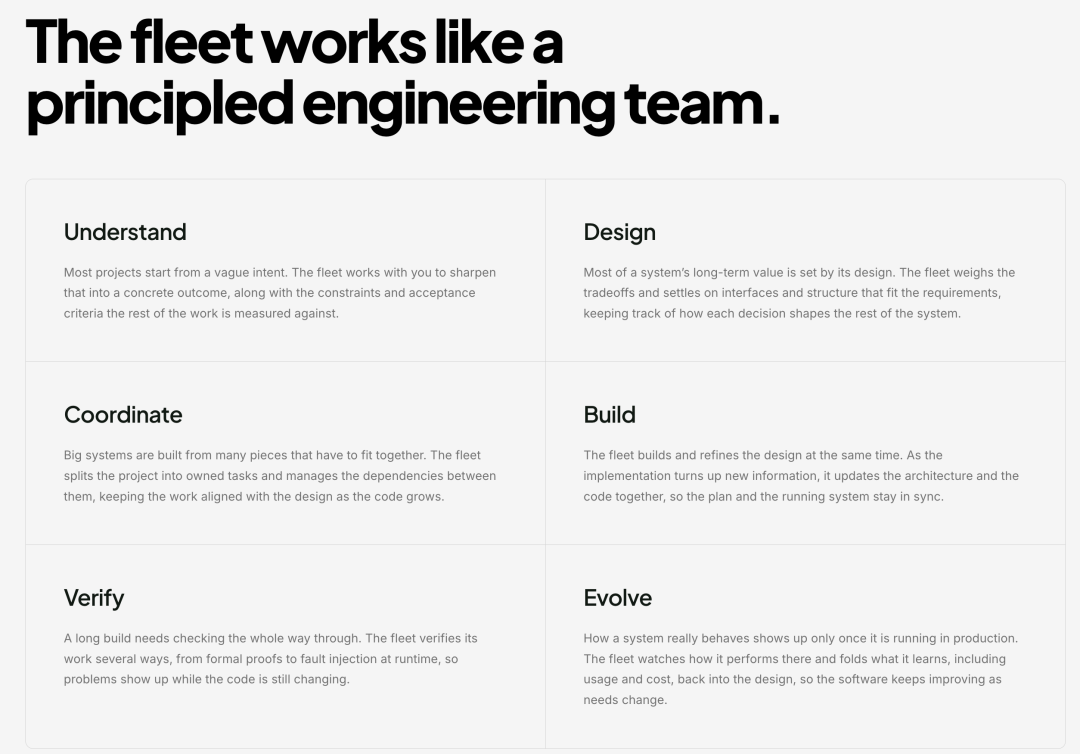
Fleet is supposed to turn vague intent into a concrete outcome, constraints, acceptance criteria, and measurable definitions of success.
Fleet weighs trade-offs and defines interfaces, components, and long-term system structure.
The system splits a large project into tasks, manages dependencies, and keeps implementation aligned with the overall design.
Implementation and architecture evolve together as new information appears during development.
Verification can include unit tests, integration tests, benchmarks, formal proofs, model checking, fault injection, fuzzing, and runtime validation.
Fleet is intended to observe production performance and feed information about usage, reliability, and cost back into the design.
This is the point where Intent Lab’s ambition extends beyond an autonomous coding agent.
The target is not only software generation.
It is autonomous software ownership.
Intent Lab describes Fleet as operating like a principled engineering team.
That is a useful metaphor because no one member of a strong engineering organization is responsible for every concern.
One engineer may optimize kernels. Another may design a storage protocol. Someone else maintains benchmarks. Another person reviews reliability.
Fleet attempts to turn those responsibilities into coordinated agent roles.
The hard question is therefore not only whether an LLM can write high-quality code.
It is whether multiple autonomous processes can maintain a coherent system architecture while building, testing, optimizing, verifying, and revising the same project over a long horizon.
Jia also makes an economic argument.
For decades, software development had a large fixed cost.
The rational strategy was to build one product, sell it to many users, and ask users with different needs to adapt to the same software.
If autonomous engineering reduces the fixed cost of building and maintaining a system, that equation changes.
oss-cn-beijing.aliyuncs.com/cms-assets/image/2026/07/dce27f23-7161-488d-aa67-f2ccc932be13-bdea7efd-b790-4fe7-97f2-e828d77b2750.png)
A company might be able to justify software for a smaller group of users.
An internal team could build a system for a workflow that would previously remain on a backlog for years.
An infrastructure group could create a specialized engine instead of accepting the limitations of a generic product.
Intent Lab says it plans to work with outside organizations on this type of project: systems with substantial engineering value that companies have postponed because the required work is too large.
The launch demos can easily be reduced to a viral headline:
One sentence created a database.
That framing misses most of the work Fleet claims to perform.
The database example starts with one requirement, but the system then carries out a long engineering process.
It must repeatedly make design decisions, generate code, run tests, diagnose failures, revise architecture, review behavior, and repeat.
The user provides a short intent.
The machine does not necessarily perform a short task.
A better evaluation asks how much human intervention was required, how much compute the run consumed, how many retries occurred, how well the result was verified, whether another team can reproduce it, and whether the system can be maintained after the demo.
Intent Lab's first results are ambitious, but the public material leaves important questions open.
The 6.3× inference result, SQLite test count, AgentFS performance, and formal-verification figures are company-reported.
Independent reproduction would make the claims substantially stronger.
Intent Lab has not publicly documented enough detail to reconstruct Fleet itself.
It is not yet clear which base models are used for each role, how agents share state, how tasks are scheduled, how conflicts are resolved, how specifications are stored, or how much human supervision remains available.
Building a benchmark-quality system is not identical to operating it for years.
The "Evolve" stage may be the hardest part of the thesis because a production owner must handle security patches, dependency changes, hardware shifts, incidents, cost changes, feature requests, and backward compatibility.
Autonomous engineering can be cheaper than a human team for some tasks while still consuming substantial inference and compute.
Intent Lab's own database example shows that model choice can change total project cost by several times.
Intent Lab is not simply another coding-agent startup.
Its thesis is closer to autonomous systems engineering.
The target unit of work is not a code completion or a pull request.
It is a production system.
That is why the first three examples look unrelated.
An inference engine, a database, and a file system share little at the product level.
They share an engineering pattern:
Intent
→ specification
→ architecture
→

Coordinated implementation
→ measurement
→ verification
→ iteration
→ production evolution
Fleet is intended to automate that pattern.
Whether it can do so reliably across many real companies remains an open question.
But the ambition is clear.
Intent Lab is a new AI infrastructure and autonomous engineering company co-founded by Yangqing Jia and other experienced systems engineers. Its first product, Fleet, is designed to turn high-level software intent into production-grade systems.
Fleet is Intent Lab's autonomous engineering system. The company describes it as a team of coordinated agents that can understand requirements, design architecture, build code, verify results, and continue evolving software after deployment.
Intent Lab reports that its optimized GLM-5.2 engine increased output speed from 102 tokens/s on stock TensorRT-LLM to 647 tokens/s on two Grace Blackwell nodes. The number is a company-reported benchmark and has not yet been independently reproduced in the sources reviewed here.
Intent Lab says the initial database requirement was a single prompt asking for a SQLite-compatible SQL engine. Fleet then autonomously performed architecture, coding, testing, review, and QA until the company says the system passed roughly six million compatibility tests.
AgentFS is a distributed file system created in Intent Lab's third launch demonstration. It is optimized for AI-agent workloads involving many sandboxes and small files, and Intent Lab says its core protocols were checked with formal model verification.
A normal coding agent typically works on code changes inside an existing project. Fleet is intended to coordinate a full systems-engineering lifecycle including requirement definition, architecture, implementation, performance work, formal verification, fault testing, and production evolution.
Intent Lab has publicly shared demonstrations and its product thesis, but the sources reviewed for this article do not show a public release of the complete Fleet orchestration system. Check Intent Lab's official site for the latest availability.
Yes. NVIDIA currently maintains product pages and documentation for DGX Cloud Lepton, including workloads, node groups, endpoints, Dev Pods, batch jobs, and bring-your-own-compute functionality. This is separate from debate over how closely the NVIDIA product preserved Lepton AI's original startup roadmap.
GLM-5.2: Z.ai's open-weight long-horizon model used in Intent Lab's inference-engine demonstration.
Yangqing Jia's new company, Intent Lab, is building Fleet around a different unit of AI work: not code generation, but the complete production-system lifecycle.
Its first demonstrations span GLM-5.2 inference optimization, a SQLite-compatible database, and a formally verified distributed file system. Intent Lab reports a 6.3× inference speedup, roughly six million database compatibility tests, and model checking across about 1.9 million file-system states.
The common idea is a six-stage engineering loop—Understand, Design, Coordinate, Build, Verify, and Evolve—that tries to reproduce the responsibilities of a strong engineering organization with autonomous agents.
The results are still early and largely self-reported, so reproducibility and long-term production operation remain the real tests.
Fleet's most important claim is not that AI can write code from one sentence; it is that an autonomous system can take responsibility for the engineering work between a sentence and software worth running for years.
Start from one sentence and have a complete website in minutes.



